
Accelerators
AI chips, local models, and the rumors around the next one.
AISIN's STT-MRAM SoC boots in 65.7 ms
A 16nm FinFET die from AISIN keeps its OS and Tiny YOLOv3 weights in on-chip STT-MRAM, eliminating the DRAM bus from the boot path. The kernel is up 65.7 ms after power-on.
AMD's April 2, 2025 MLPerf Inference v5.0 post reports the MI325X Llama 2 70B run
AMD's April 2, 2025 MLPerf Inference v5.0 post reports the MI325X Llama 2 70B run, but it leaves the November price unmeasured.
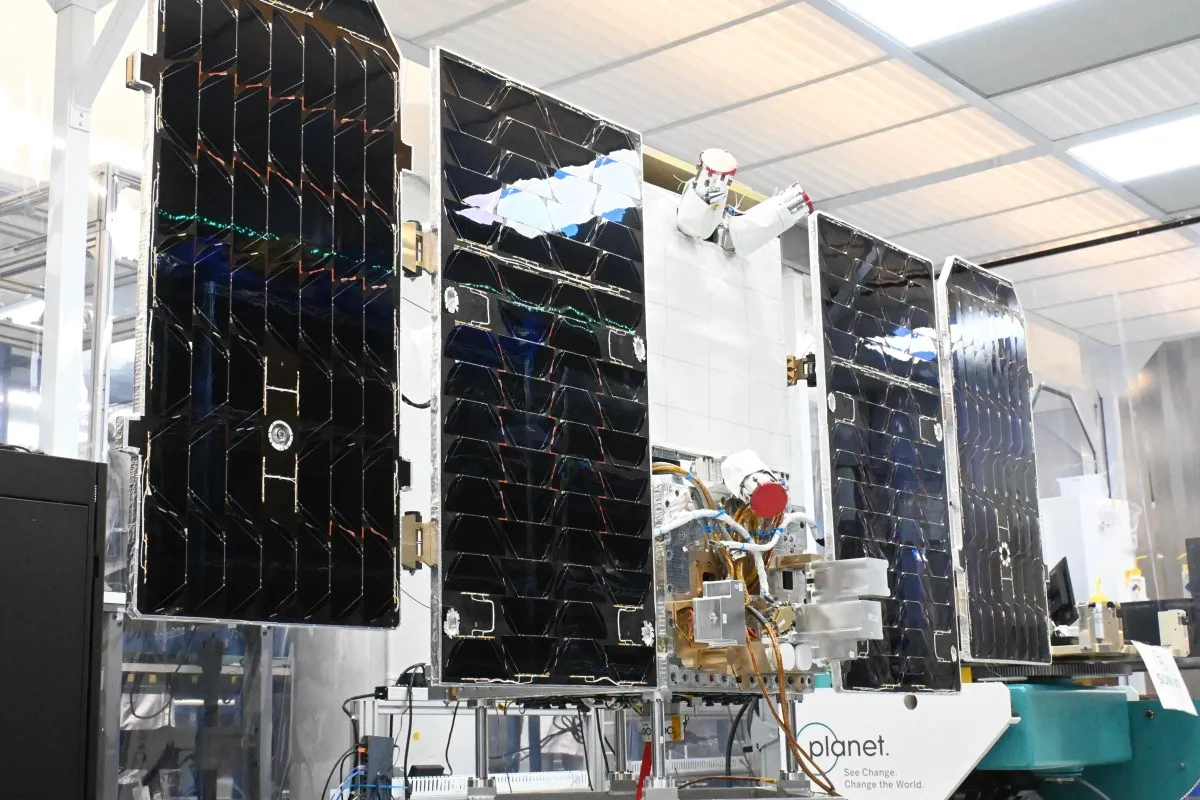
Suncatcher prototype is online, one TPU active for 20 minutes at a time
The 1 kW ceiling on Google's Suncatcher prototype means one TPU runs for about twenty minutes at a time, even though the satellite is now online and talking to the ground.
OpenAI plans to buy google TPUs
OpenAI plans to buy Google TPUs for training and serving AI models, but the chip count, price, and delivery schedule remain unconfirmed.
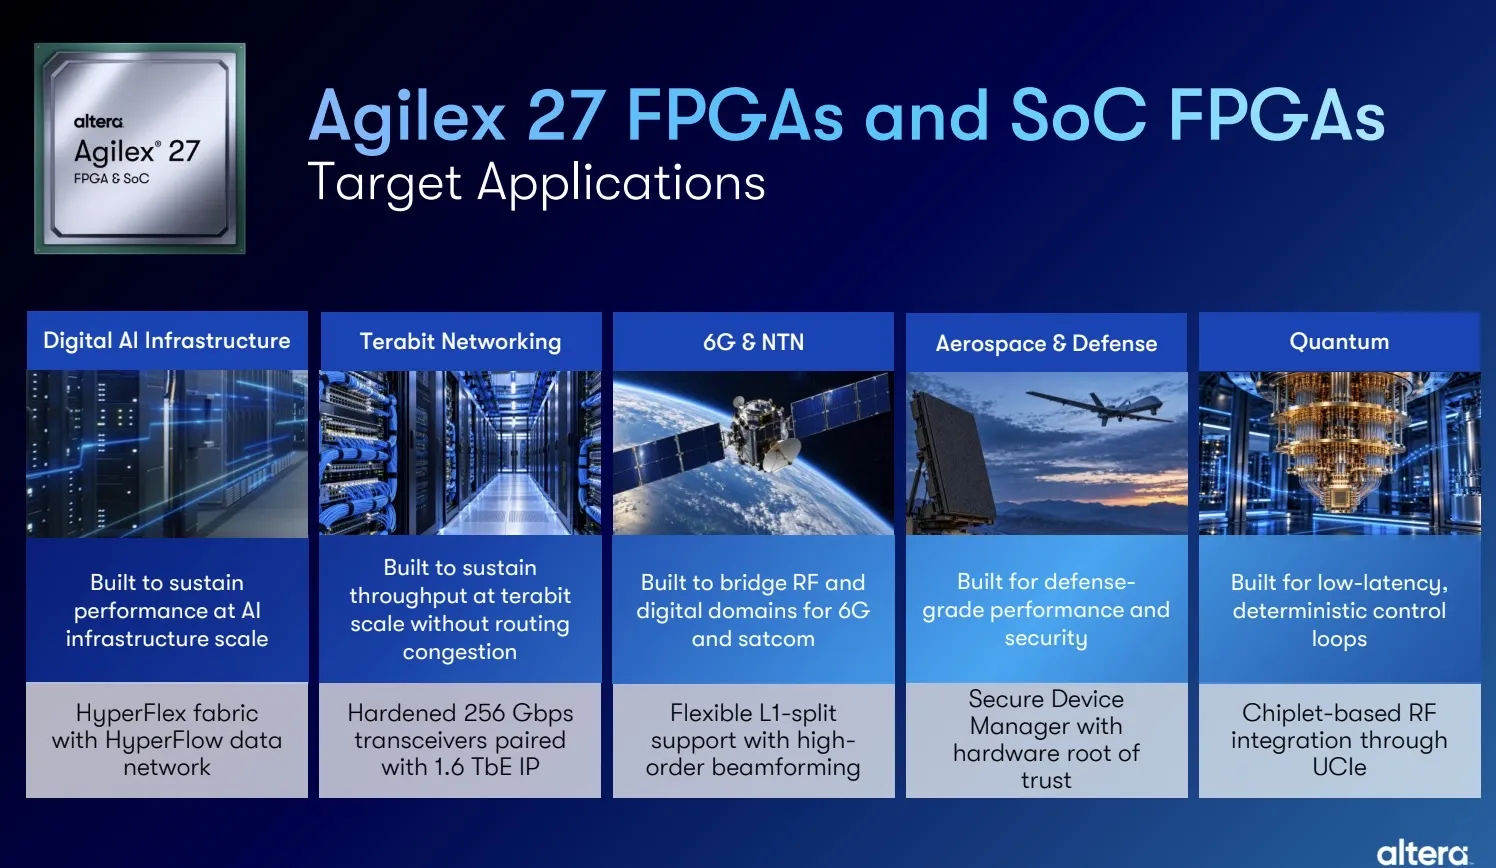
Altera Agilex 27 adds 800GbE and 1.6TbE to Agilex 2X in October 2026
Altera introduced Agilex 27 on October 28, 2026, as the first Agilex 2X platform with hardened 800GbE and 1.6TbE Ethernet.
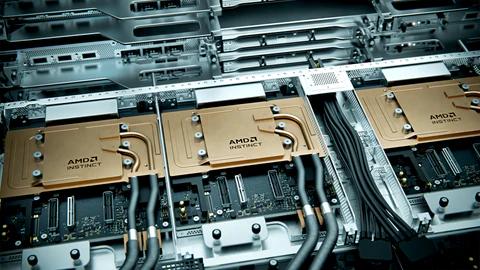
AMD names the MI430X without a spec sheet
AMD's MI400 Series page names the MI430X for sovereign AI and HPC but provides no memory, bandwidth, FLOPS, or price figures for the chip.
OpenAI frontier models enter Google Cloud Model Garden
OpenAI's vendor page dated October 21, 2026 confirms frontier models and Codex workflows will be purchasable through Google Cloud Marketplace, with general availability in the coming weeks.
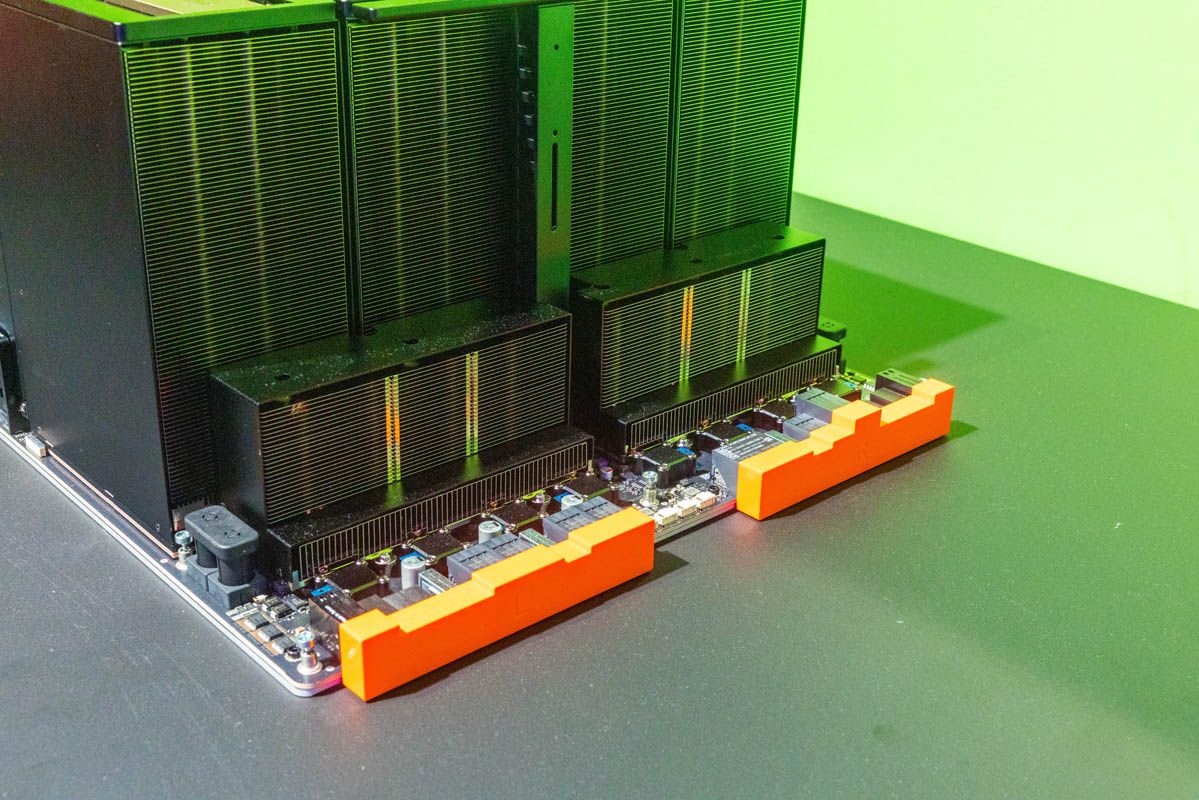
NVIDIA HGX B300 NVL16 shifts from package count to die count
NVIDIA's HGX B300 NVL16 carries up to 2.3TB of HBM3e across sixteen dual Blackwell GPU package modules, while eight ConnectX-8 NICs sit on the UBB.
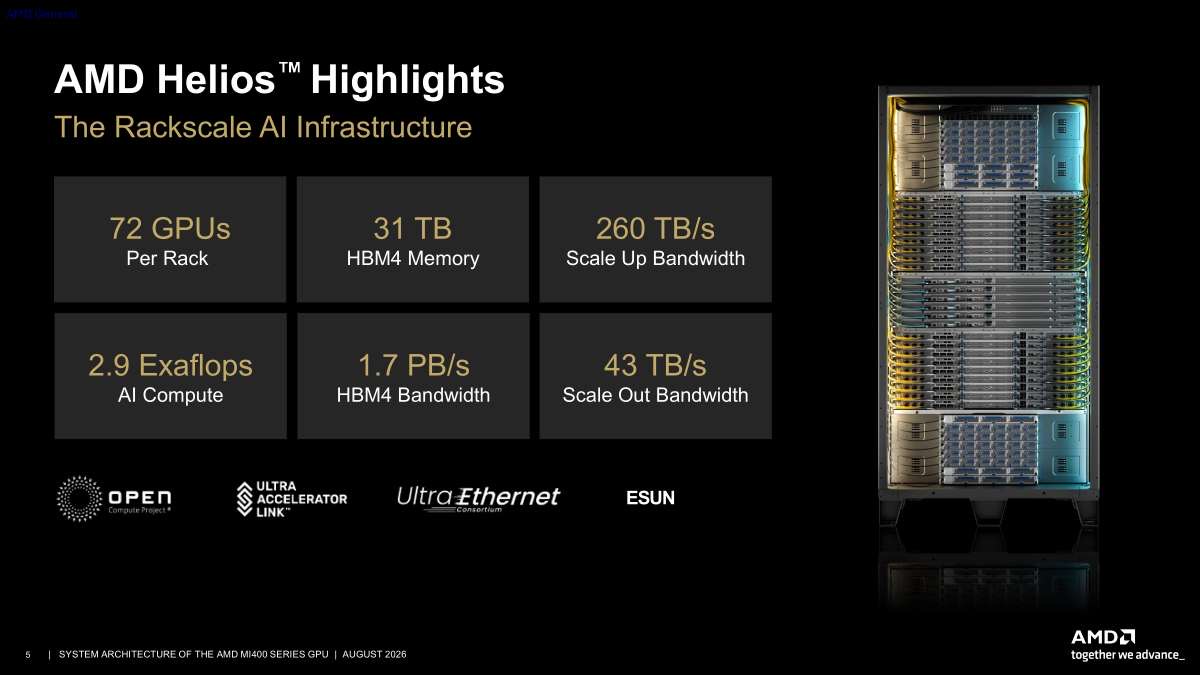
AMD Helios moves the constraint from chips to facility economics
The Helios rack carries 31 TB of HBM4 across 72 MI455X GPUs, and that memory stack sets the scale of the decision.
ByteDance weighs custom MediaTek ASICs for data centers
ByteDance is reportedly near a MediaTek ASIC deal, while considering data-center and AI infrastructure spending of up to 70 billion dollars.
Amazon is reportedly in talks to buy Decart for up to $7 billion
Amazon is reportedly in talks to acquire Decart, whose DOS software compresses neural-network tuning from months into weeks, at a value of up to $7 billion.
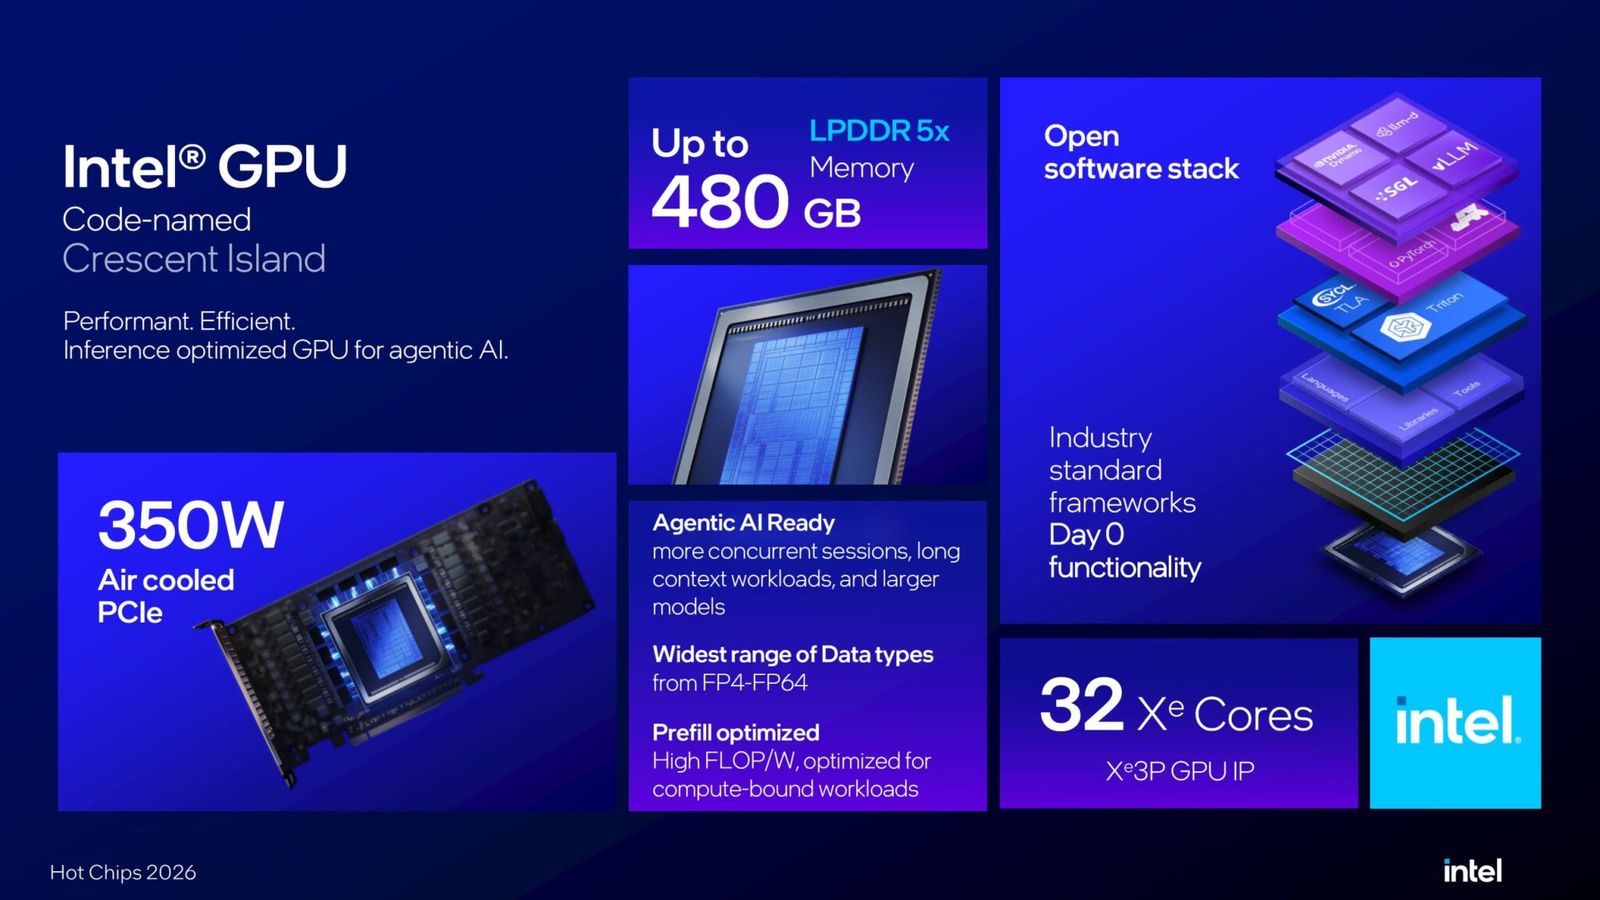
Partner memory claim moves past Intel's official 480GB ceiling
Intel's official partner ceiling is 480GB, and a leaker puts partner boards at 512GB.
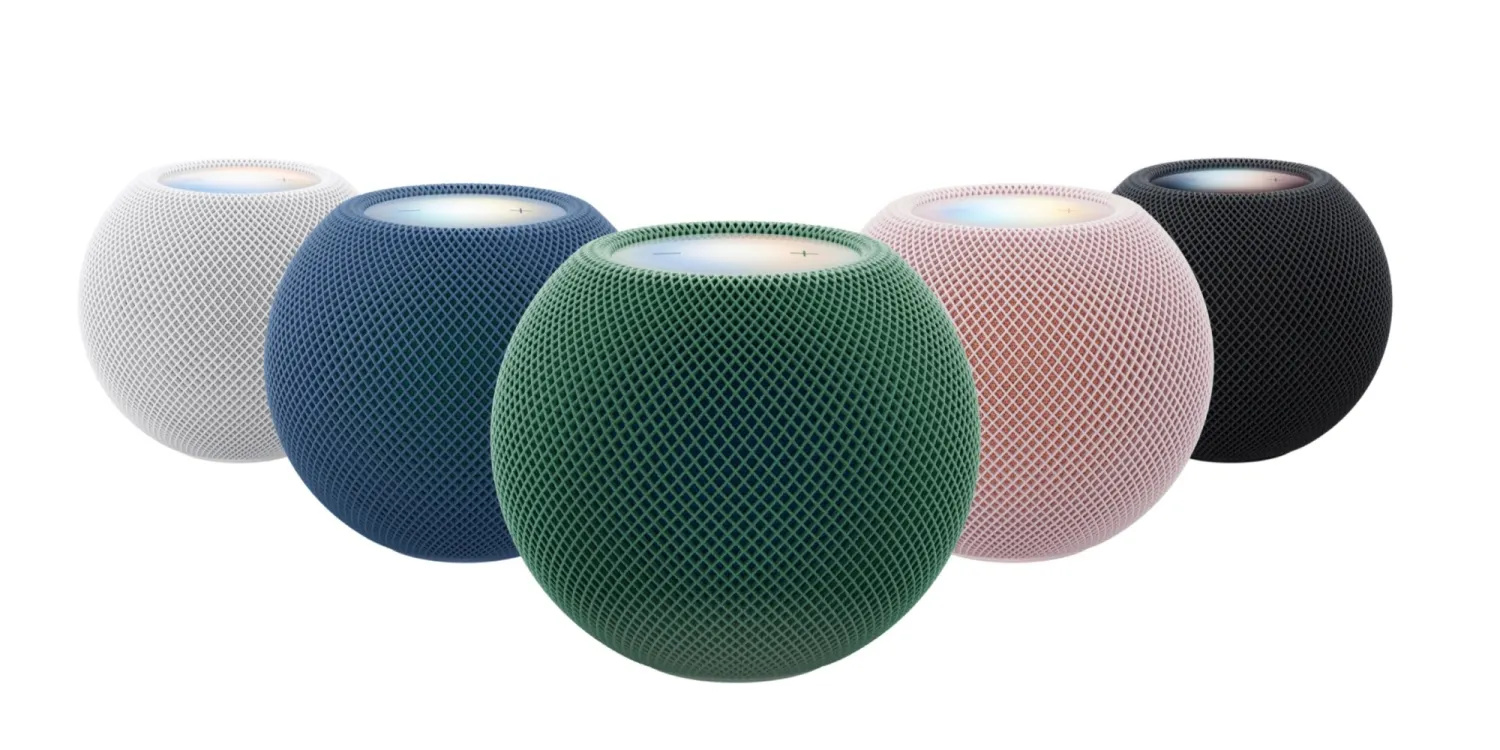
Wi-Fi 6E Is the HomePod mini 2's Ticket to the Mac's Default Audio Slot
The HomePod mini 2's jump from Wi-Fi 4 to Wi-Fi 6E is not a cosmetic spec bump—it is the functional prerequisite that lets the speaker become a Mac's default audio output, a role the original HomePod mini could only approximate through AirPlay with its attendant latency.
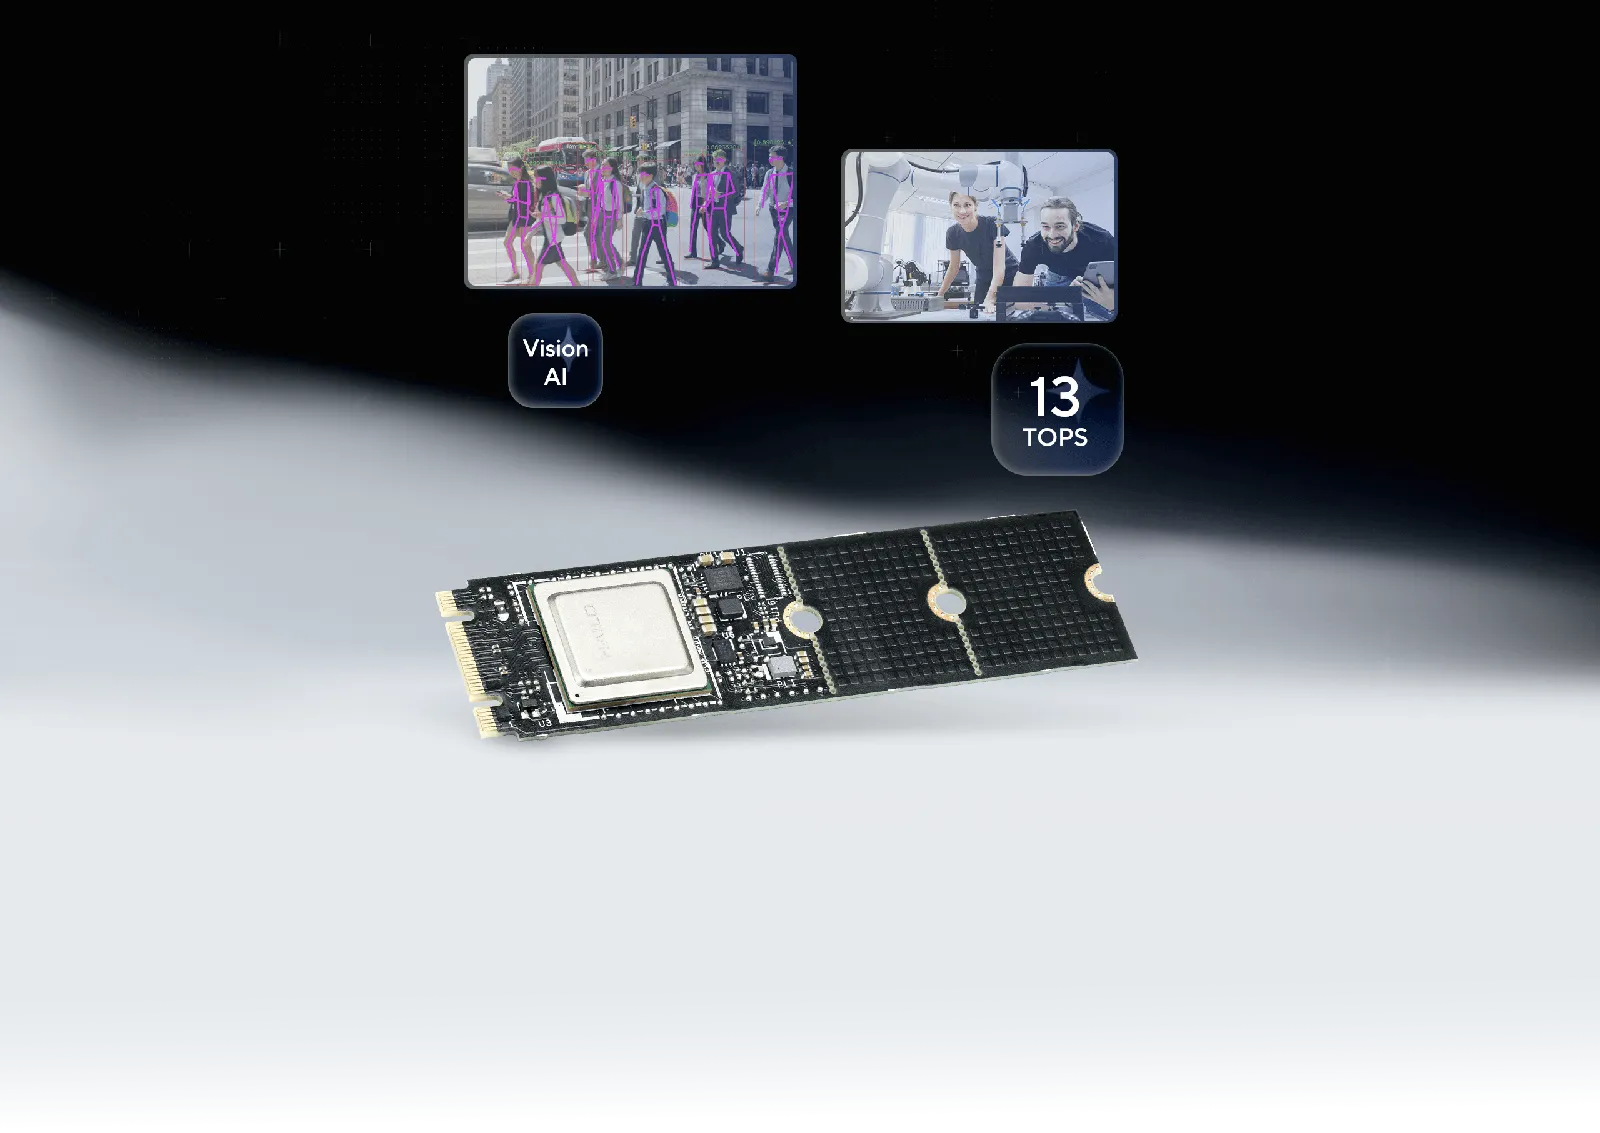
ASUS UGen200 M.2 AI module adds Hailo-8L vision inference
The ASUS UGen200 M2(B+M) AI Module is an M.2 Key B+M edge accelerator with Hailo-8L, up to 13 TOPS INT8, and 1.5 W typical power.
Intel GPU D270: 480 GB LPDDR5X, 32 Xe3P cores, no price
Intel's GPU D270 pairs 480 GB of LPDDR5X with 32 Xe3P cores and 256 XMX matrix engines in a 350-watt air-cooled package, but the Phoronix page of 12 October 2026 states no price.
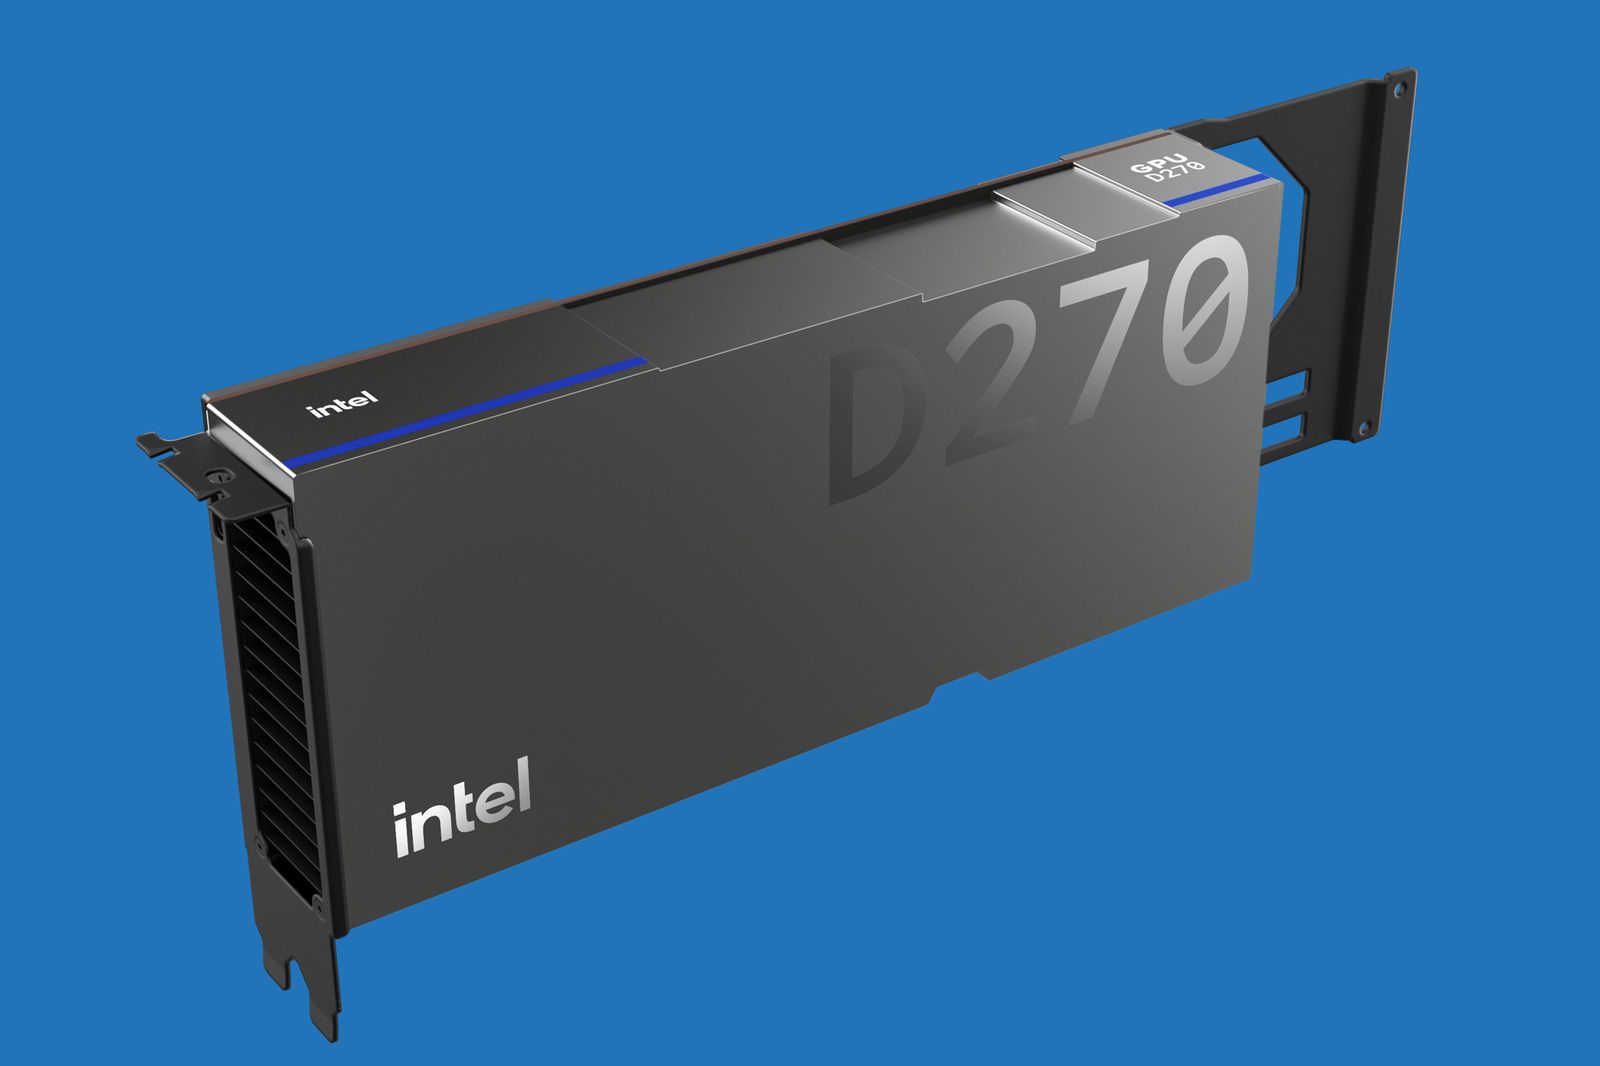
Intel names crescent island the GPU D270
The first Crescent Island card is an air-cooled PCIe CEM part named the D270, with a 350W design and up to 480GB of LPDDR5X.
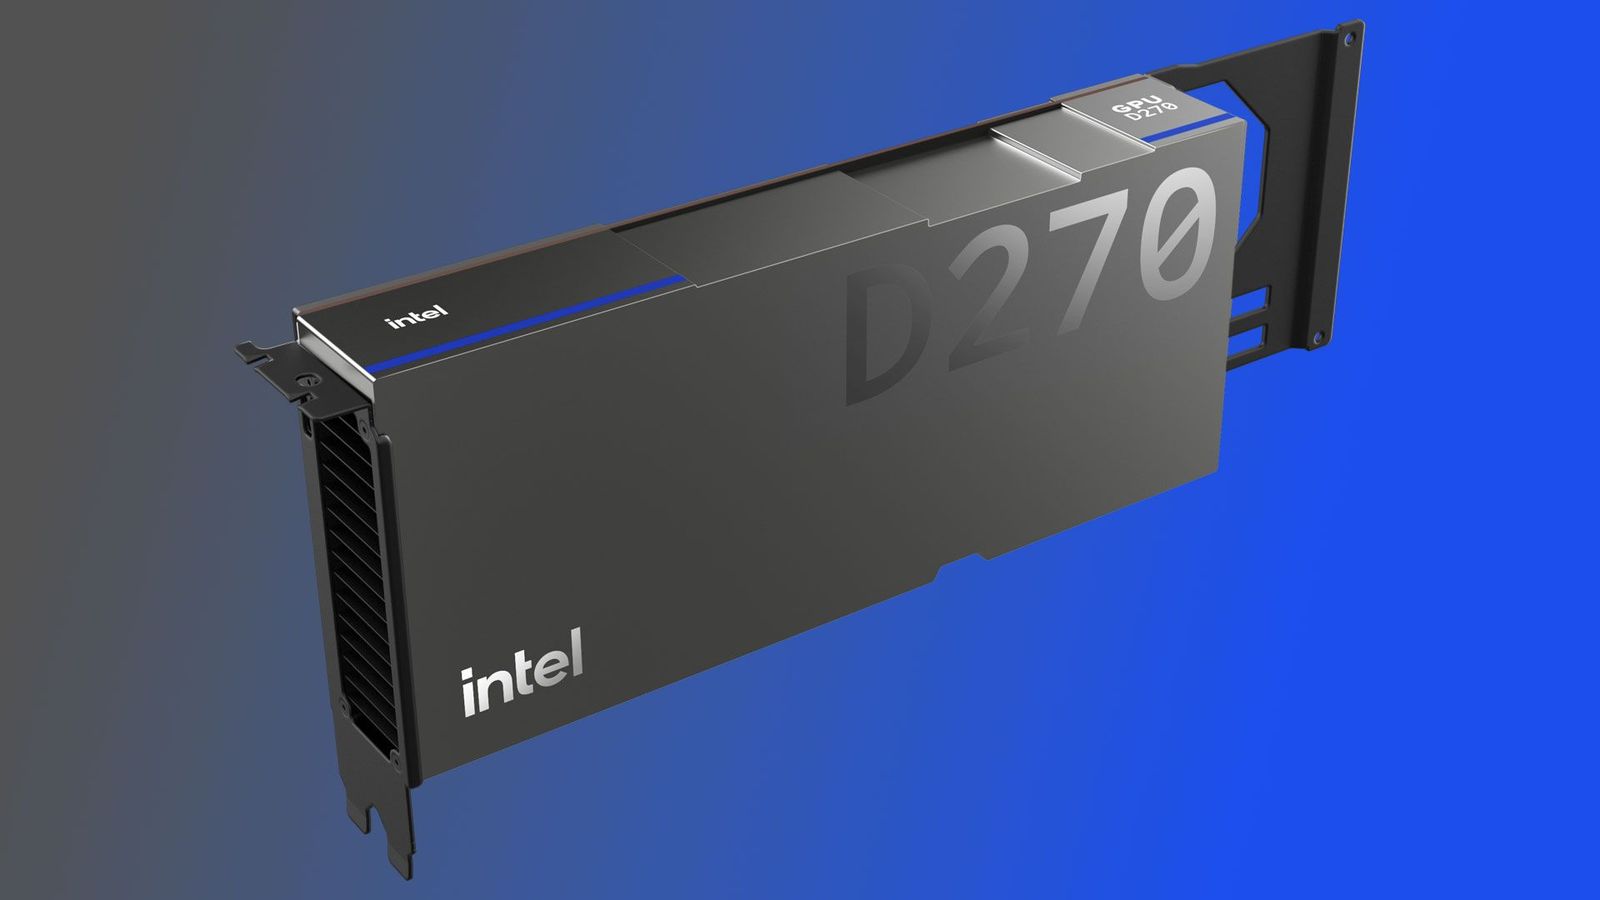
Crescent Island ties FP8 peak to D-Series GPUs
Intel's Crescent Island accelerator officially powers new GPU D-Series products, with 1.3 peak PFLOPS of FP8 compute and 1.5 TB/s of memory bandwidth.
AMD MI455X carries 432 GB of HBM4 and no published price
AMD's MI455X spec page lists 432 GB of HBM4, a 40.3 PFLOPs OCP MXFP4 peak, and a 7/23/2026 launch date, but no price, no TDP, and no rack configuration.
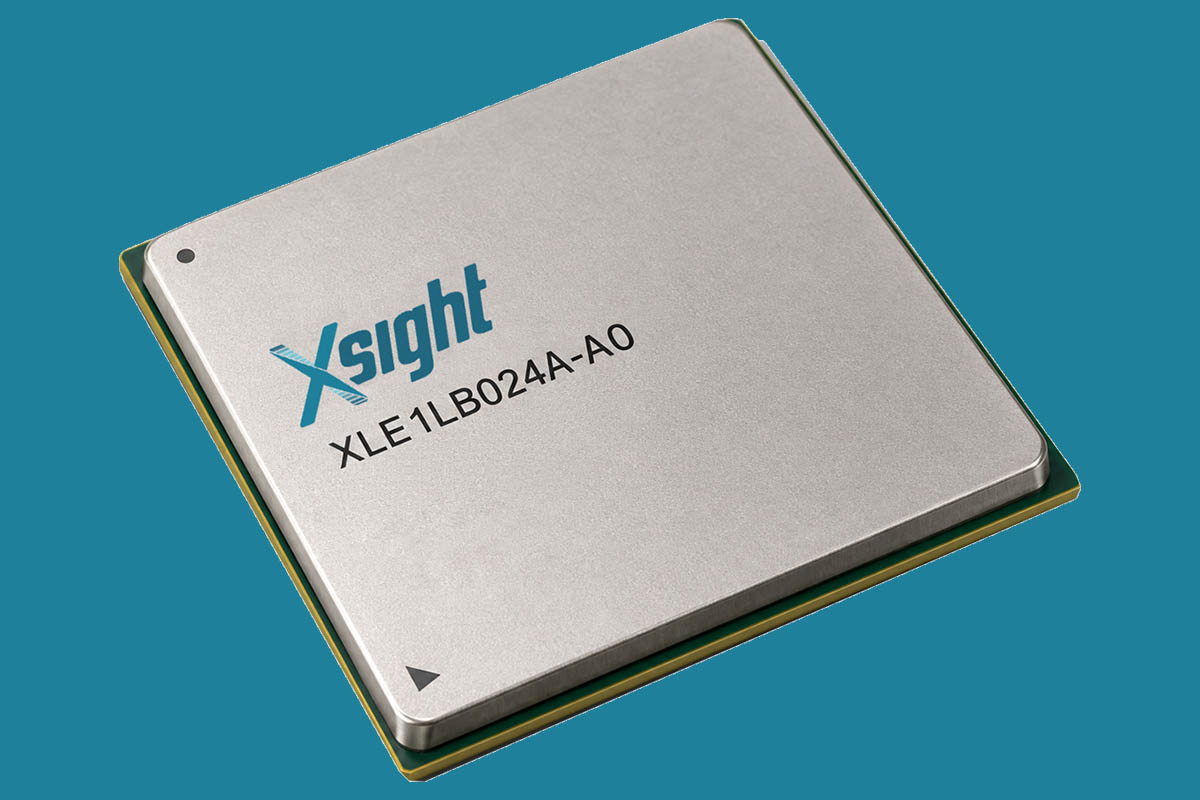
Xsight E1L DPU fits switch power budgets
Xsight Labs lists the E1L DPU with 8, 16, or 22 Arm Neoverse N2 cores, up to 200Gbps over four SerDes lanes, and configurable 25 W, 30 W, or 40 W TDP.
Surface RTX Spark Dev Box: $5,999, one channel, no measured number
Microsoft lists the Surface RTX Spark Dev Box at $5,999 MSRP, pre-order exclusive to Microsoft.com in the U.S., shipping November 2026, built on the NVIDIA RTX Spark Superchip.
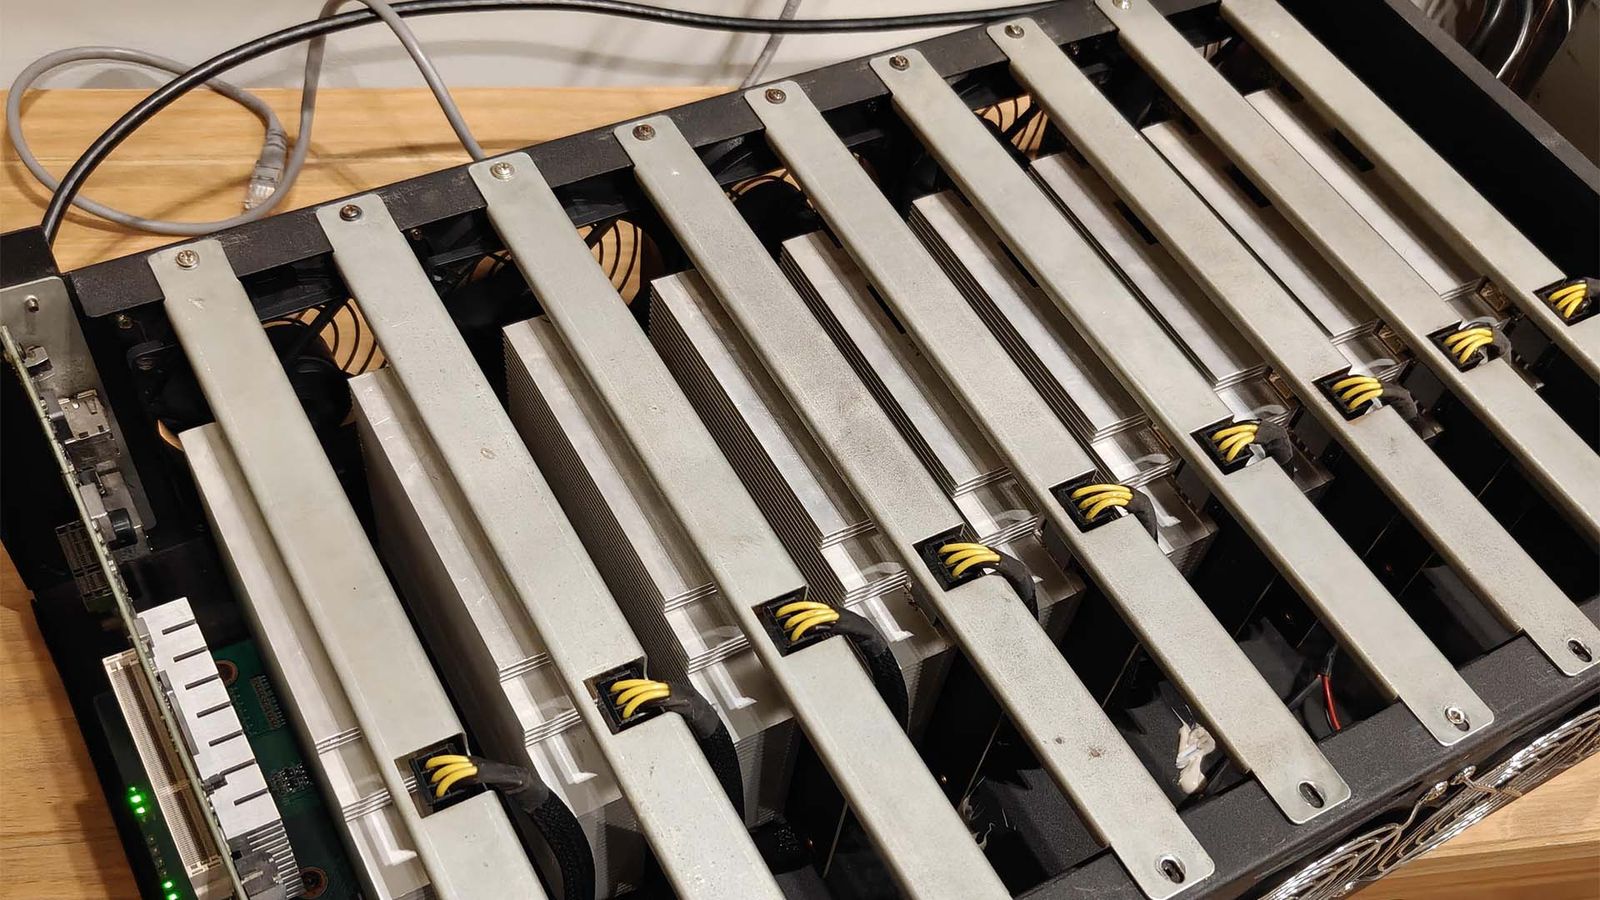
Nine P106 cards and 54GB of VRAM at 3,000 rubles set a cheap local-LLM floor
Nine P106 cards with 54GB of VRAM were bought for 3,000 rubles, about $35, after the price was cut from 5,000 rubles, and the buyer says the rig can run quantized local LLMs.
FemtoAI opens developer community with unmeasured tenfold claim
The October 6, 2026 filing says femtoAI opened its developer community and lists an SPU evaluation kit, compiler, compressed models, and Sparsity Studio.
Tencent Oracle offshore chip deal leaves cost basis unmeasured
The wire headline ties Tencent to a 100,000-chip offshore AI deal with Oracle at $7 billion, but the page gives no measured per-hour cost.
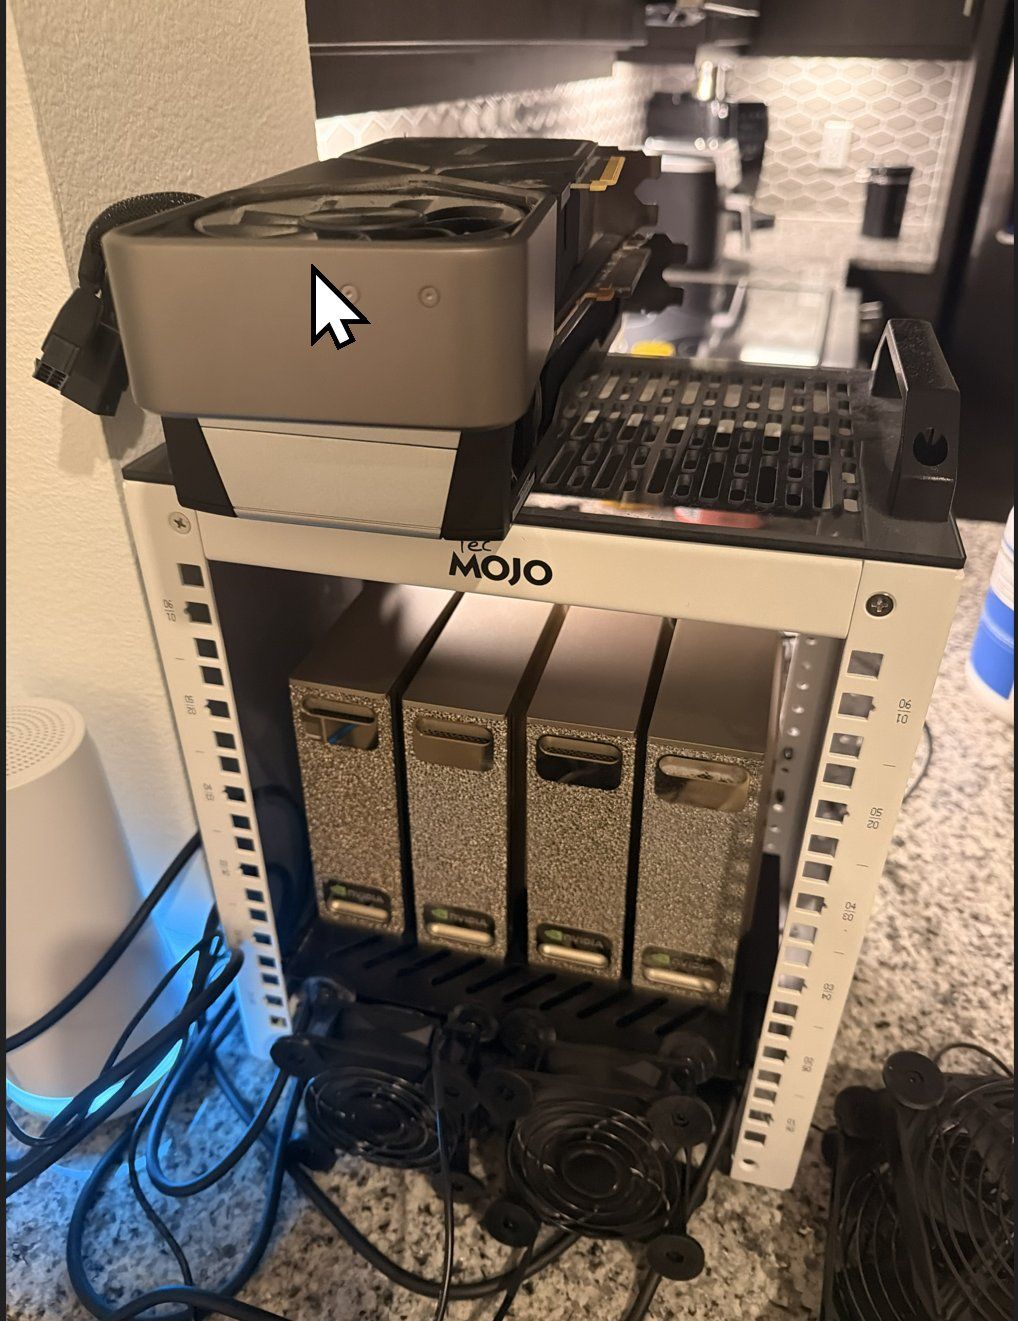
494 tokens per second on four DGX Sparks
A four-node NVIDIA DGX Spark rack ran DeepSeek V4.1-Flash at 494 tokens per second for code with 32 concurrent requests.
SEMIFIVE and Mobilint lock LPDDR6, PCIe Gen6, UCIe-S into a robotics ASIC contract
SEMIFIVE and Mobilint signed a turnkey contract on October 1, 2026, naming LPDDR6, PCIe Gen6, and UCIe-S as the interconnect stack for an agricultural-robotics AI chip.
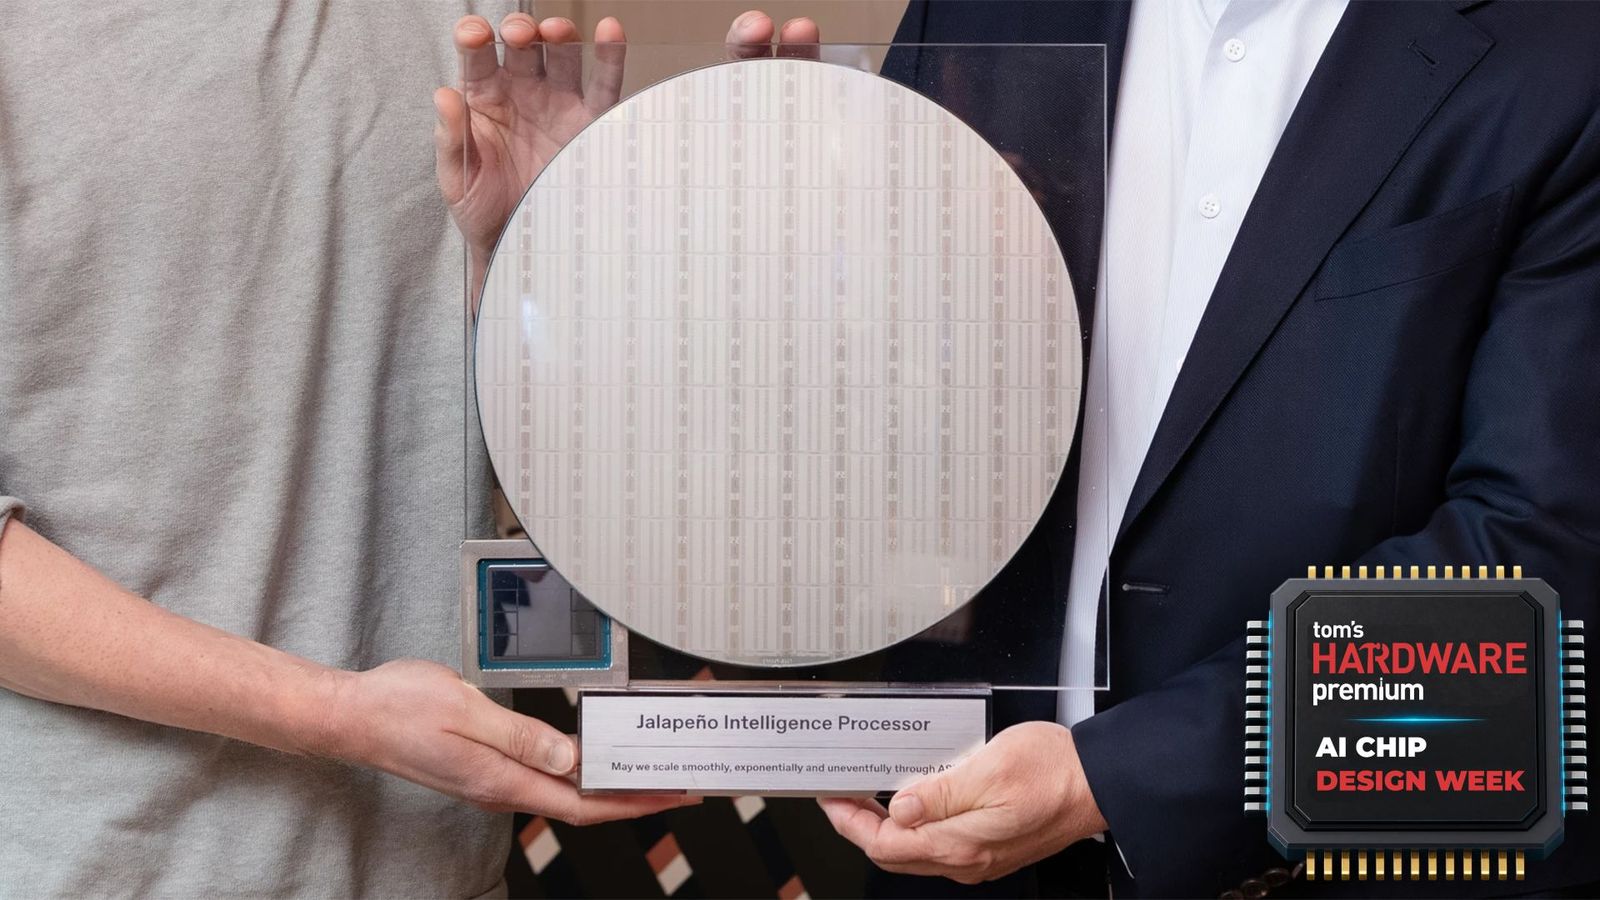
OpenAI's Jalapeño inference ASIC has no spec sheet yet
OpenAI's hardware VP Richard Ho discussed the Jalapeño inference ASIC in an interview, but the transcript carries no node, power, or memory figures.
AMD's NPU3 driver drops the userspace doorbell
David Zhang's 21-patch series moves NPU3 command submission from userspace doorbell mapping into kernel mode, adding fence management and full suspend/resume support.
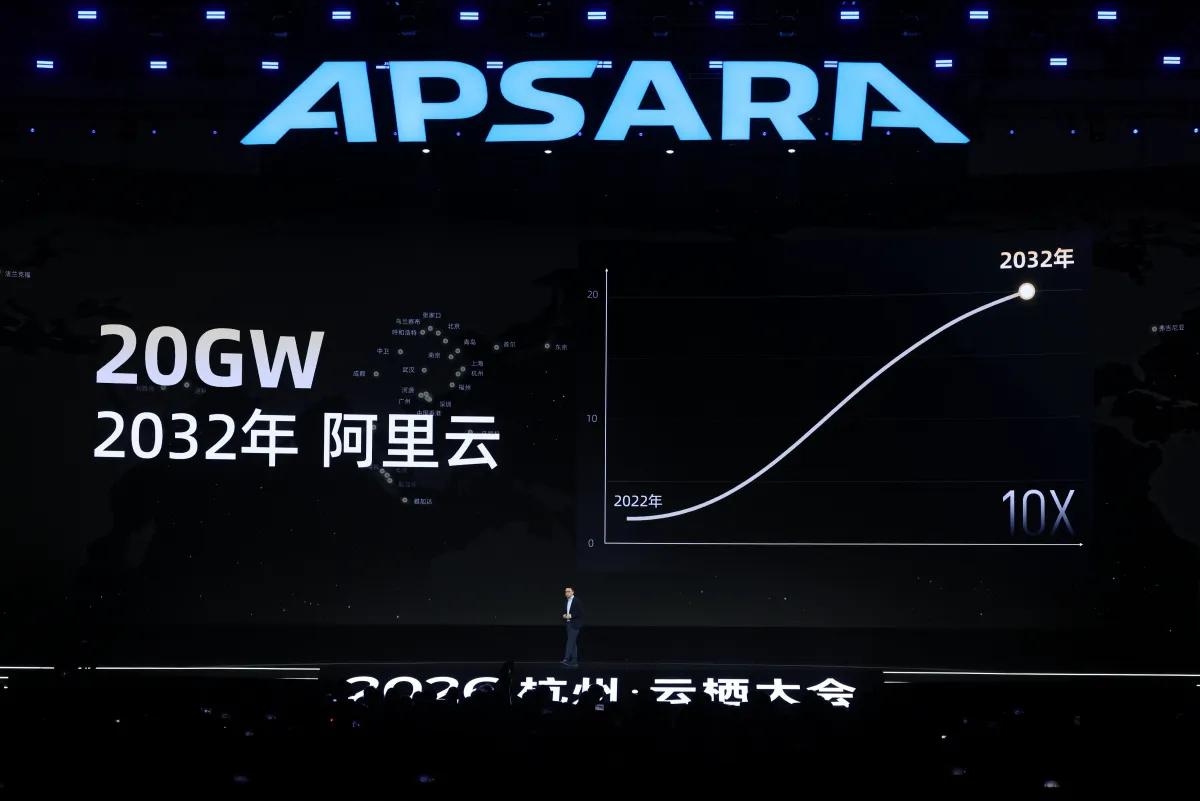
Zhenwu V900 cluster target lacks silicon proof
The Tom's Hardware page names a Zhenwu V900 accelerator, a 500,000-chip supercluster target, and a 10T-parameter Qwen model on the roadmap.
ZLUDA maps cuFFT to hipFFT, unlocking Folding@Home CUDA cores on AMD GPUs
ZLUDA 7-preview.11 maps NVIDIA cuFFT calls to AMD hipFFT, enabling Folding@Home Core24 and Core27 CUDA cores to run on AMD Radeon GPUs.
Huawei shelves global Atlas rollout as domestic demand outstrips supply
Huawei will not sell its latest Atlas AI hardware outside China, citing domestic demand that already exceeds production capacity at 120 EFLOPS cluster scale.
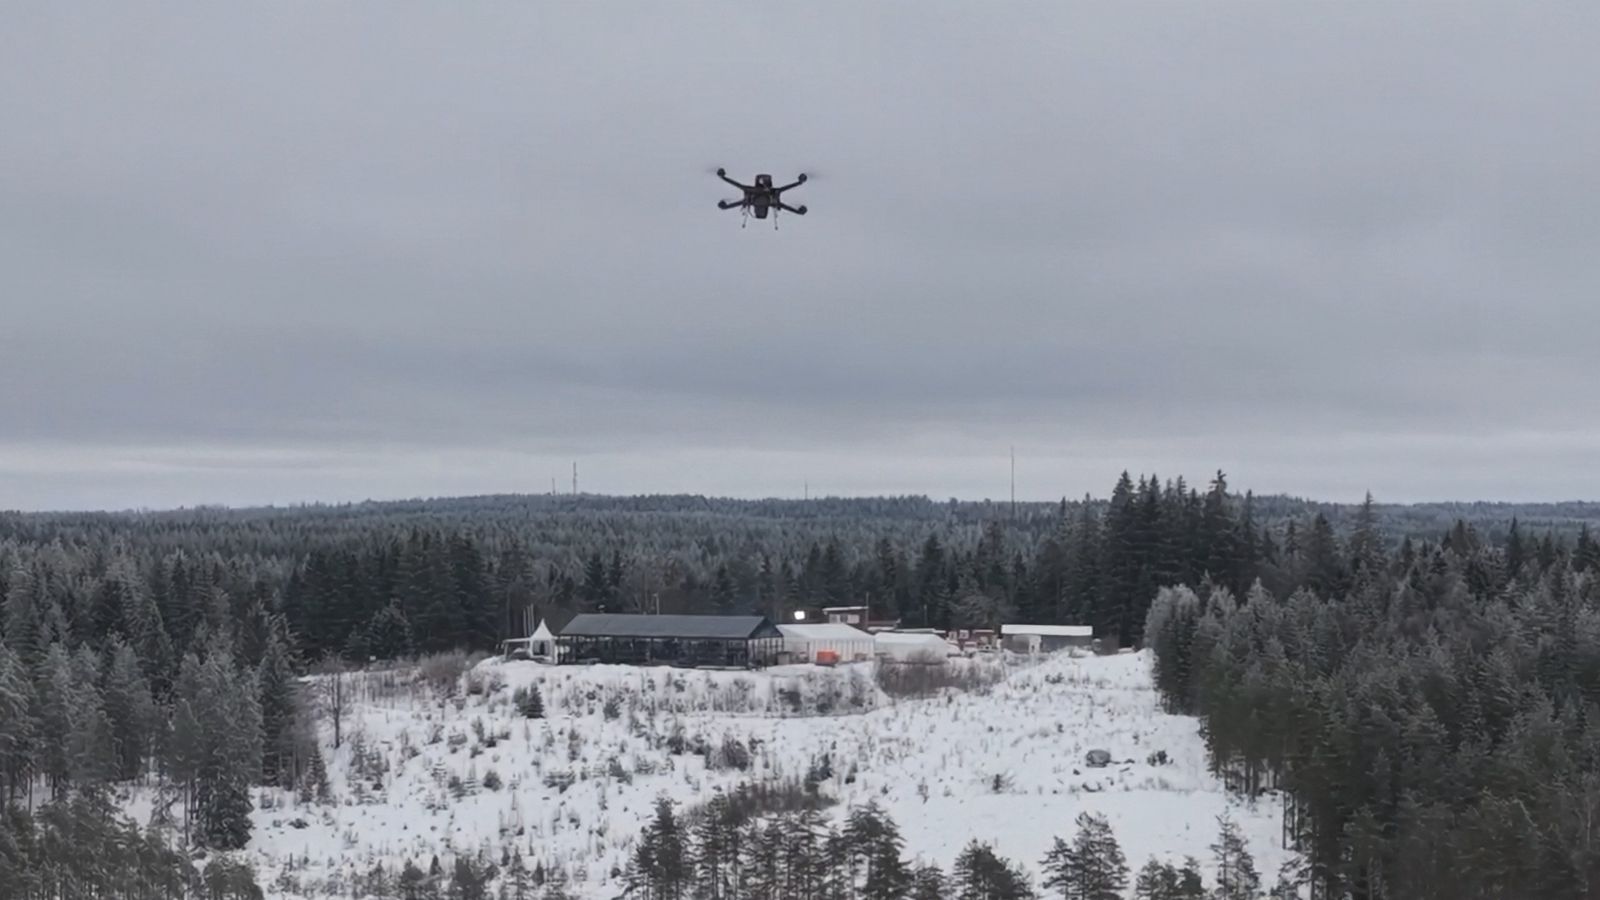
Swedish drone design pairs Jetson Orin Nano with human target check
A Swedish startup's NATO strike drone design is said to use an Nvidia Jetson Orin Nano to identify targets, while a human verifies the target before attack.
Chip Industry Week in Review: Memory Deals, AI Infra, and 2nm Advances
A weekly chip industry review covers Infineon's $1.12B NOR flash sale to Winbond, SK hynix talks with Intel for US memory manufacturing, and 2nm and below advances.
Unified Chiplet Network Scales Neuromorphic Computing Systems
Heidelberg University researchers published a unified interconnection network for chiplet-based scaling of the BrainScaleS neuromorphic system, handling two distinct classes of traffic.
Eight chiplets, two papers, no shared benchmark
Fengshui co-designs 8 chiplets into bespoke accelerators and reports 48.5% energy reduction, but the dossier's deepest pages describe a different paper entirely.
Qwen3.8-27B at 2.0 bits per weight on a 16 GB card
A 27B-parameter model in EXL3 2.0-bit quantization occupies 9.7 GB and fits a single 16 GB NVIDIA card, per a one-click serving kit from MiaAI-Lab.