Nvidia's Nemotron 3.5 Transcribe, released October 28, runs 30B speech on one GPU
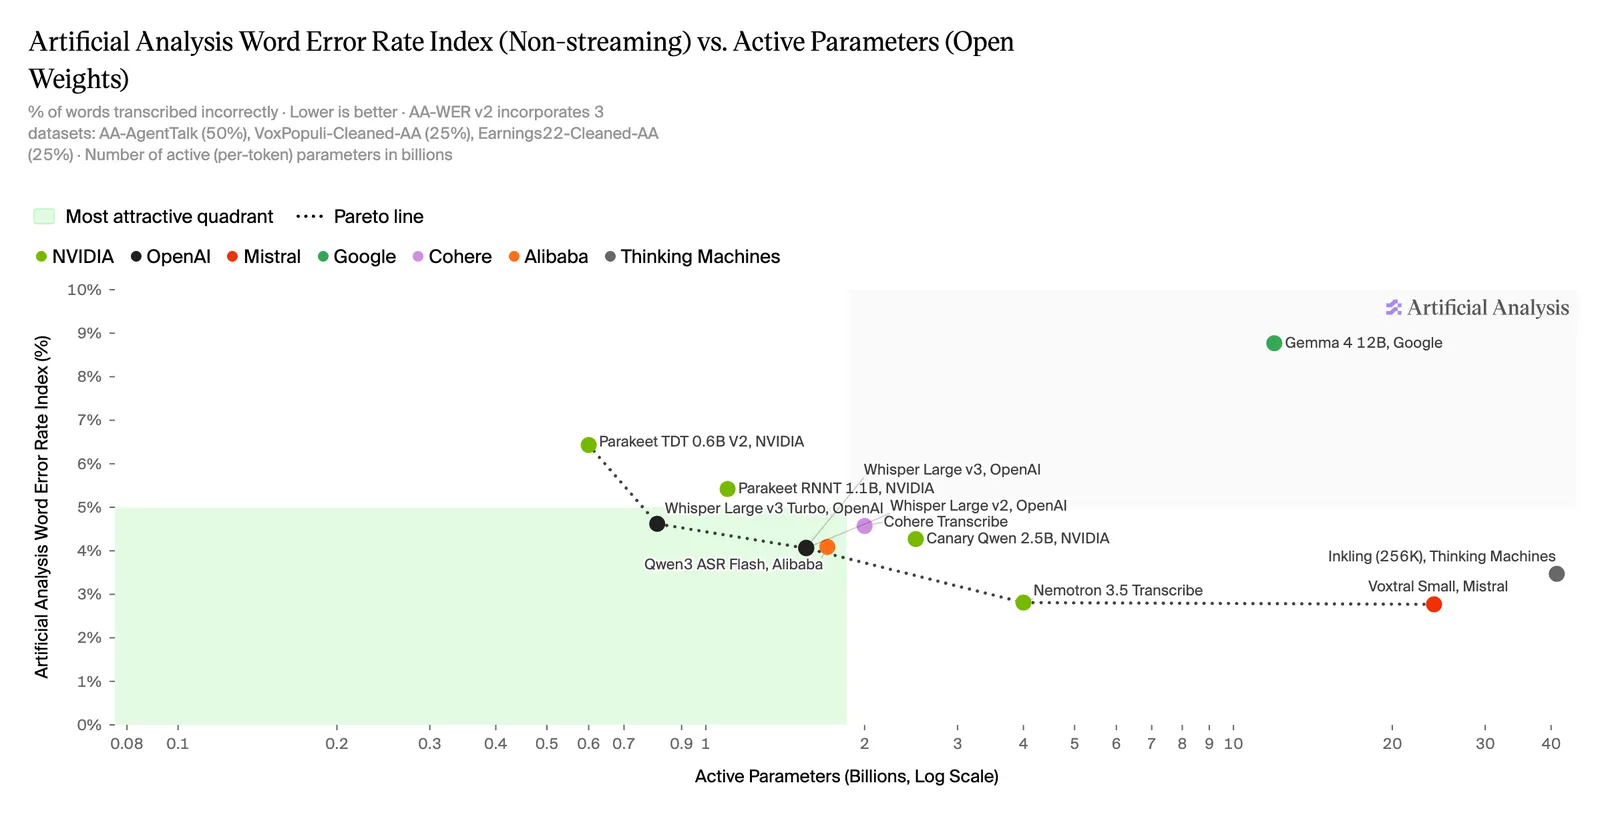
Nvidia released Nemotron 3.5 Transcribe on October 28, 2026, as an open-weight speech model with 4.3B active parameters.
| Nemotron 3.5 Transcribe | |
|---|---|
| active parameters | approximately 4.3B |
| languages | 40 |
| max recording length | one hour |
| English Open ASR WER | 4.71% |
| multilingual Open ASR WER | 4.62% |
| throughput | up to 2,238 seconds of audio per second |
| license | OpenMDW-1.1 |
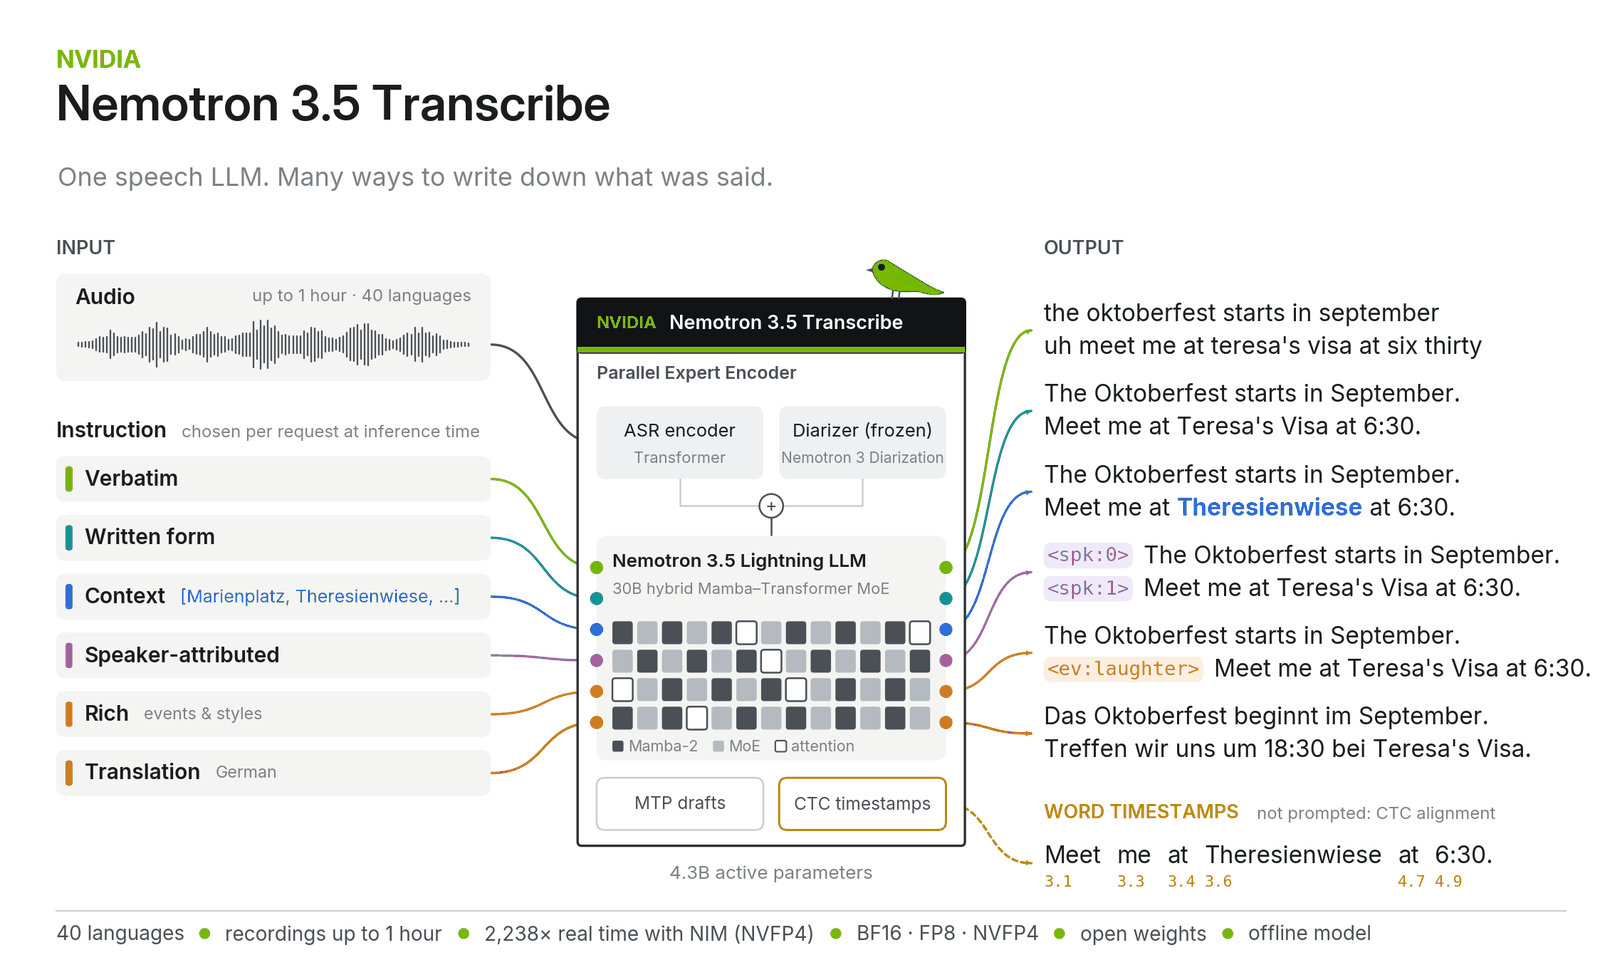
On a single RTX PRO 6000 Blackwell GPU, the NVFP4 checkpoint with DFlash2 transcribes up to 2,238 seconds of audio per second. That speed comes from a hybrid Mamba-Transformer mixture-of-experts design, where 4.3B of the 30B parameters activate per step.
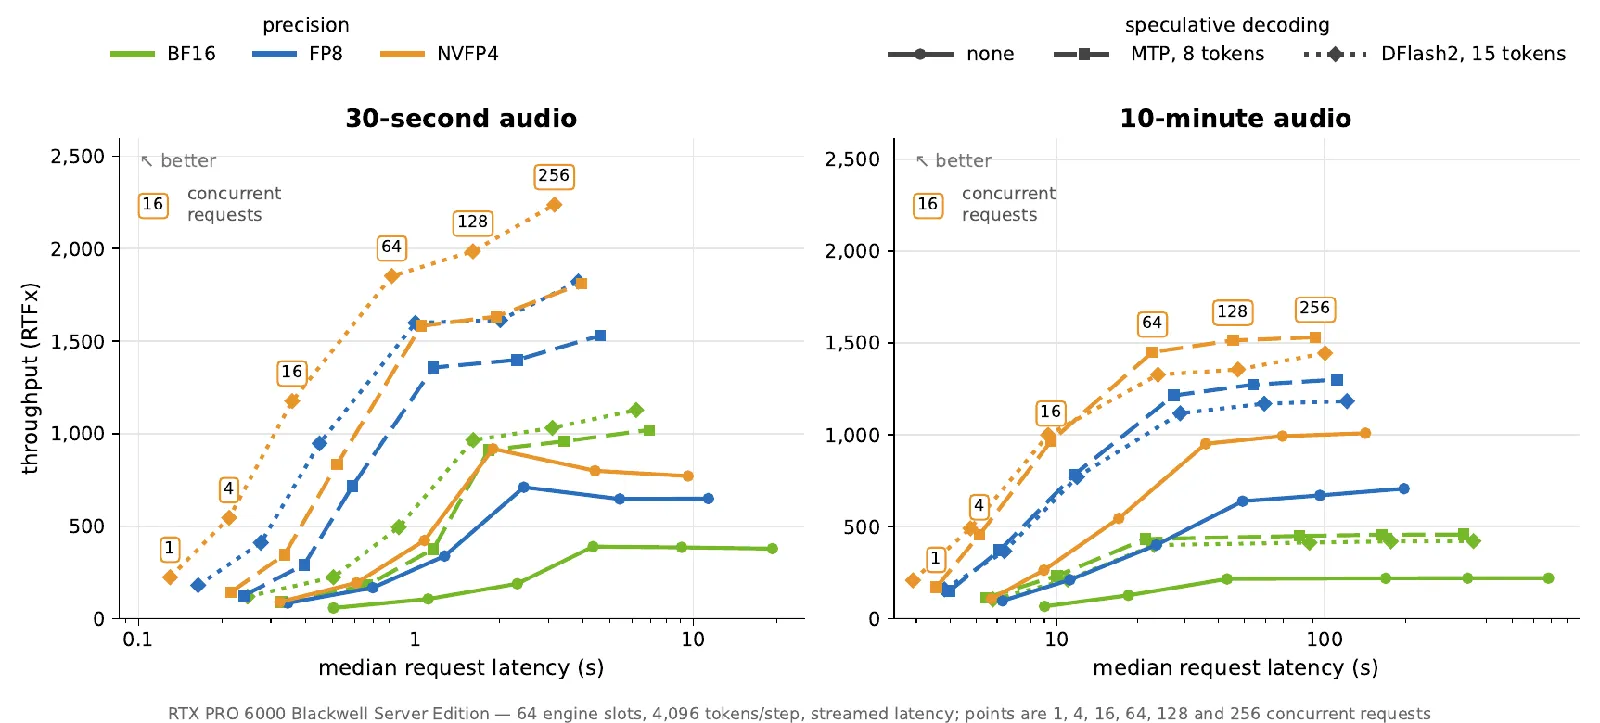
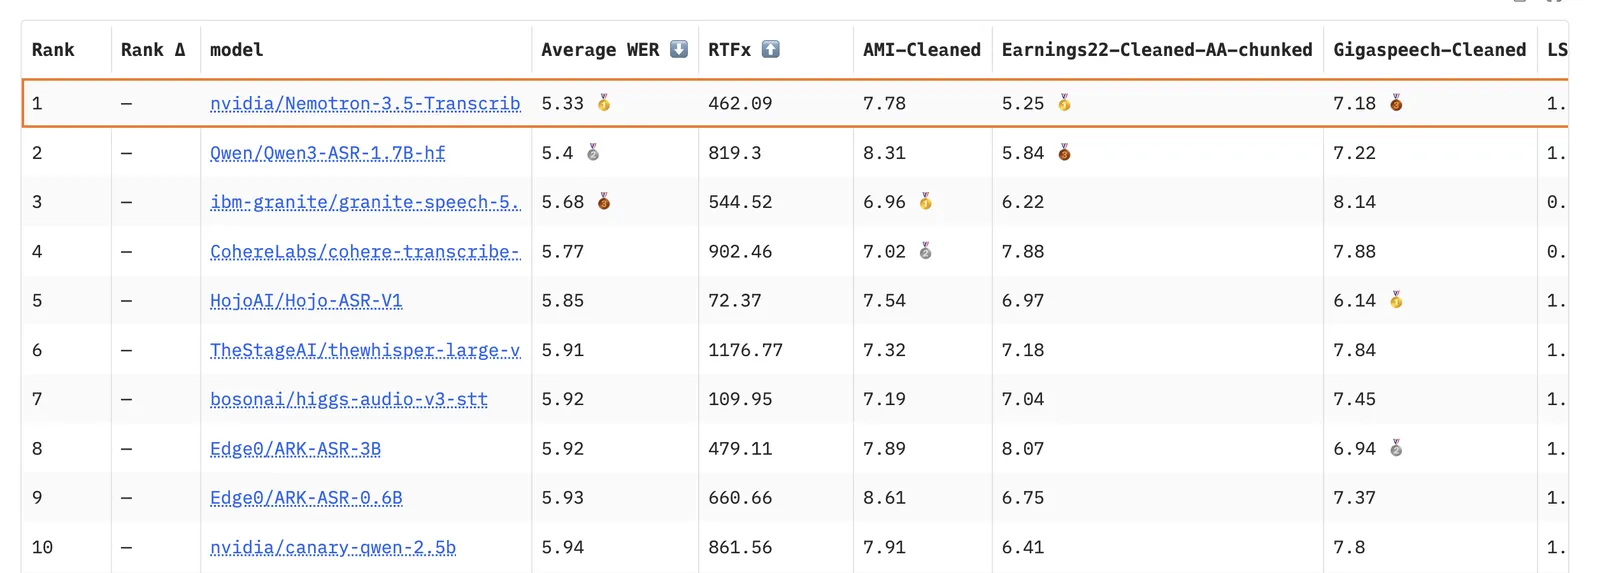
It posts a mean WER of 4.71% on the English Open ASR Leaderboard and 4.62% on the multilingual set. The model handles 40 languages, recordings up to one hour long, and speaker-attributed word timestamps.
The model reduces named-entity errors on ContextASR-Bench by a factor of six when given a list of expected entities. The report does not measure live-stream latency, power draw, or accuracy on domain-specific jargon beyond the listed benchmarks.
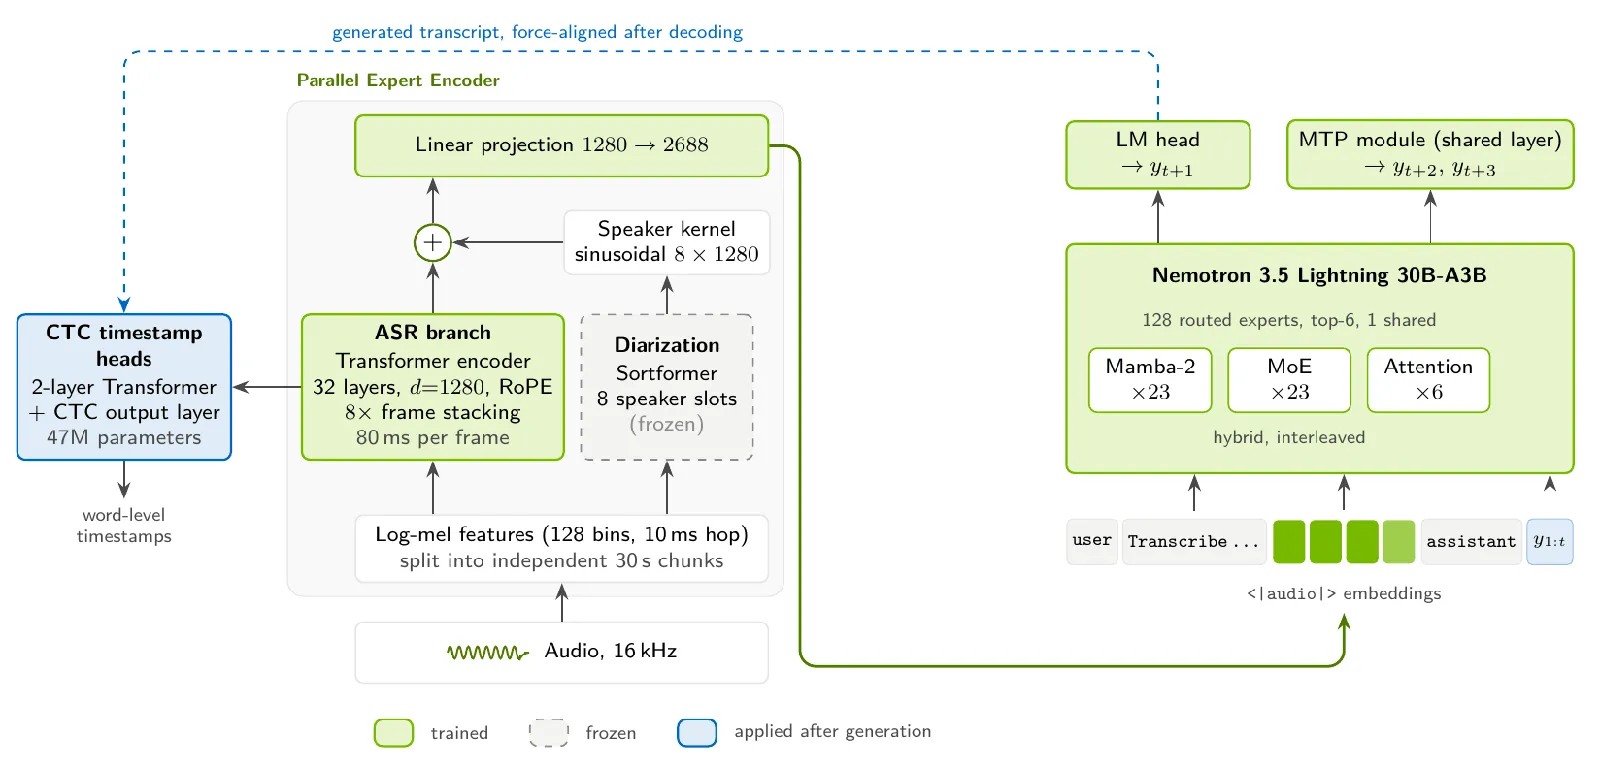
The model ships under the OpenMDW-1.1 license, with a fine-tuning toolkit in NeMo Speech.
The rewrite leads with throughput rather than parameter count, folds the MoE explanation into the speed claim, and drops the repeated buyer-guidance and limitation passages from the draft.
After @MistralAI. We did not report this. The pictures, if any, are theirs.