NVIDIA Nemotron 3.5 Transcribe bundles speech tasks into one checkpoint
One open-weight checkpoint carries NVIDIA Nemotron 3.5 Transcribe's transcription, speaker attribution, translation, and audio question answering.
| NVIDIA Nemotron 3.5 Transcribe | Granary v2 | |
|---|---|---|
| languages | 40 languages | 48 languages |
| translation | 31 languages translated to or from English | |
| speaker attribution | 13 languages | |
| max recording | up to an hour long | |
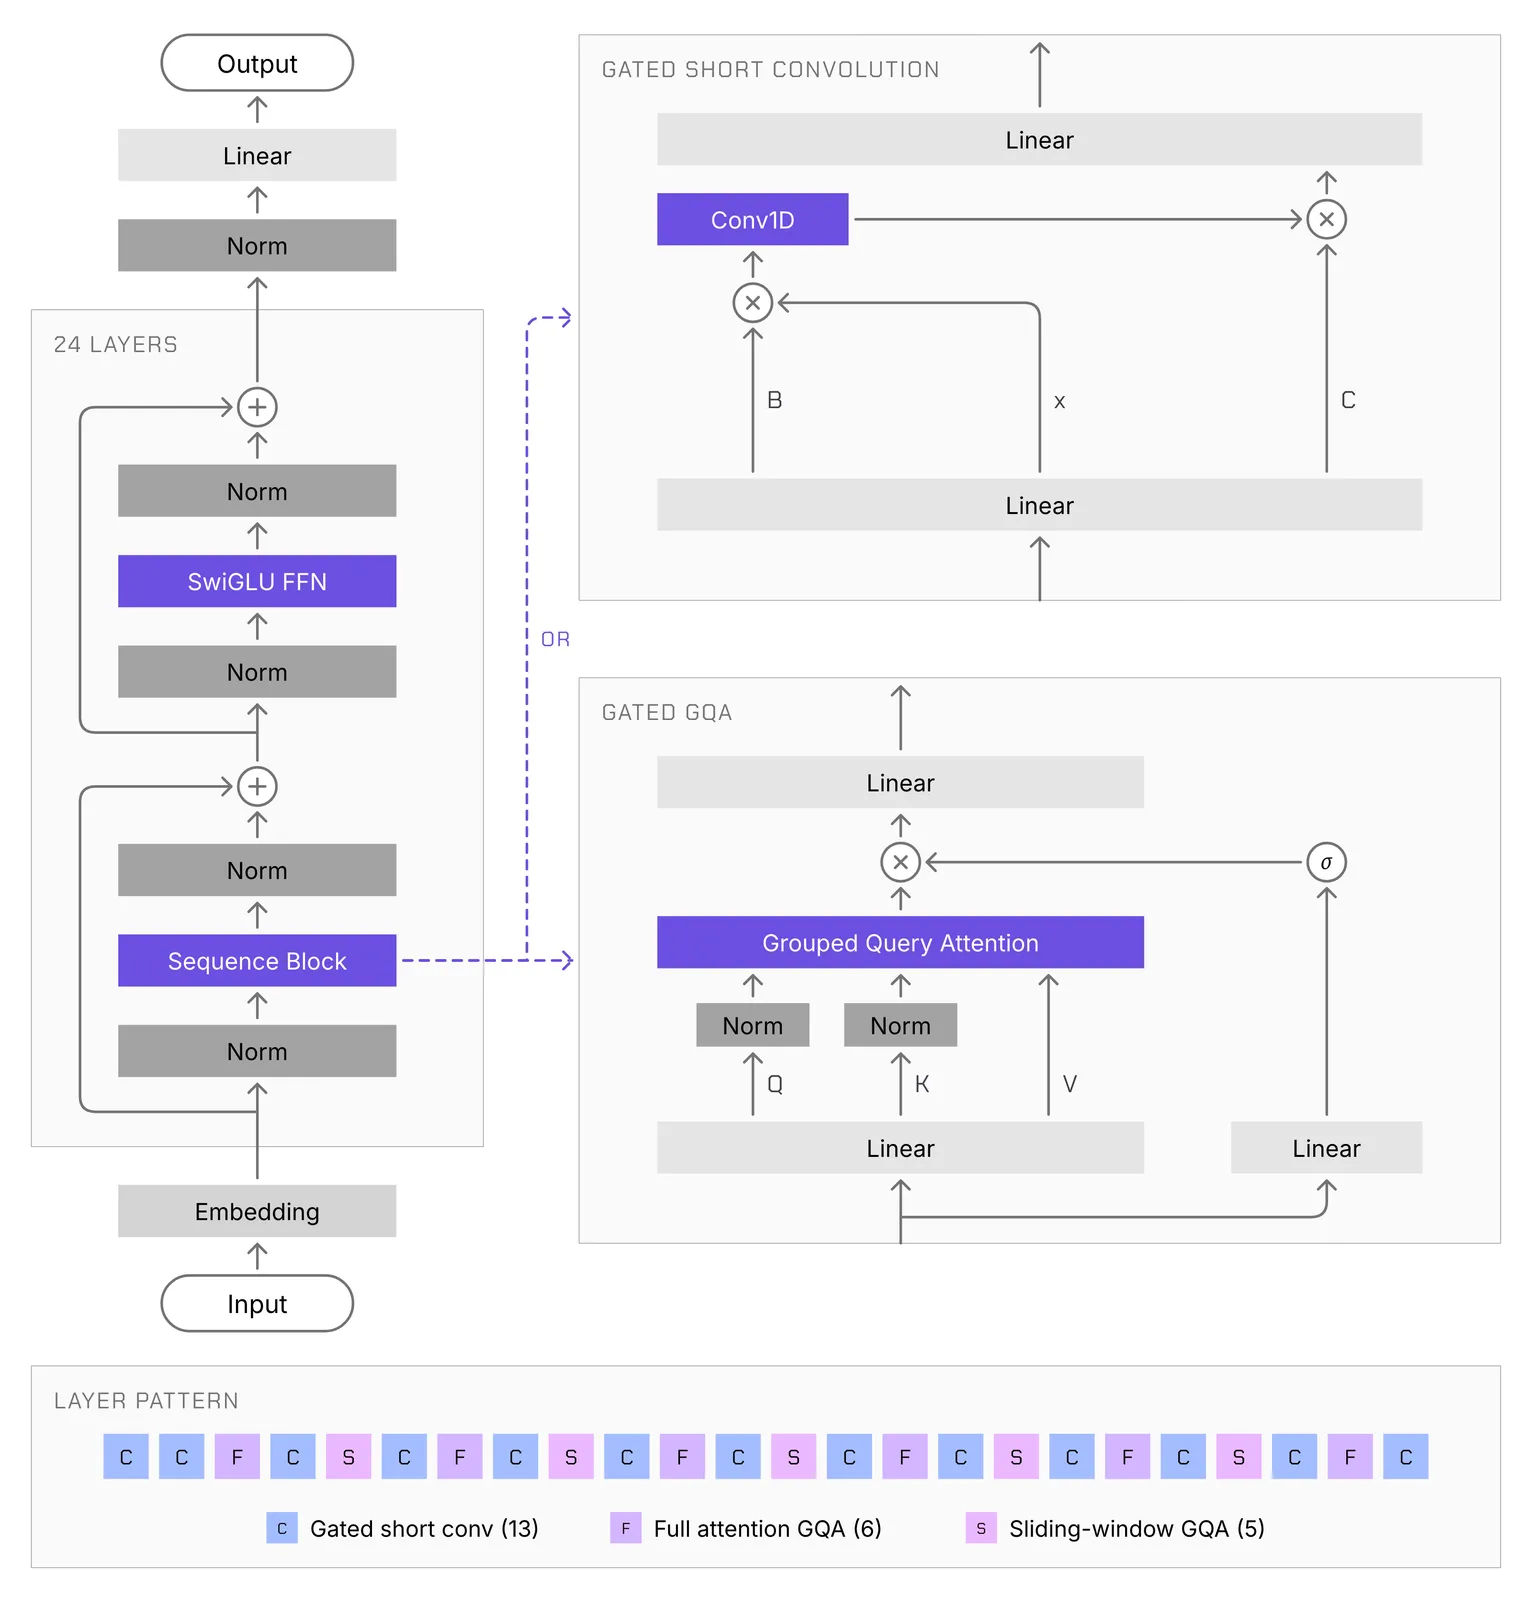
| active parameters | about 4B active parameters | |
| total parameters | 30B total parameters | |
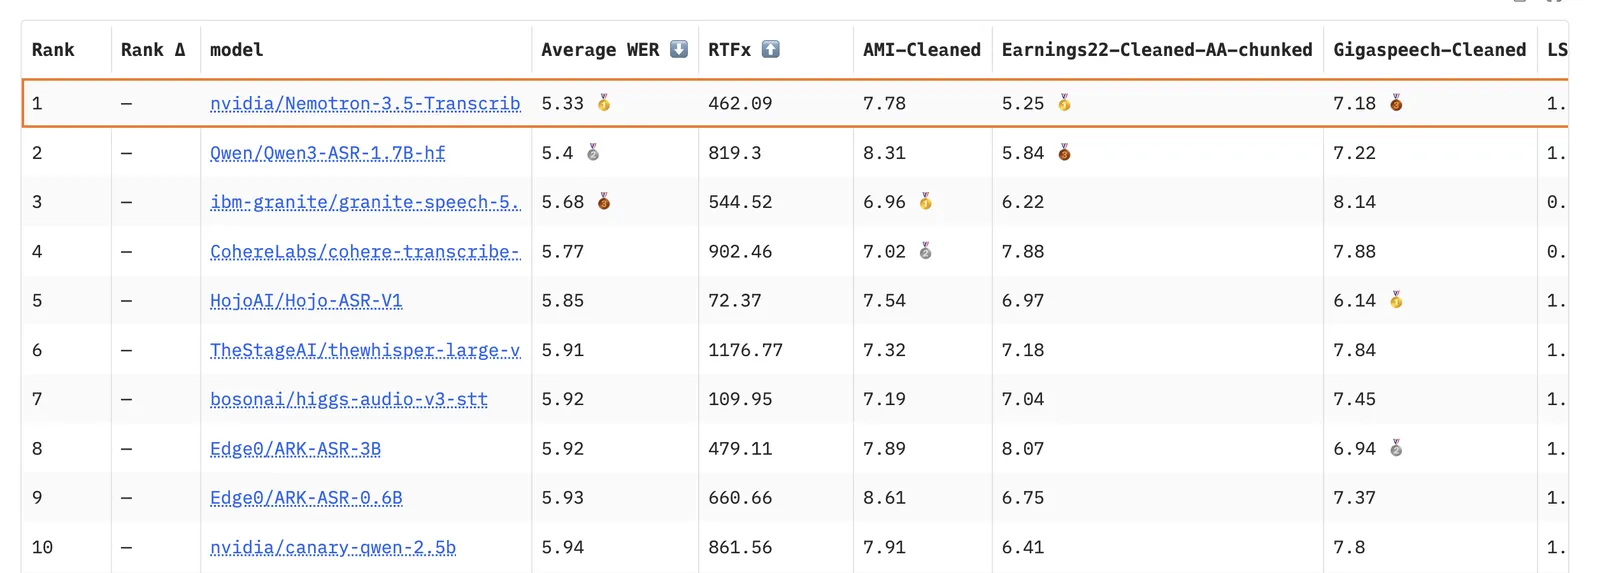
| English WER | 5.33% average WER | |
| public manifest hours | 463,062 hours |
The checkpoint transcribes 40 languages, translates 31 of them to or from English, and attributes speakers in 13.
The Hugging Face page lists it first among open-weight models on the English Open ASR track at 5.33% average WER.
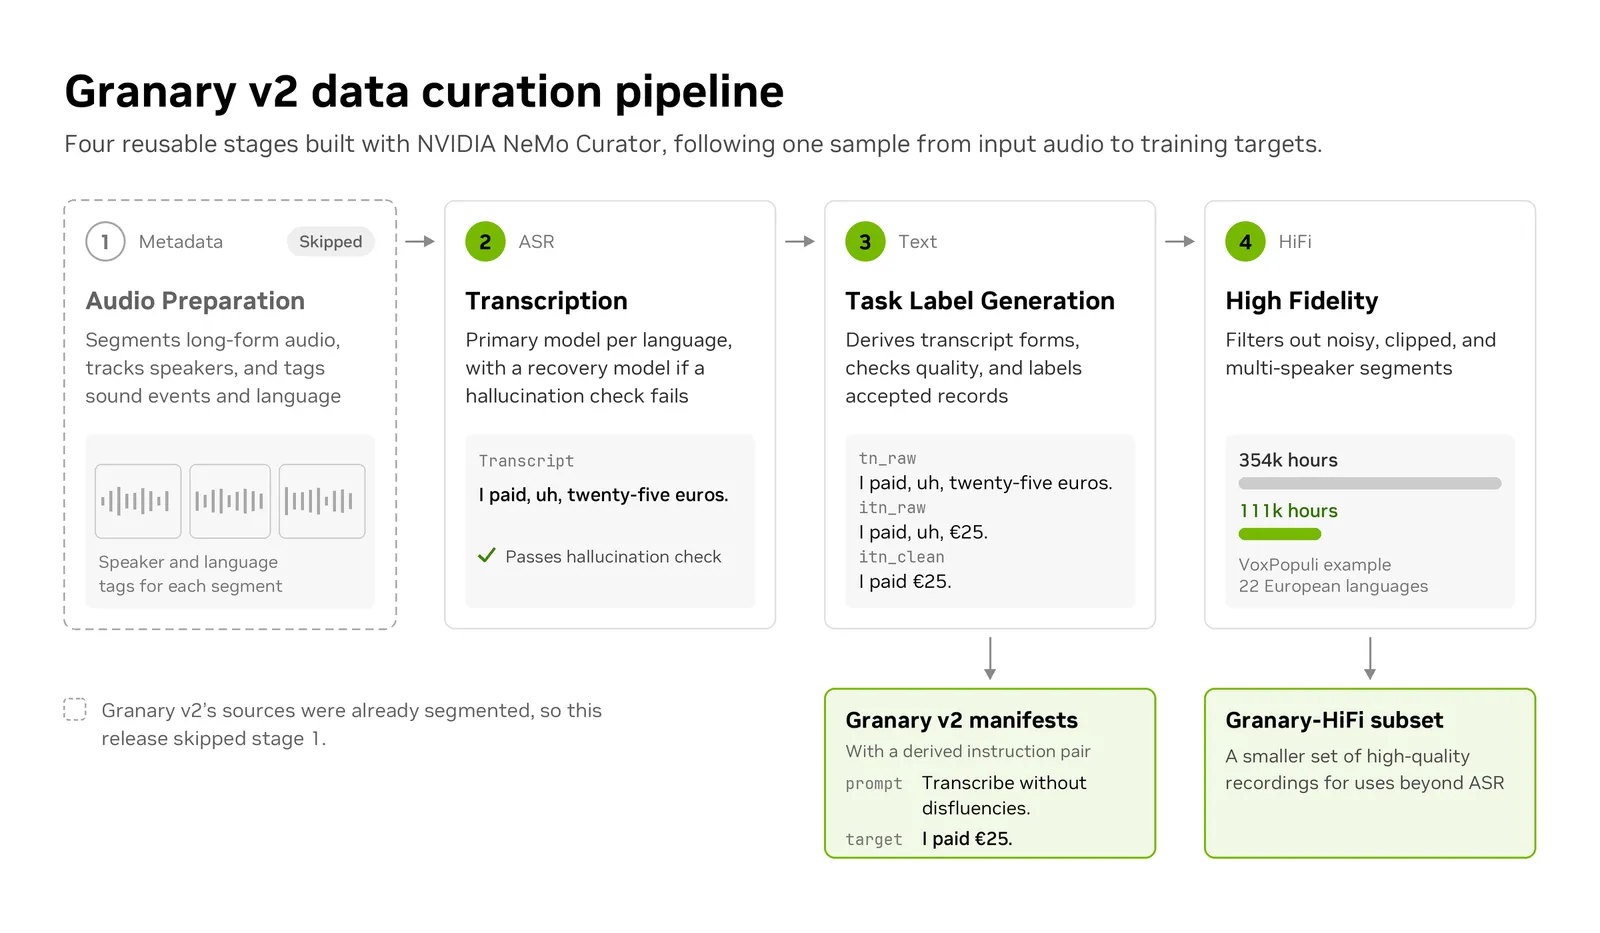
Figure 2 ties the accuracy claim to 2.80% AA-WER with about 4B active parameters inside a 30B-parameter model.
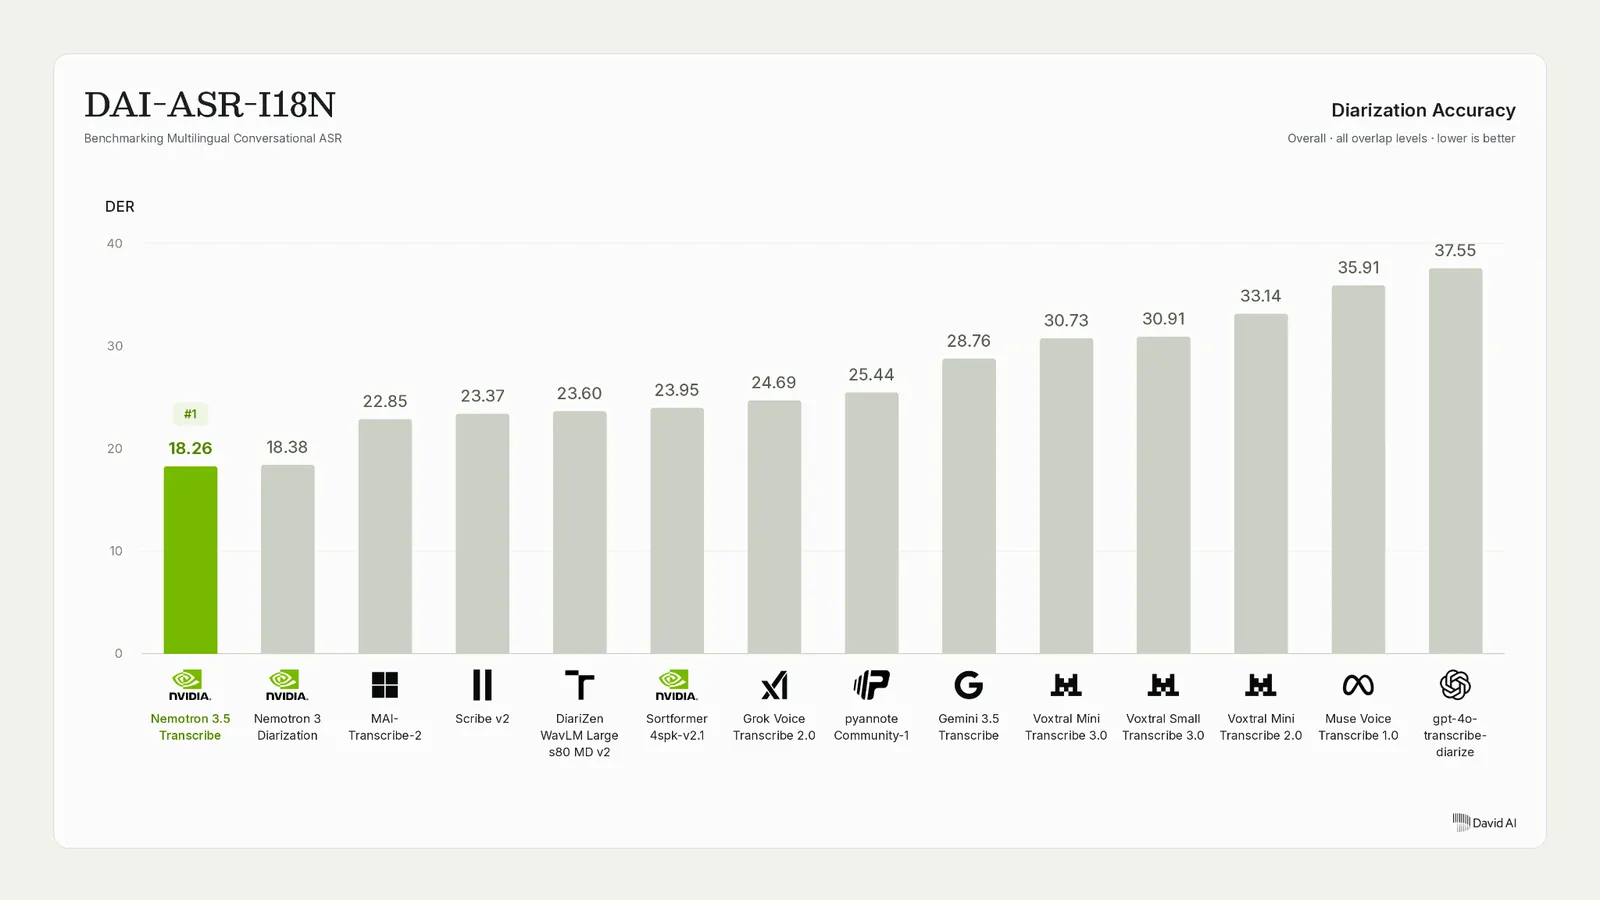
Figure 3 reports 18.26% DER across 21 languages, and Figure 4 reports 32.4% cpWER on VoiceArena.
Granary v2 adds a 463,062-hour manifest and a curation path that makes the data claim testable.
The desk reads this as a packaging shift rather than a new acoustic miracle.
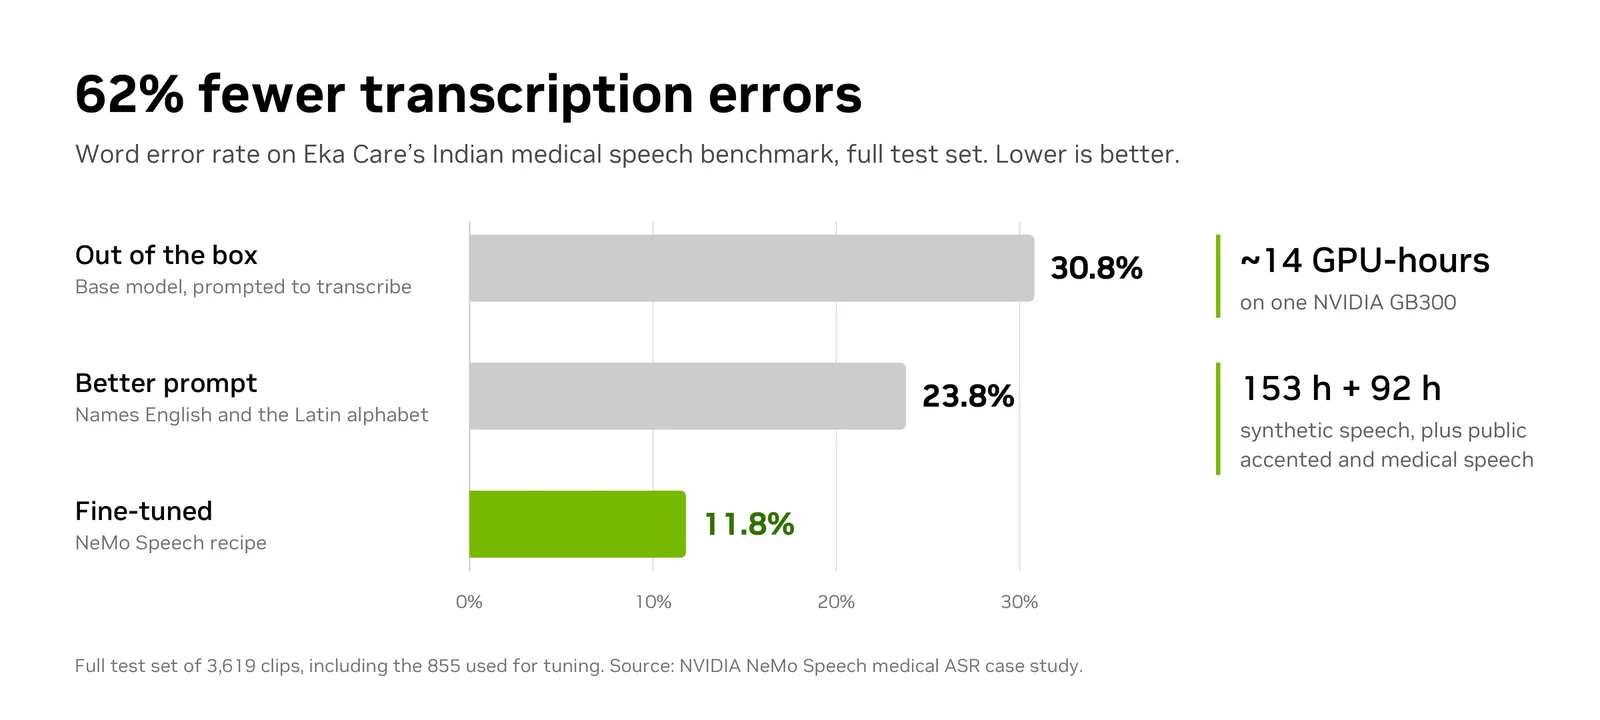
The page does not prove the checkpoint stays efficient on messy domain audio without fine-tuning.
Missing pieces include the full language lists, training mixture weights, full corpus list, and the quantized local-deployment date.
Those gaps matter because leaderboard wins cover public tracks, not the private vocabularies a hospital or call center would use in production.
The useful part is the 30B checkpoint with about 4B active parameters and the open Granary v2 data path. The unresolved part is domain audio and local quantization.
After github.com. We did not report this. The pictures, if any, are theirs.