Gemini 4 carbon: 59 points, 23 percent cheaper
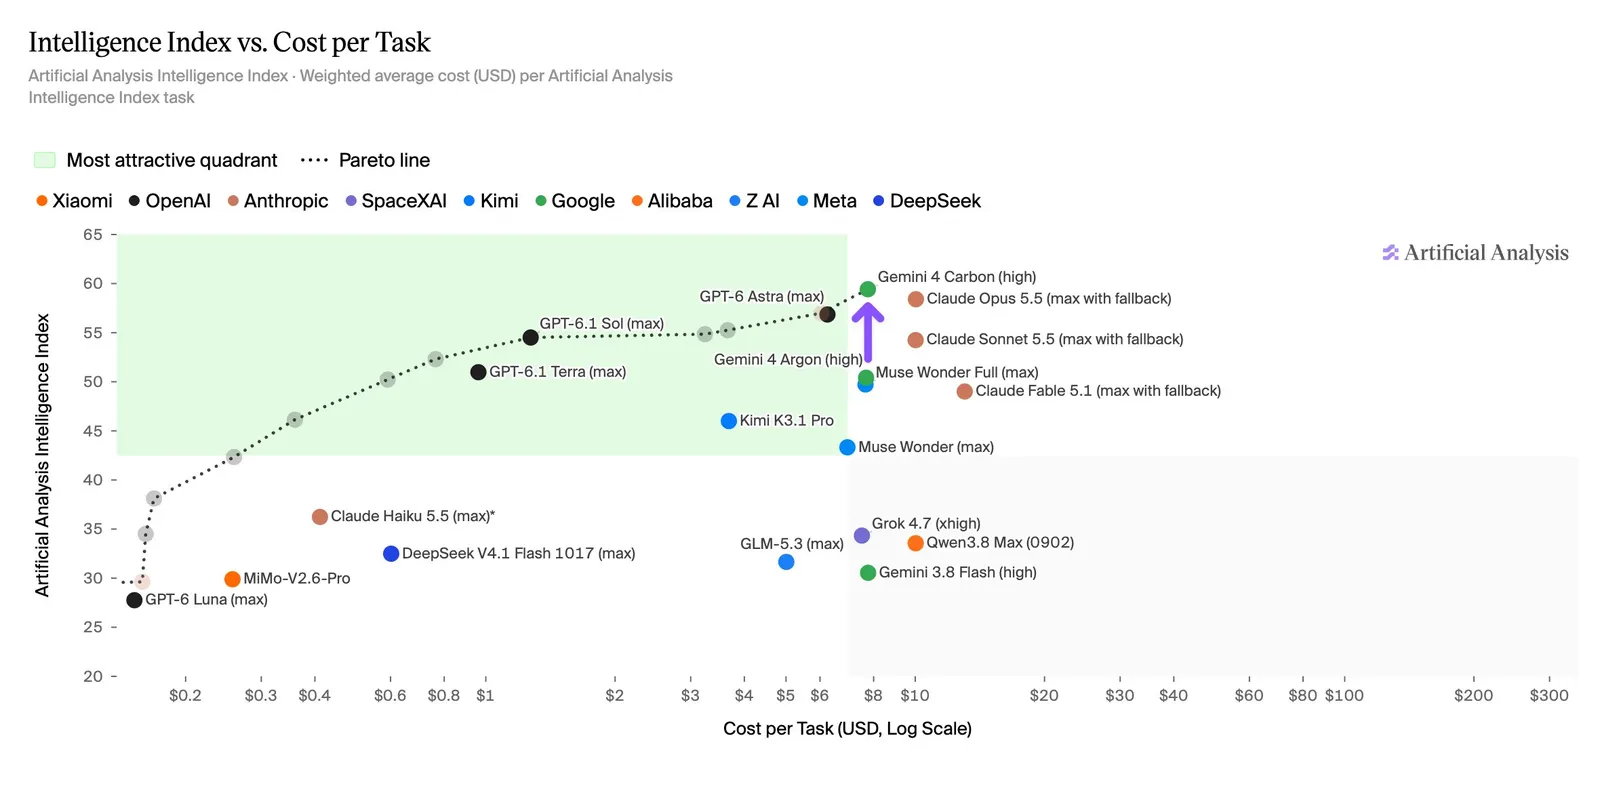
Gemini 4 Carbon scores 59 on the Artificial Analysis Intelligence Index v5 while costing approximately 23 percent less than Claude Opus 5.5 on a typical task.
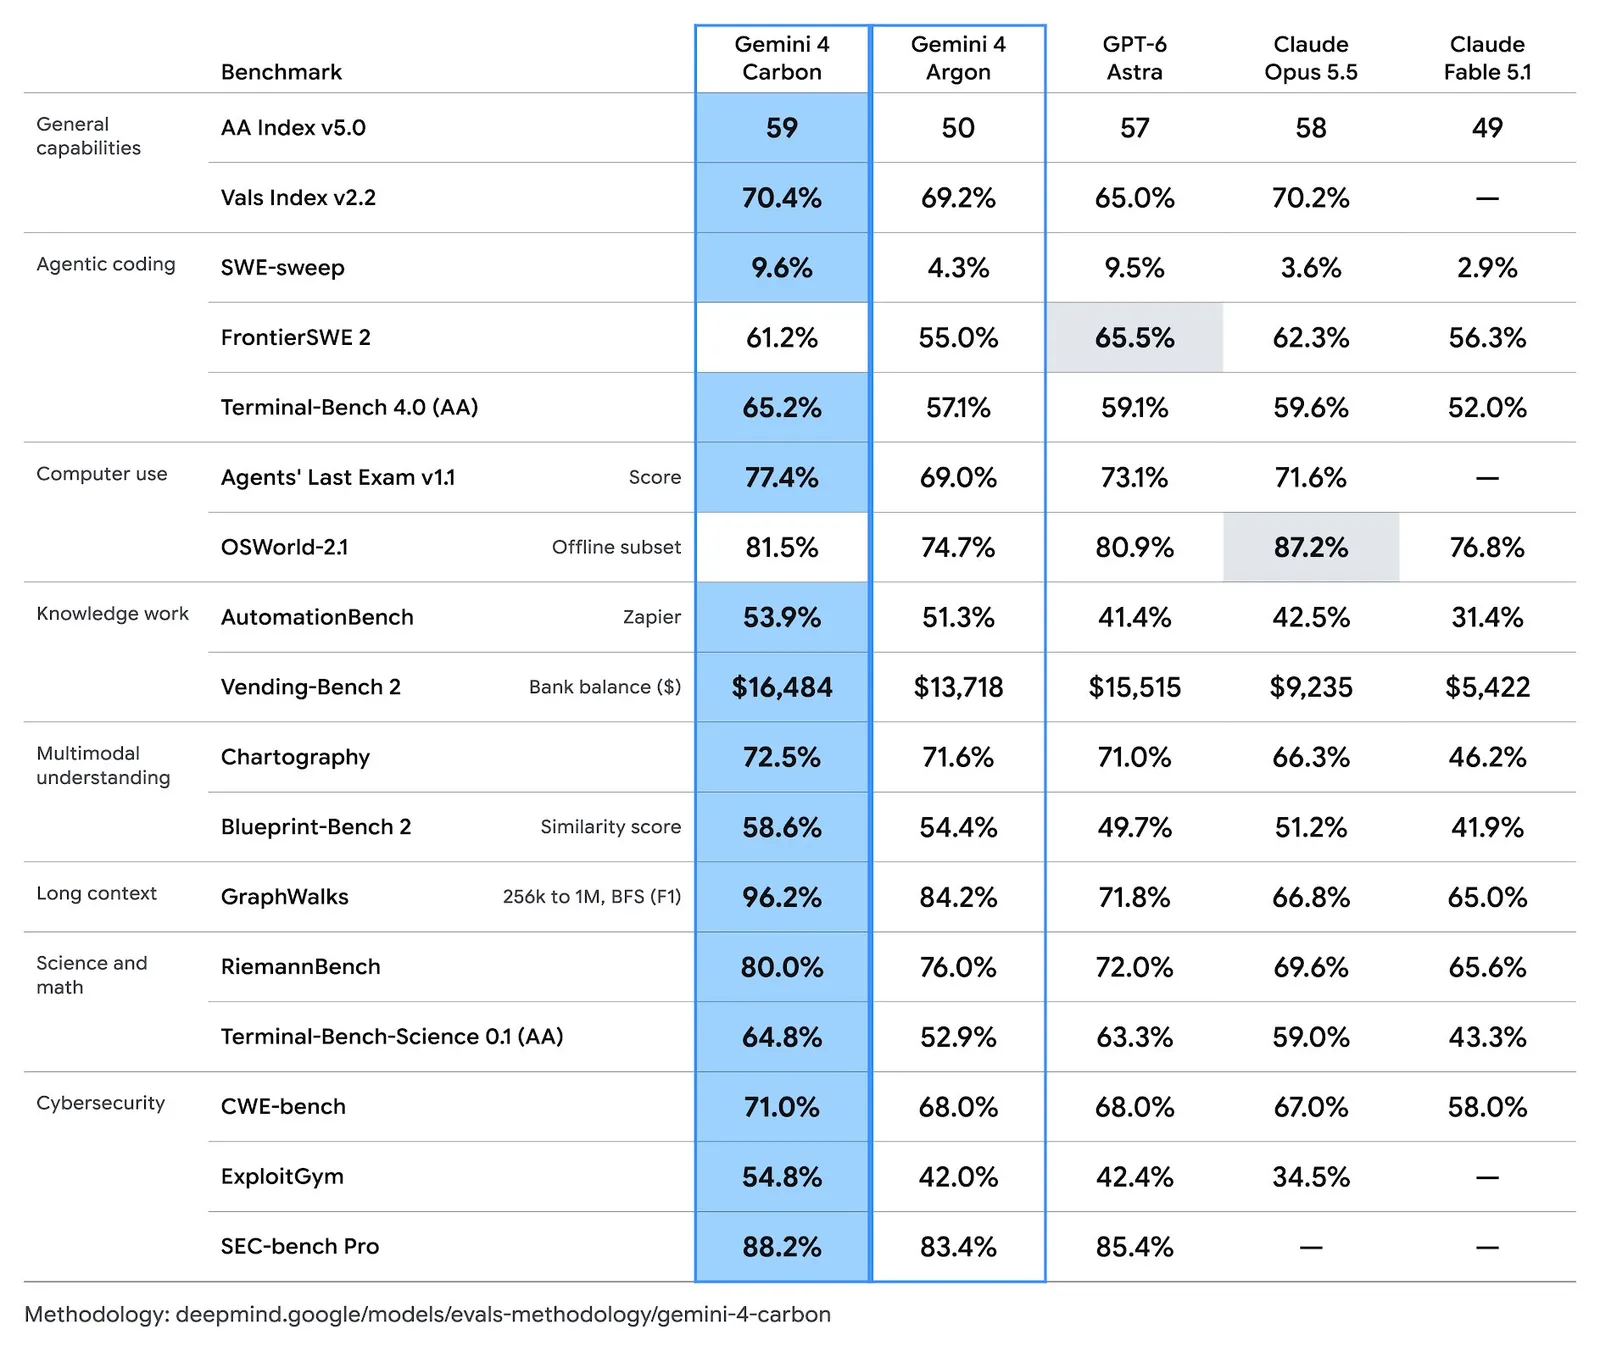
The new SOTA model sits above Claude Opus 5.5 and GPT-6 Astra on the same benchmark. The cost gap is the sharper number: 23 percent less per task, which is not a rounding error in a market where pricing is the primary differentiator.
Google shipped Carbon just two weeks after Argon, positioning it for extended agent workflows and the full cyber defense lifecycle. Access is restricted to selected security experts at launch, which limits the pool of users who can actually test the 59-point claim.
On security patches specifically, the model performs over 10x better than any publicly available model, a figure that does not appear on the index itself and therefore cannot be compared to the 59.
The Decoder, The Verge, and Wccftech all confirm the 59-point score and the 23 percent cost differential. What nobody measured: the maximum possible score on the v5 index, so 59 could be a ceiling or a midpoint. The 23 percent figure applies to a 'typical' task, not the full benchmark suite.
The 59-point score and the 23 percent cost gap are both confirmed across three outlets, but neither is anchored to a scale. Without knowing the index ceiling, 59 is a relative number, not an absolute one. The 23 percent figure is scoped to a 'typical' task, leaving open whether the gap widens or narrows across the full suite. The security-patch claim (10x) is a separate axis entirely and cannot be folded into the index comparison.
Die Brief desk. The claim is ours. Facts from Google DeepMind, The Verge AI, The Decoder, Wccftech. Pictures, if any, are from those pages.