Nvidia's open Nemotron 3.5 Transcribe activates 4B of 30B weights per step
Nvidia's open Nemotron 3.5 Transcribe activates about 4 billion of its 30 billion weights per step, so it fits on a single GPU.
| Nemotron 3.5 Transcribe | |
|---|---|
| parameters | 30 billion |
| active parameters | about 4 billion per step |
| transcription languages | 40 |
| translation languages | 31 |
| speaker recognition languages | 13 |
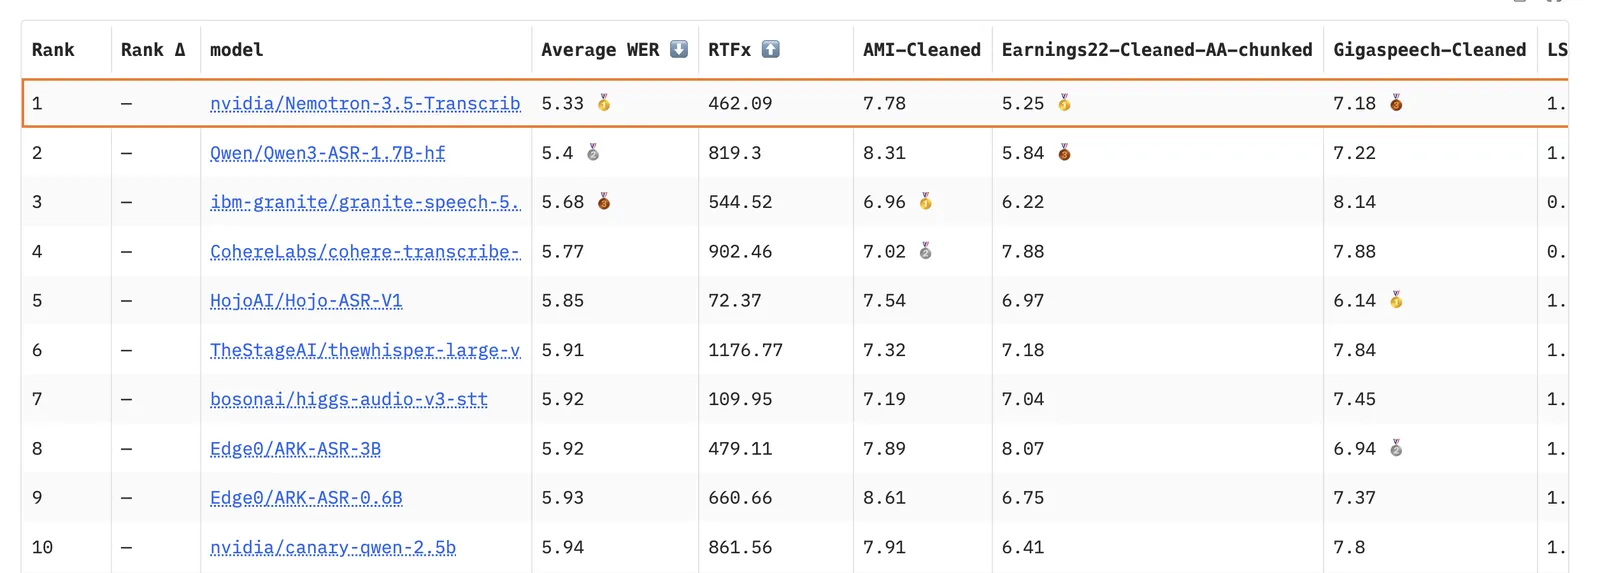
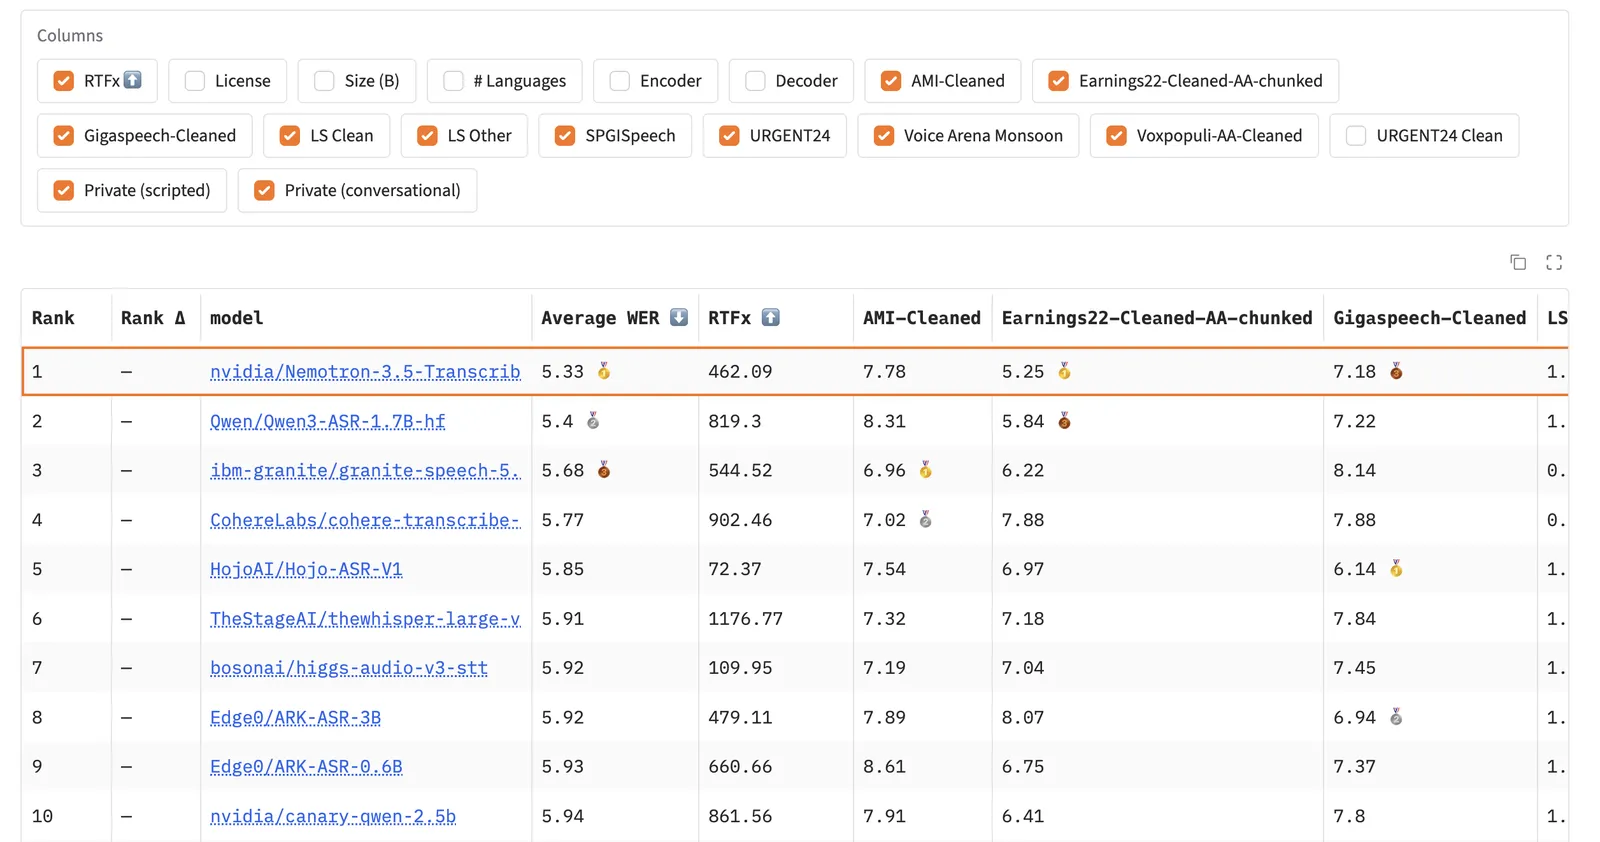
| WER (Hugging Face) | 5.33 percent |
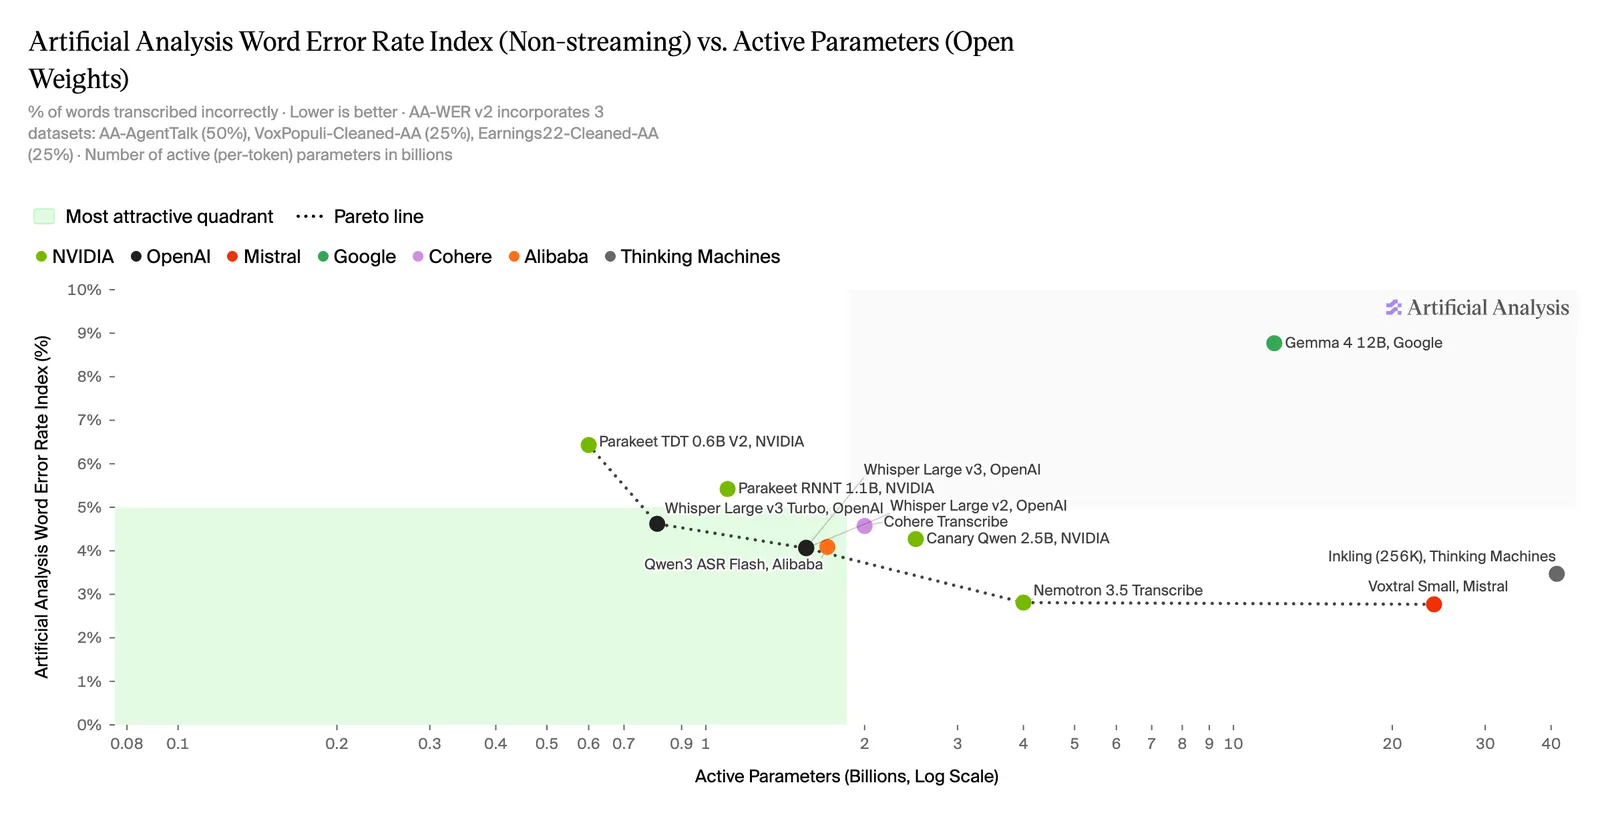
| WER (Artificial Analysis) | 2.81 percent |
| Granary v2 hours | 844,000 hours |
The 30 billion total is not the cost driver. The Decoder report says only about 4 billion parameters are active per step, and the model runs on one GPU.
It transcribes 40 languages, translates 31 of them to or from English, and identifies speakers in 13. Recordings can run up to an hour and include up to eight speakers.
Compute is the practical limit. On RTX PRO 6000 Blackwell Server Edition hardware, the model processes 100 hours of audio in under three minutes at NVFP4 precision.
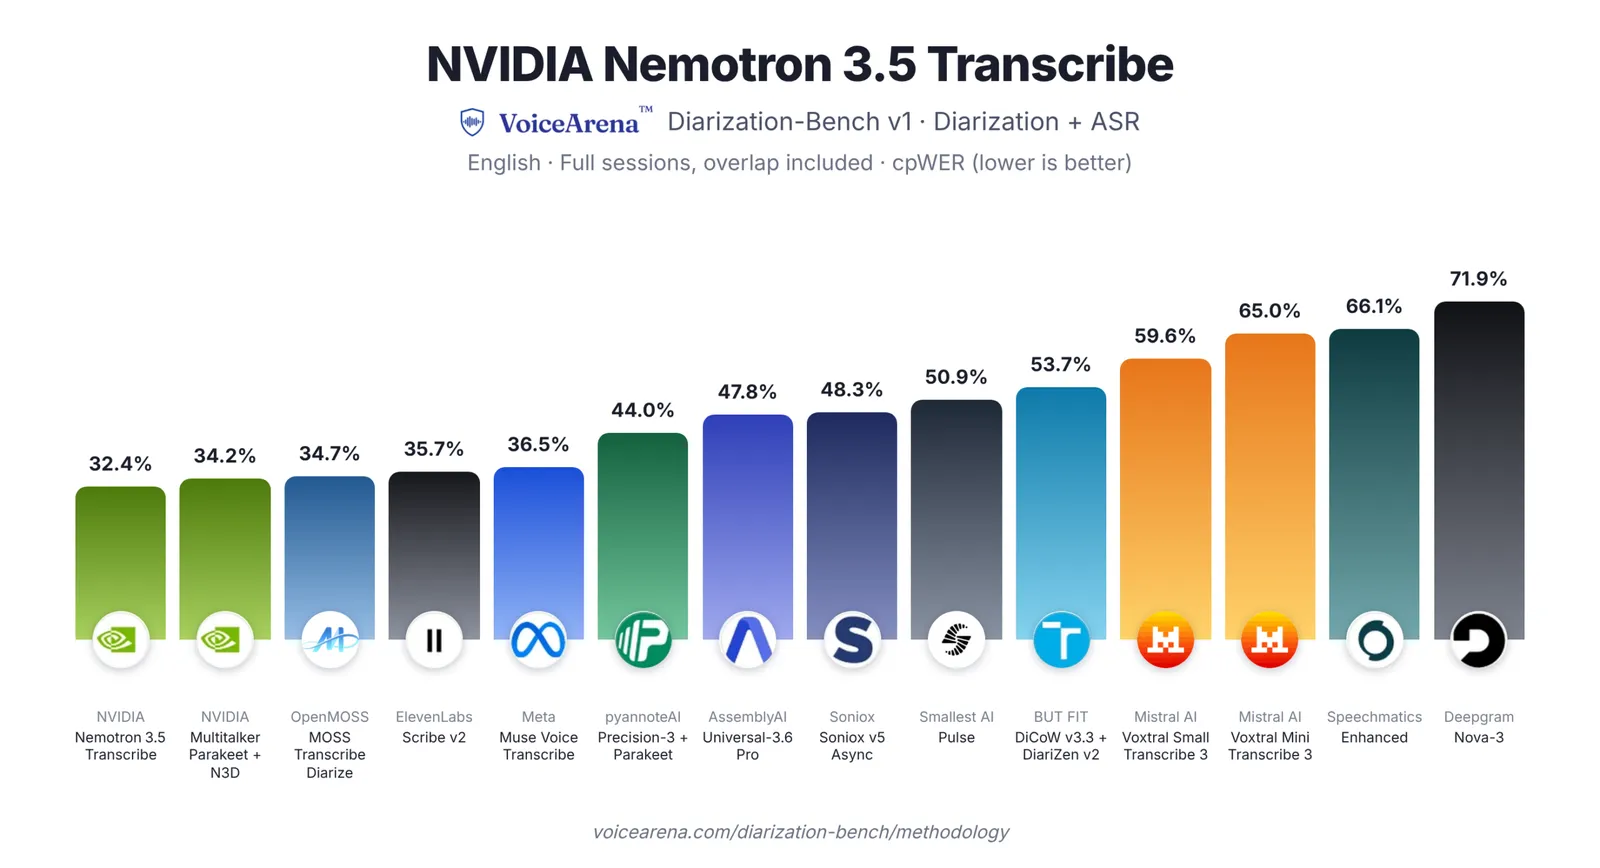
The accuracy edge is thin. Hugging Face's English Open ASR Leaderboard lists a 5.33 percent word error rate, while Artificial Analysis reports 2.81 percent, close to Voxtral Small's 2.77 percent.
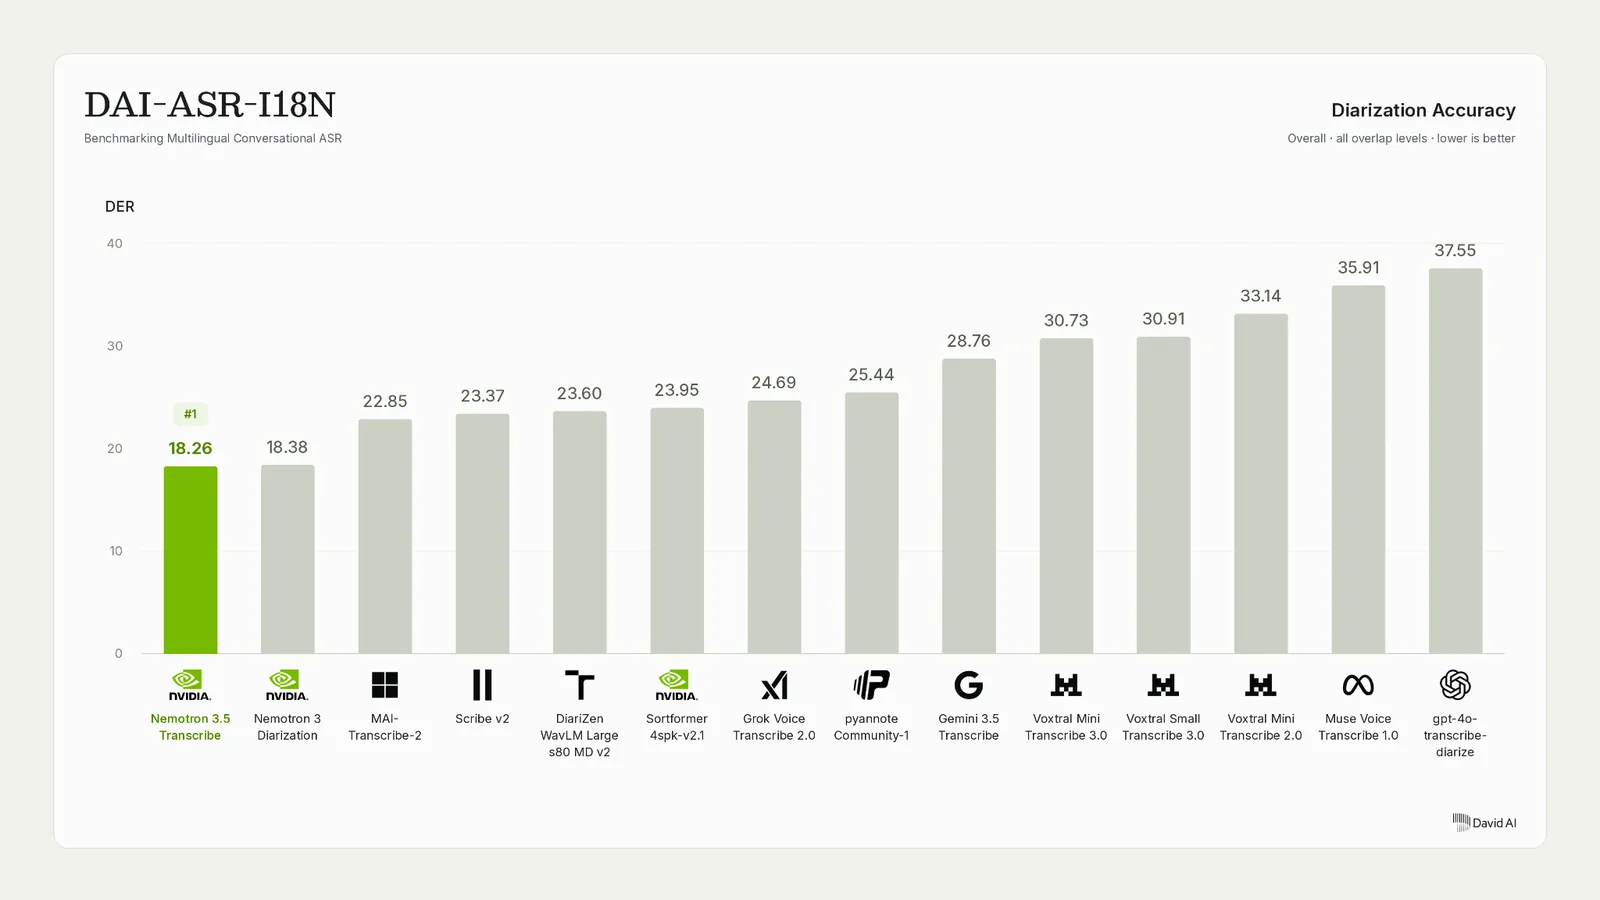
Speaker attribution in mixed-language, overlapping speech outside the tested sets remains unmeasured. The 844,000-hour Granary v2 dataset may not cover a specific clinic, court, or factory floor.
Buyer choice should turn on speaker attribution and language coverage, not raw WER. The document does not measure cost per hour of audio, latency for live streams, or accuracy in overlapping non-English speech.
Lead with active steps, keep the caveat about unmeasured cost.
After techcommunity.microsoft.com. We did not report this. The pictures, if any, are theirs.