LFM2 report sets the edge budget at 1.5B active parameters in an 8.3B MoE
In the LFM2 report, 1.5B active parameters set the edge CPU budget for an 8.3B-total mixture-of-experts variant.
| LFM2 | |
|---|---|
| parameters | 350M-8.3B |
| active parameters | 1.5B active |
| context | 32K |
| IFEval | 79.56% (LFM2-2.6B) |
| GSM8K | 82.41% (LFM2-2.6B) |
| training tokens | 10-12T tokens |
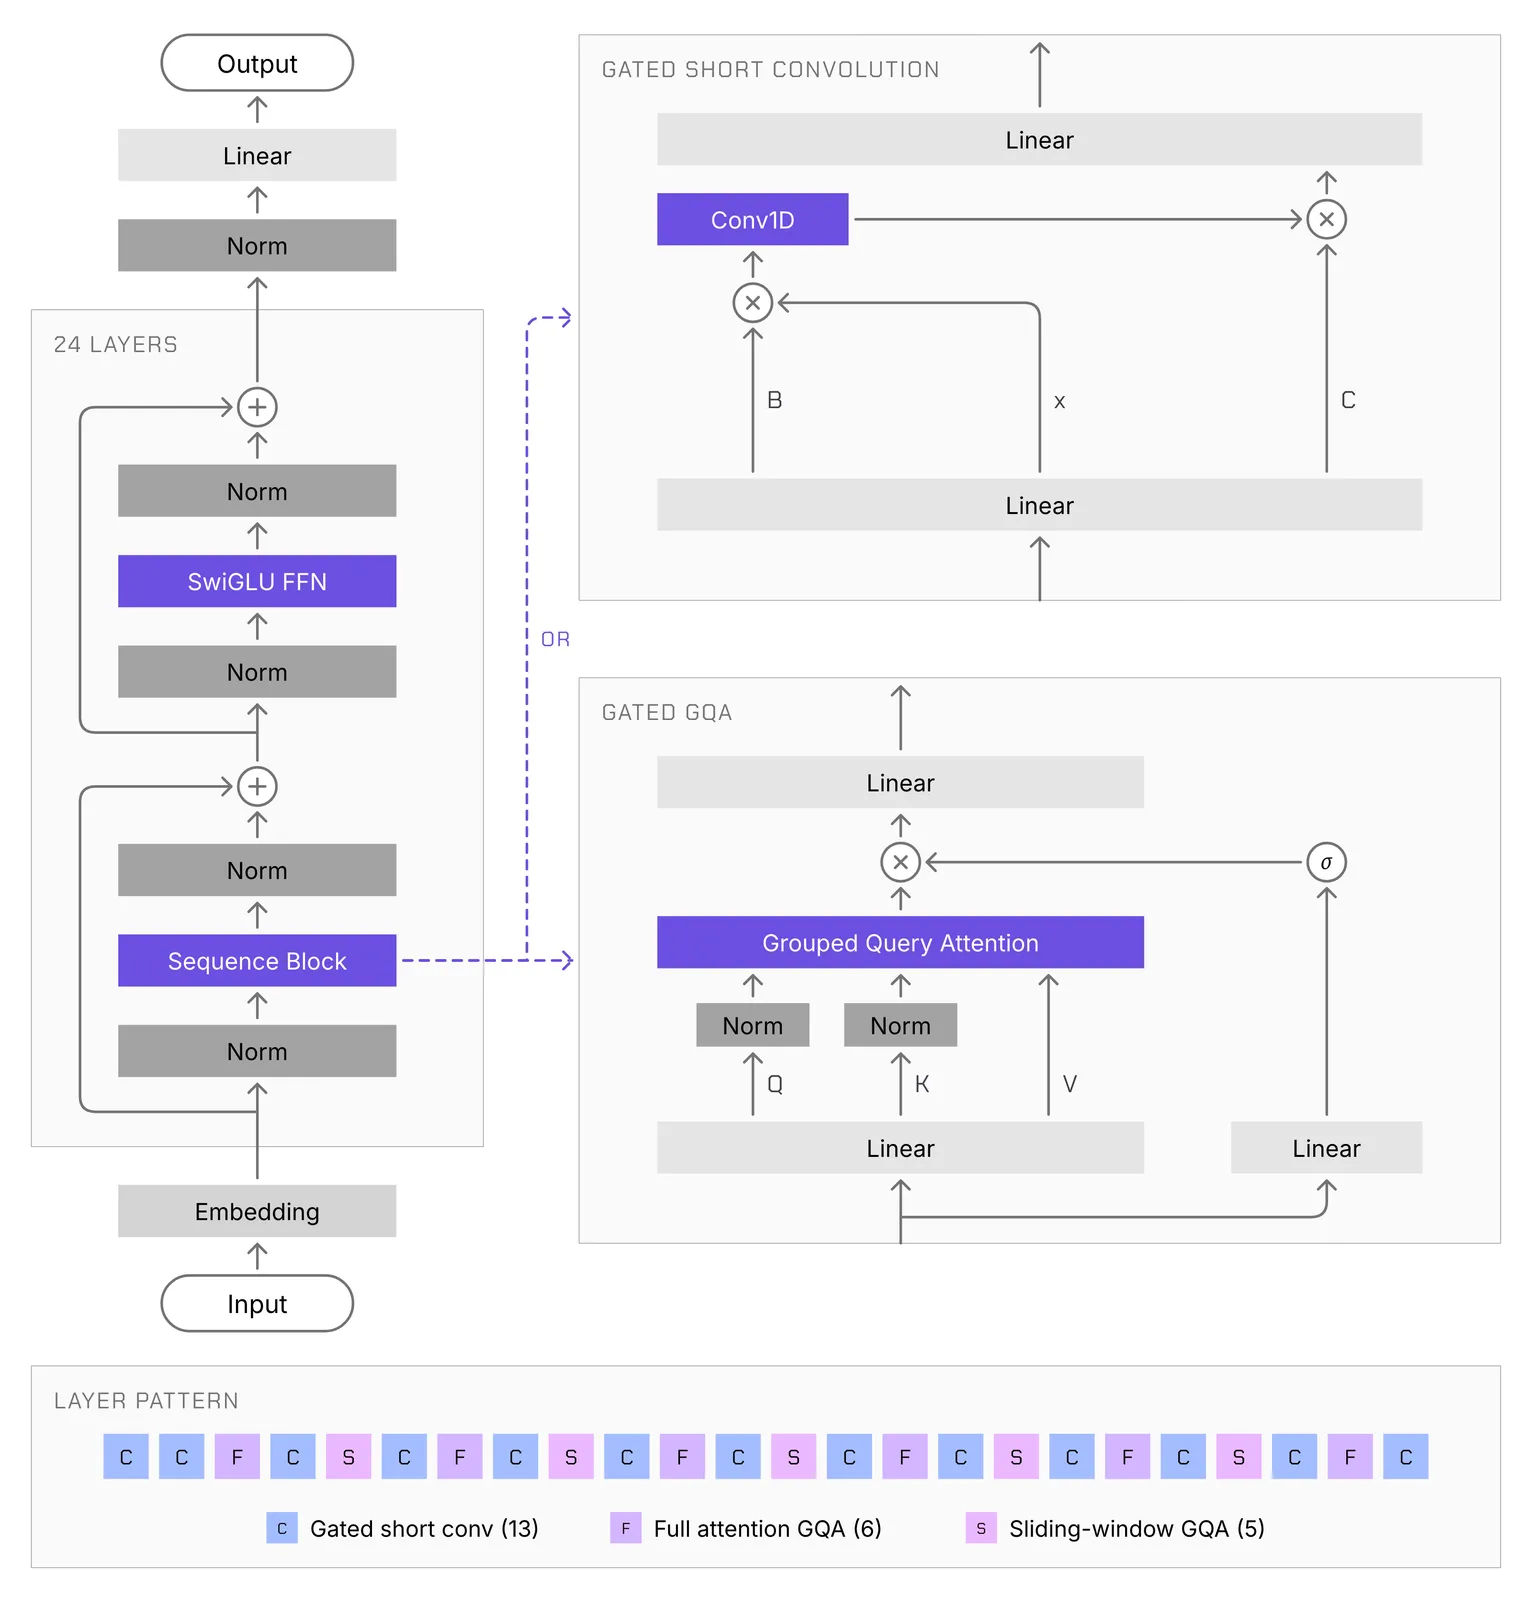
The report also lists dense sizes from 350M to 2.6B, a 32K context length, and open weights for ExecuTorch and vLLM. Its architecture search runs under edge latency and memory constraints, producing a hybrid backbone of gated short convolutions and grouped query attention.
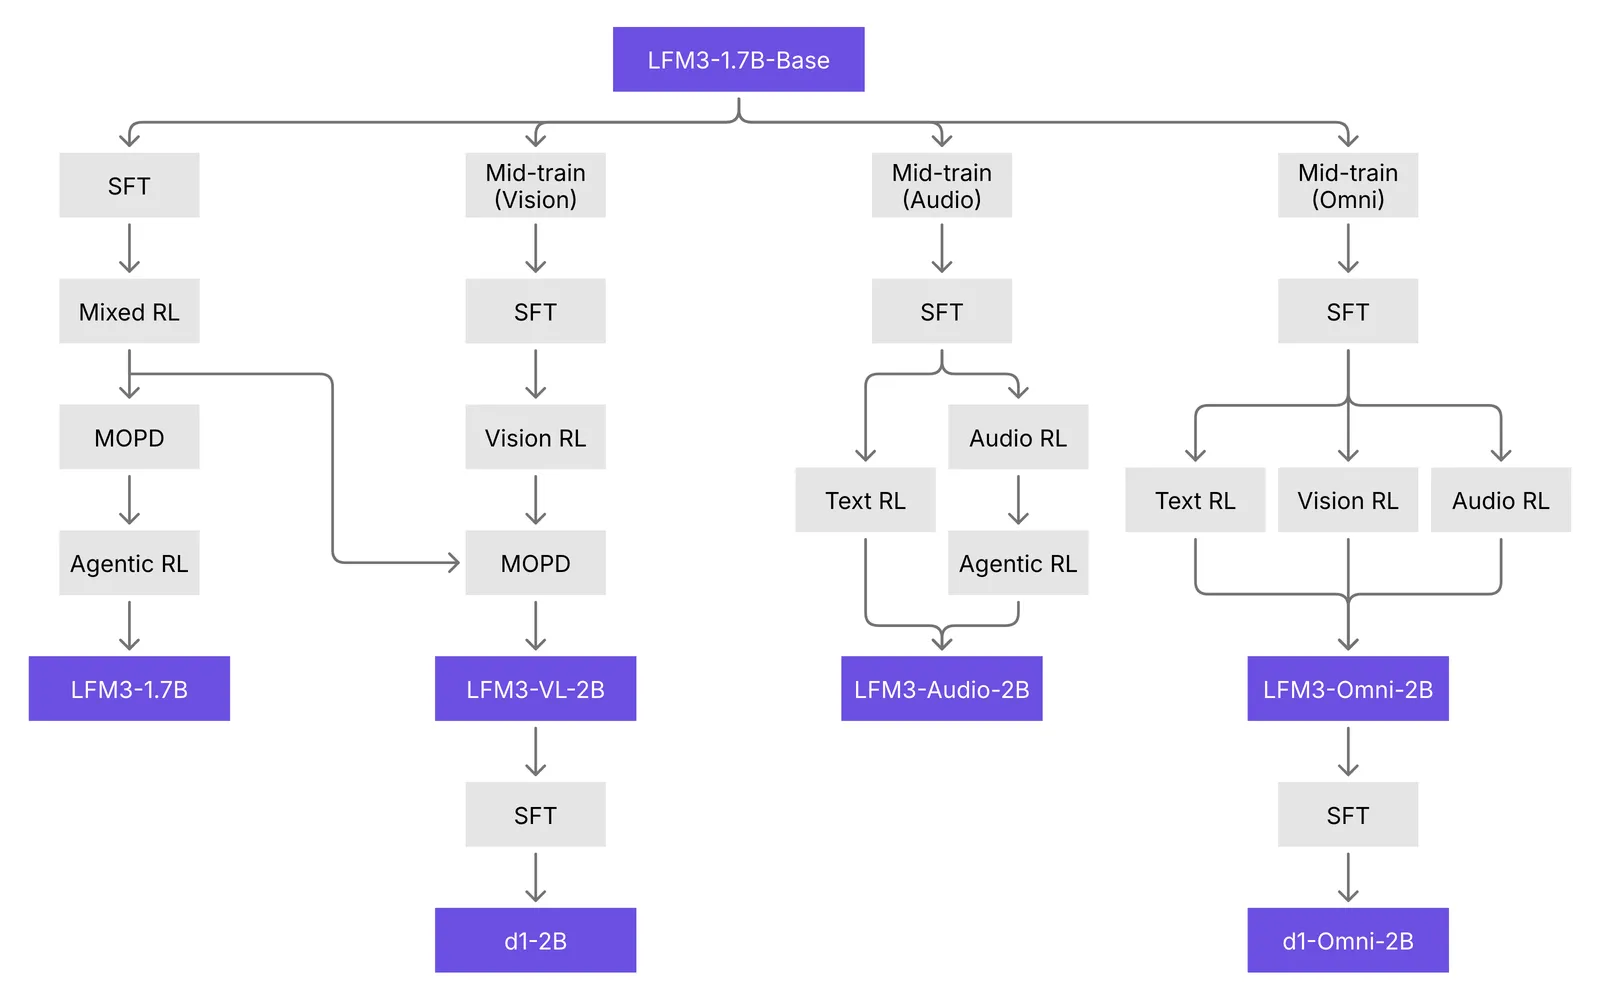
It reports up to 2x faster prefill and decode on CPUs compared with similarly sized models. Active parameters set per-token compute, while total parameters set weight memory.
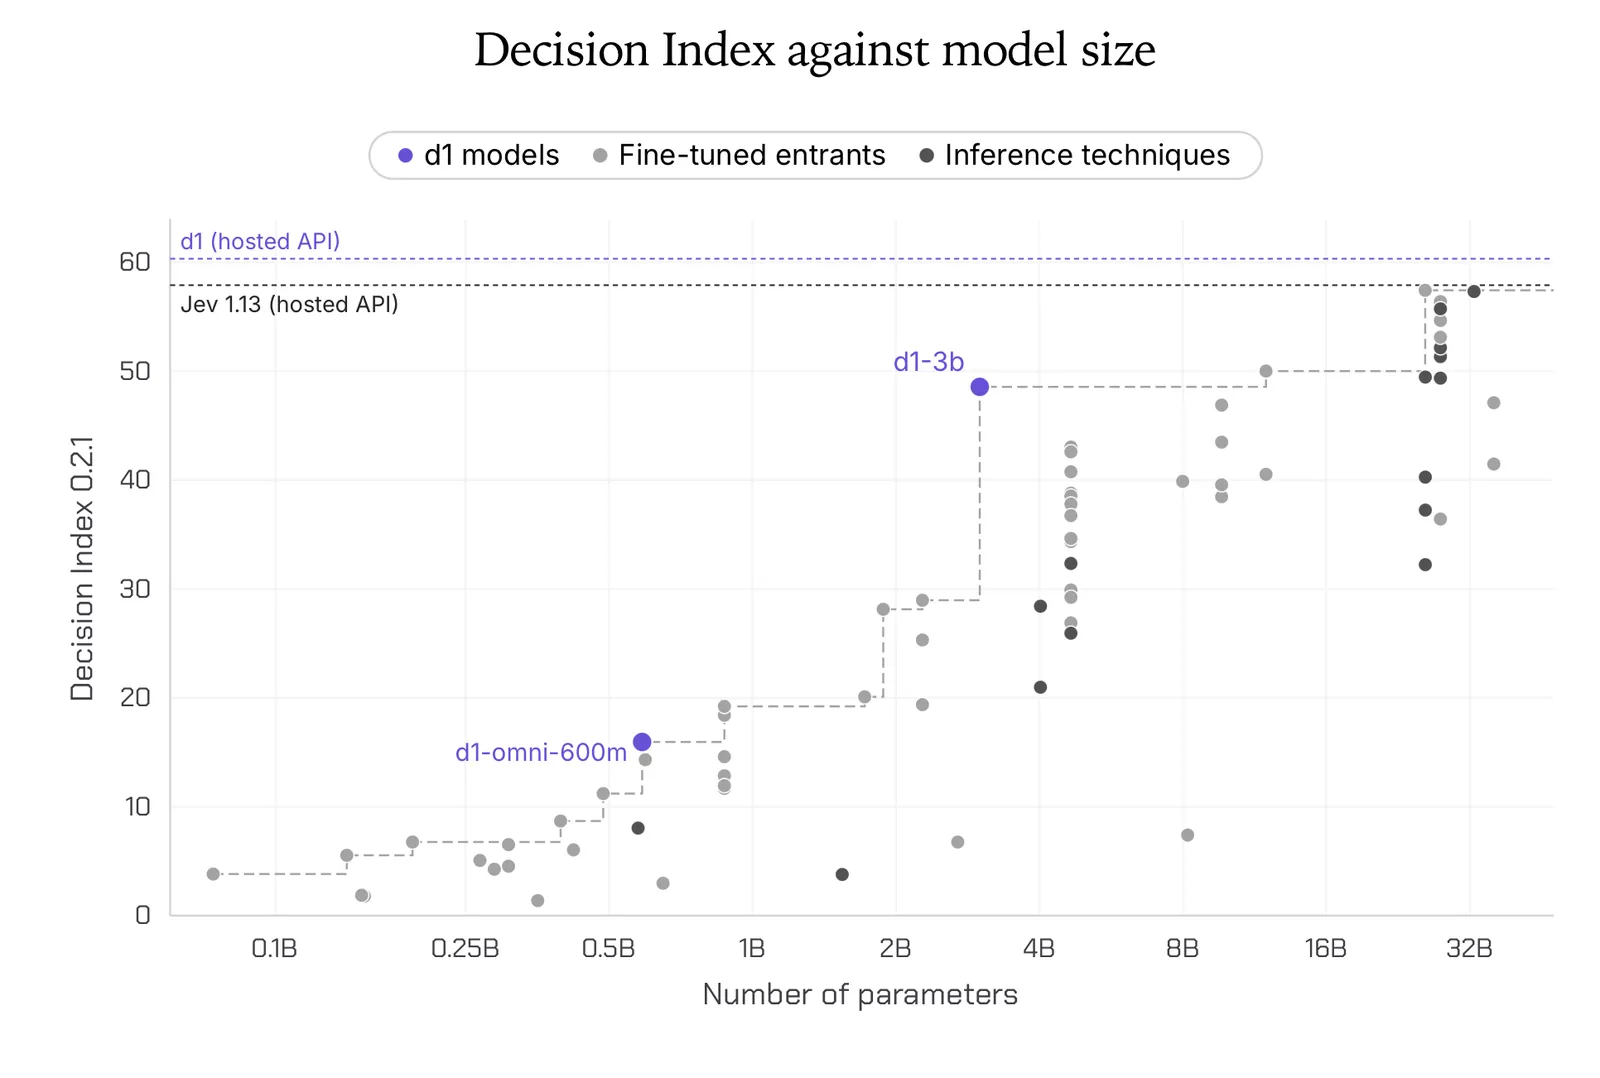
The document does not state LFM3 weights, a 24B-A2B variant, or Decision Index scores. It also omits price, node, or power figures for the variant.
The report supports the 1.5B-active MoE and does not support the LFM3 24B-A2B claim.
After arxiv.org. We did not report this. The pictures, if any, are theirs.