OpenAI ties Retell's 100M monthly calls to GPT-6 Astra
The OpenAI page says Retell now handles more than 100 million monthly calls, with OpenAI models generating responses for 80% of those calls.
| Retell AI | |
|---|---|
| monthly calls | 100M+ |
| customer resolution rates | 80%+ |
| OpenAI tokens consumed | 1 trillion |
| annual revenue run rate per employee | $1.6M |
| businesses | more than 4,000 |
| OpenAI model share | 80% |
| call volume early 2026 | 30 million |
| call volume September | more than 100 million |
100 million monthly calls is the number the OpenAI page gives Retell. It does not prove that GPT-6 Astra produced every one of those calls, or that the benchmark lead is an independent measurement. The filing also says OpenAI models generate responses for 80% of calls and that customers achieve resolution rates above 80%.
Die Brief reads the constraint as model dependency, not proof of quality. If 80% of calls run on OpenAI models and 1 trillion tokens have been consumed, Retell's cost and latency posture are tied to OpenAI's pricing and availability. A buyer should treat the 80% resolution figure as a customer-reported outcome, not a lab-verified score.
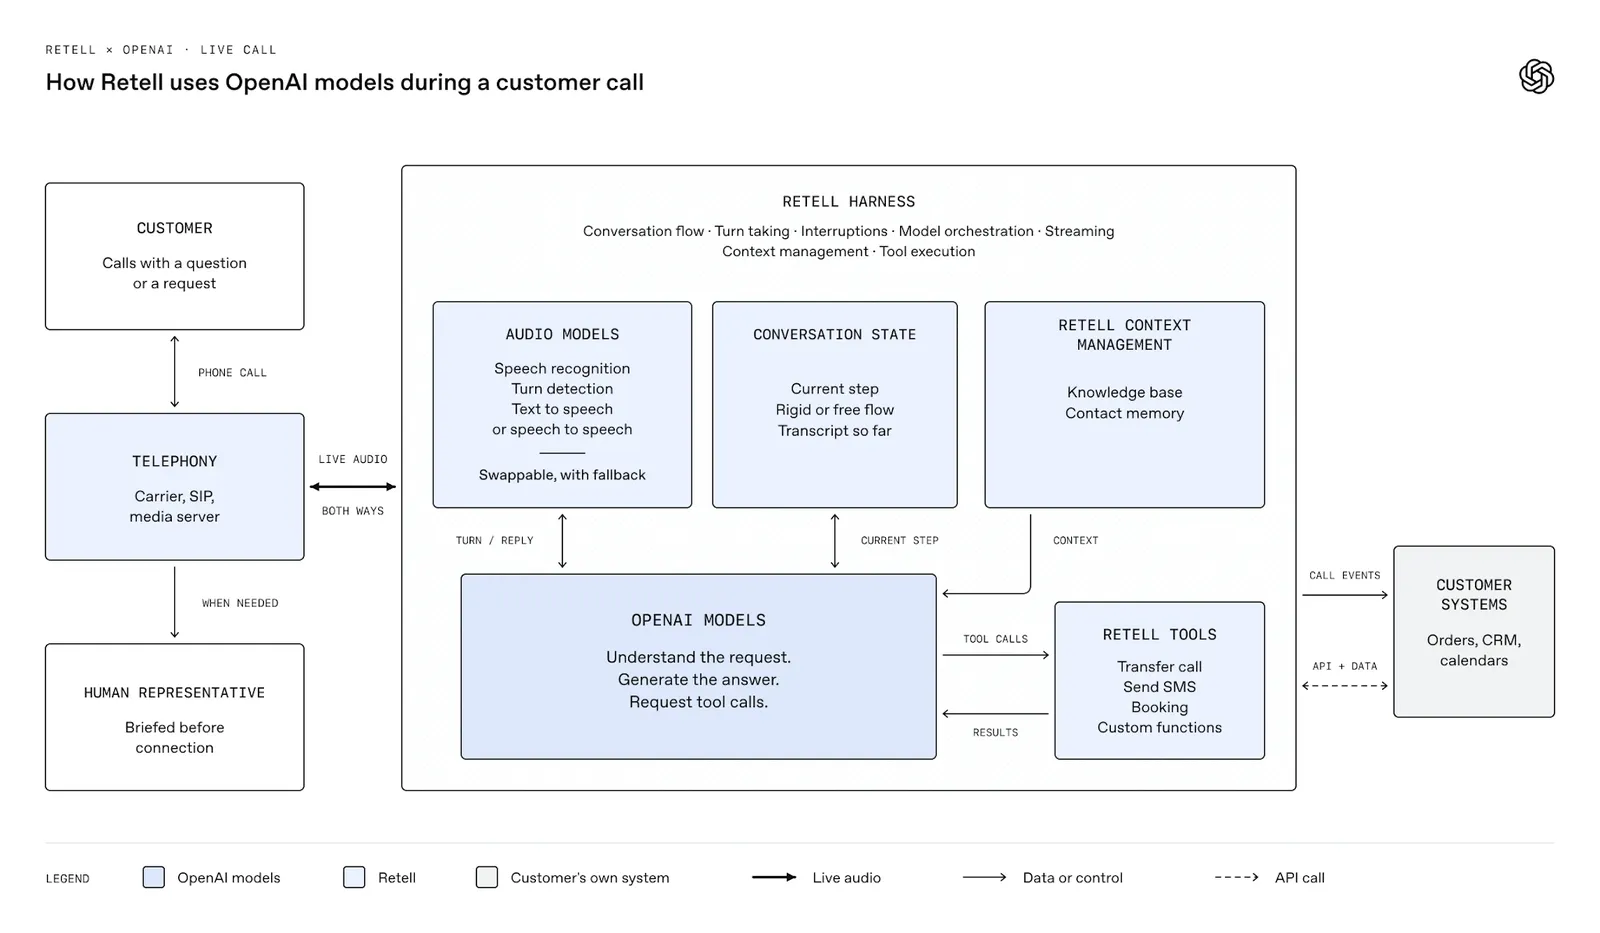
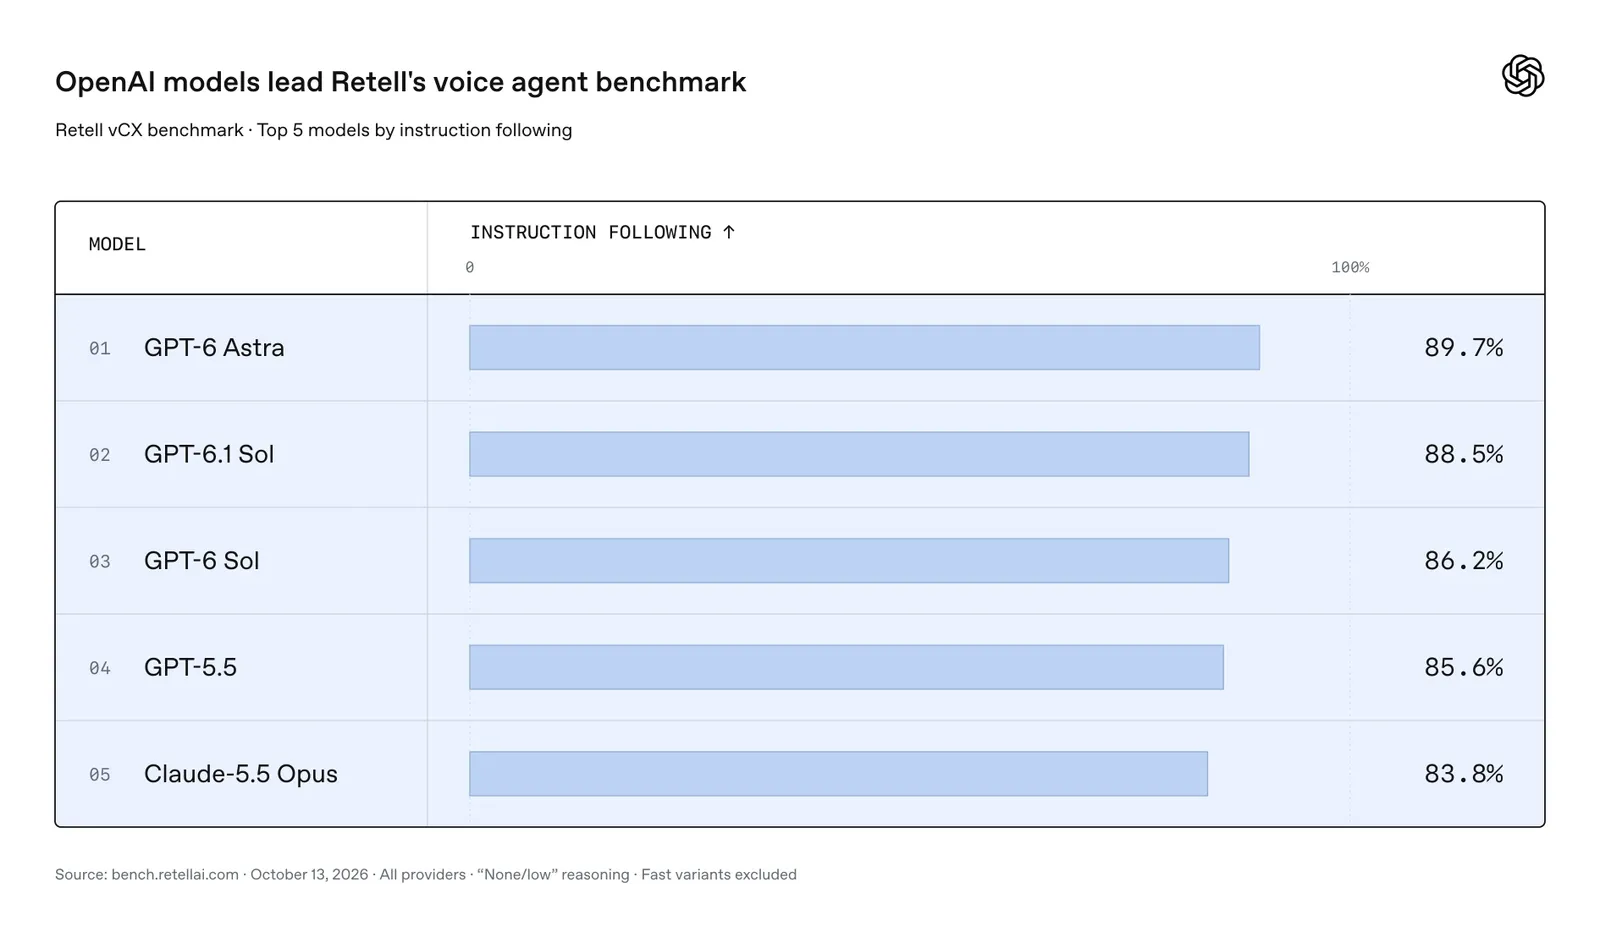
The document leaves the benchmark score, token cost per call, and latency under production load unmeasured. It names GPT-6 Astra as the top model on Retell's benchmark, but it does not state the score, the test set, or who ran the test.
Die Brief reads the constraint as model dependency, not proof of quality. A buyer should treat the 80% resolution figure as a customer-reported outcome, not a lab-verified score.
The document does not state the benchmark score, token cost per call, or production latency.
The page ties call volume to OpenAI model usage, so model pricing and availability constrain Retell's economics. The benchmark and resolution claims are not independently measured in the document.
After openai.com. We did not report this. The pictures, if any, are theirs.