Apertus 1.5 lengthens the context window and folds images and audio into tokens
Images and audio now enter Apertus 1.5 as tokens, expanding the context window to 262,144.
| 8B | 70B | |
|---|---|---|
| Model size | 8B | 70B |
| Context window | 262,144 tokens | 262,144 tokens |
| Additional pretraining tokens | 4 trillion | 2 trillion |
| Total pretraining tokens | 19T | 17T |
| Image token cost | 1,024 tokens per 512×512 image | 1,024 tokens per 512×512 image |
| Audio token rate | 40 tokens per second | 40 tokens per second |
| License | Apache 2.0 | Apache 2.0 |
| Release date | July 24, 2026 | July 24, 2026 |
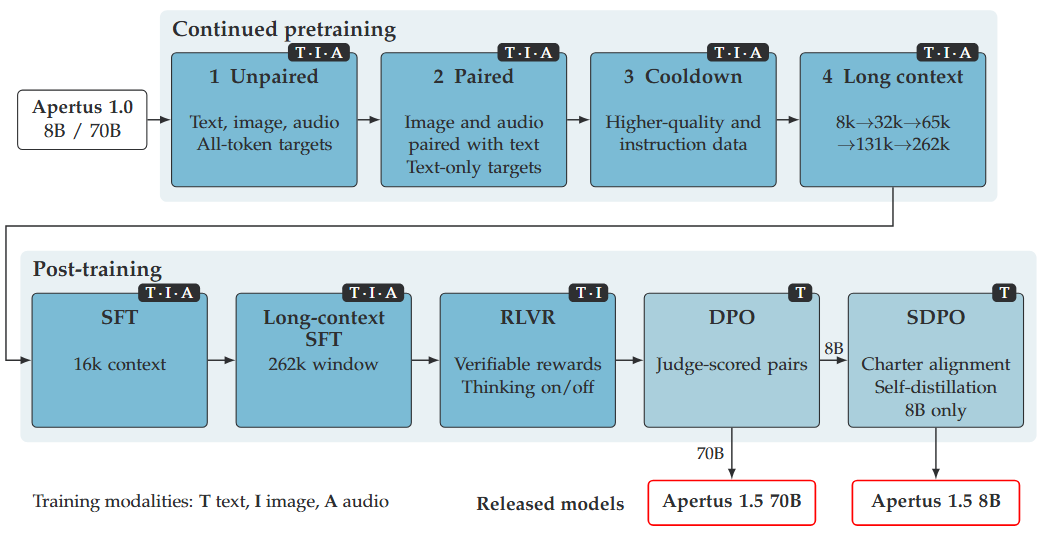
The 8B and 70B weights continue from Apertus 1.0 with 4 trillion and 2 trillion additional tokens, reaching 19T and 17T.
A 512 by 512 image is converted into 1,024 tokens, while audio is counted at 40 tokens per second.
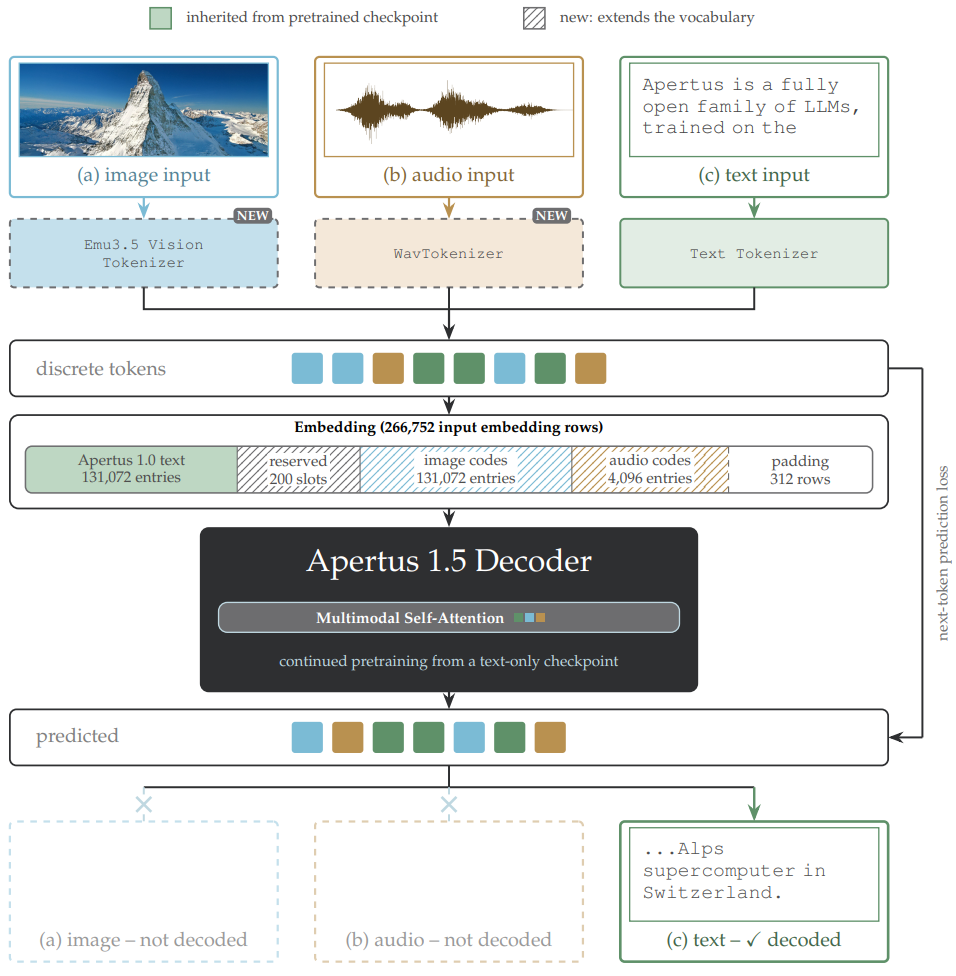
The context window grows to 262,144 tokens, four times the previous size.
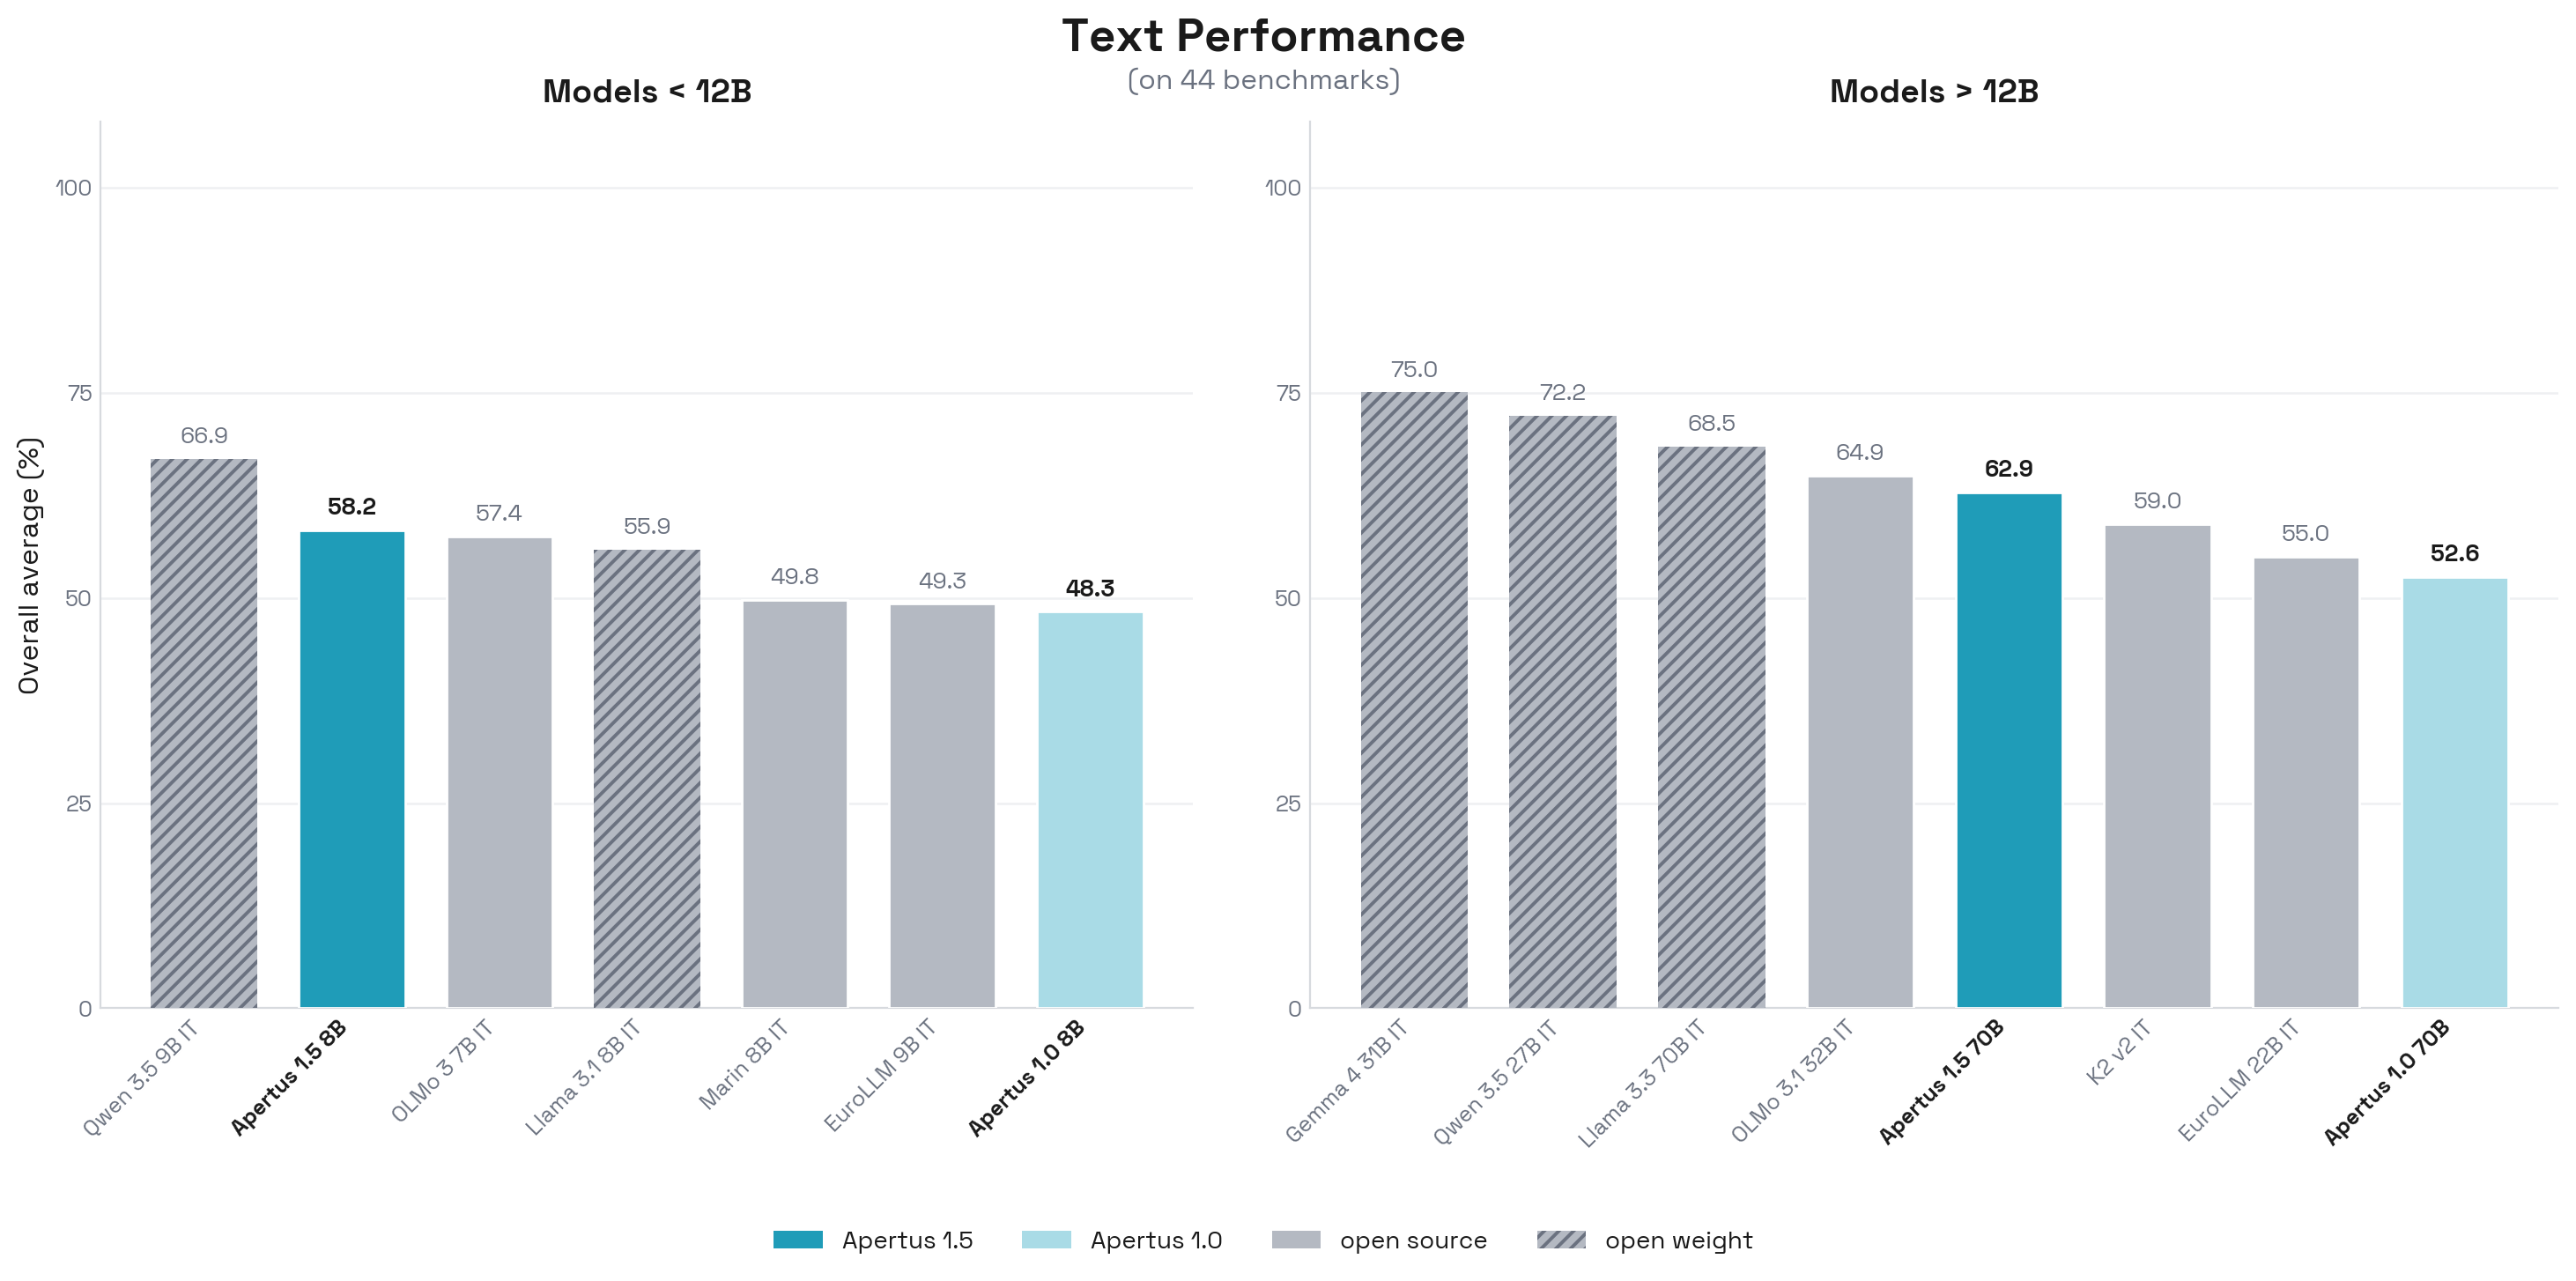
An optional thinking mode reasons before answering, and the release notes report better instruction-following and tool use.
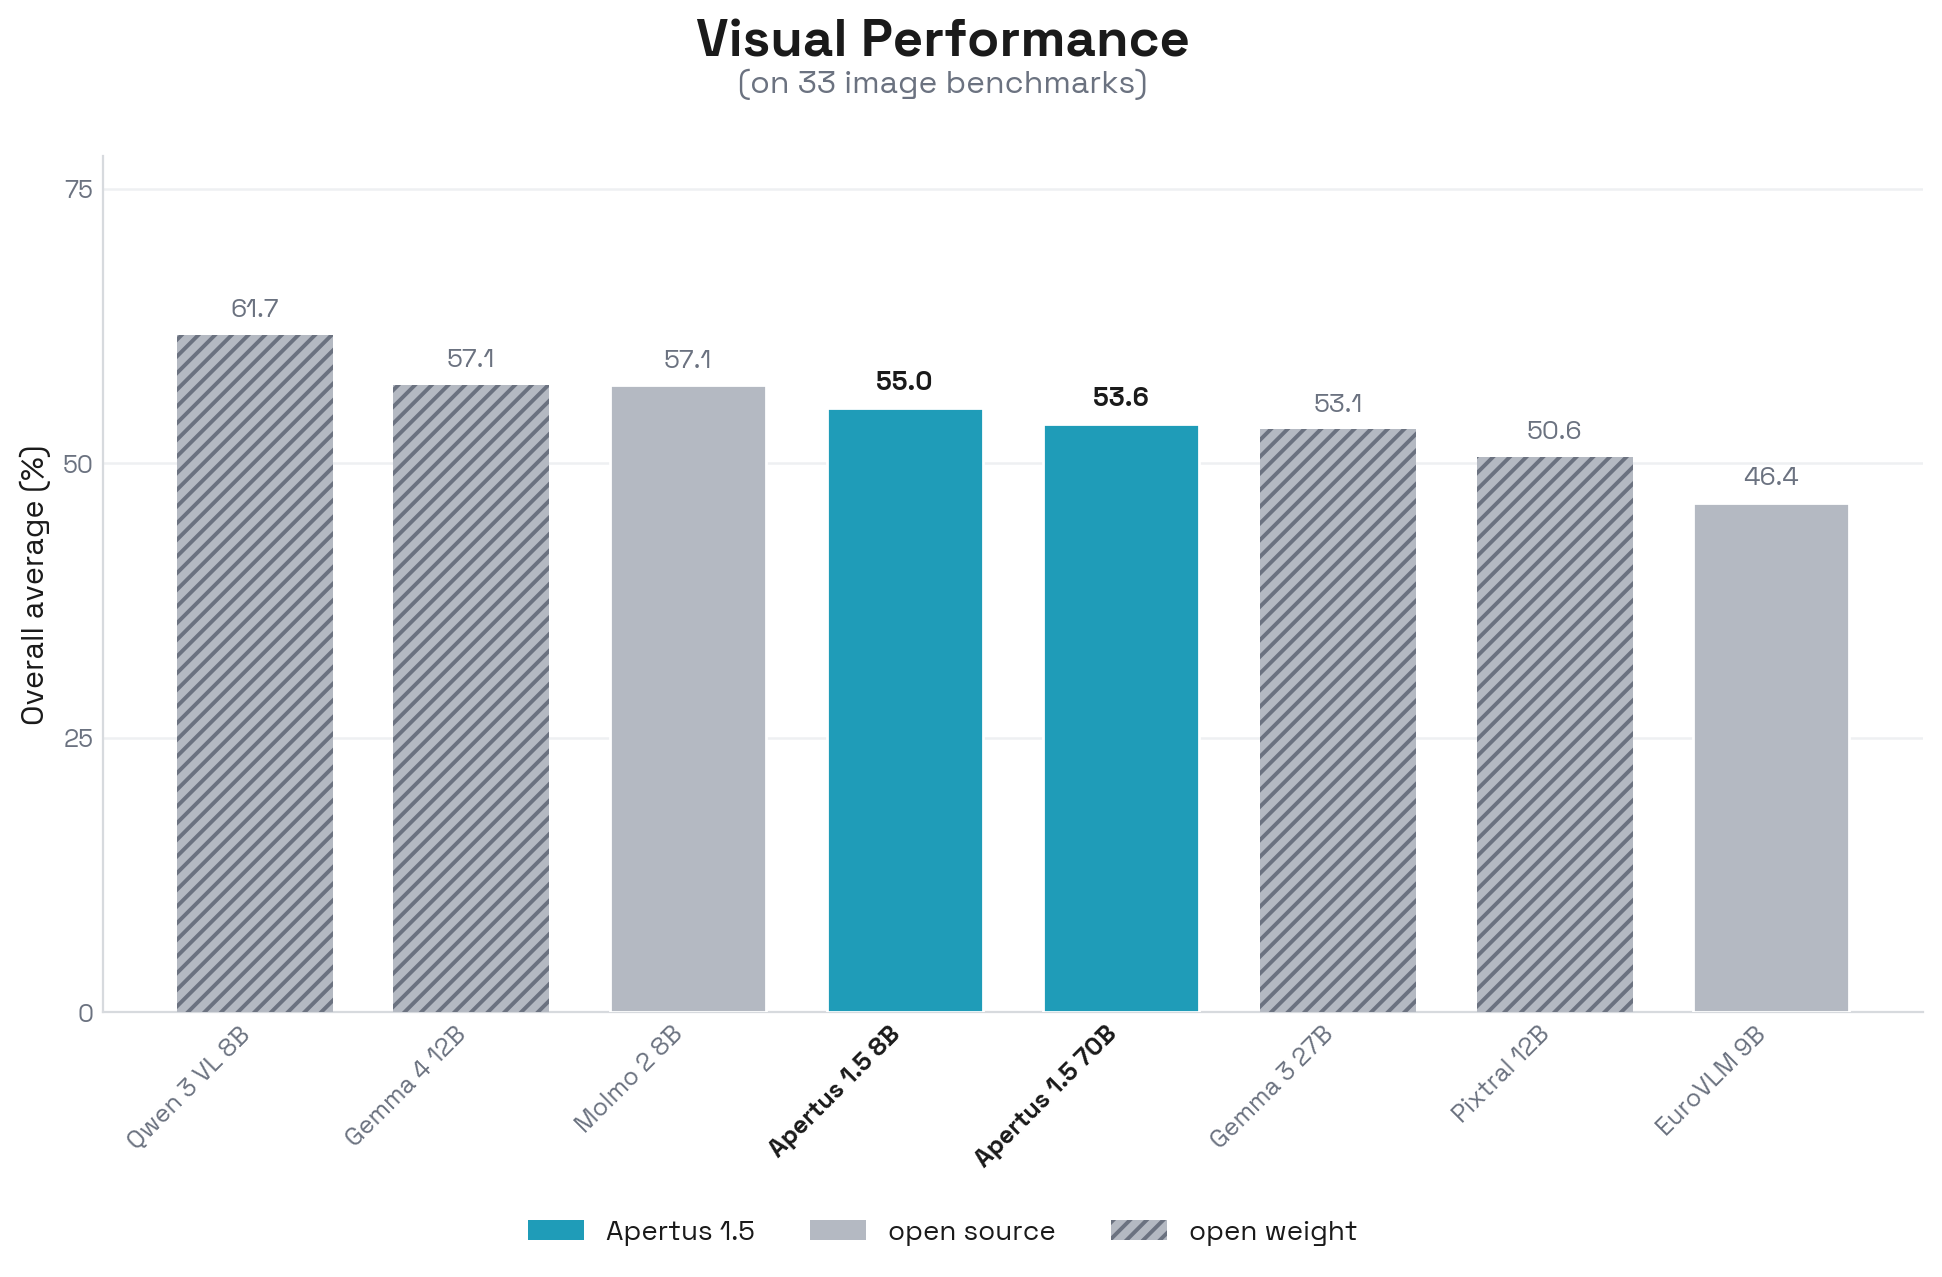
The token counts matter as a budget for deployers, not as proof of inference cost, latency, or hardware fit.
Numeric benchmark scores, training compute, GPU hours, energy use, cost, watt measurements, exact DPO preference-pair counts, and hardware deployment measurements are absent.
The token budget is the practical constraint, not a capability claim.
After arxiv.org. We did not report this. The pictures, if any, are theirs.