LiquidAI lowers active parameters to 2B for on-device agents
The model keeps 24B total parameters while activating only 2B per token.
| LFM2.5-24B-A2B | Qwen3.6-35B-A3B | Gemma-4-26B-A4B-it | |
|---|---|---|---|
| parameters | 24B | 35B | 26B |
| active parameters | 2B | 3B | 4B |
| context | 131K | ||
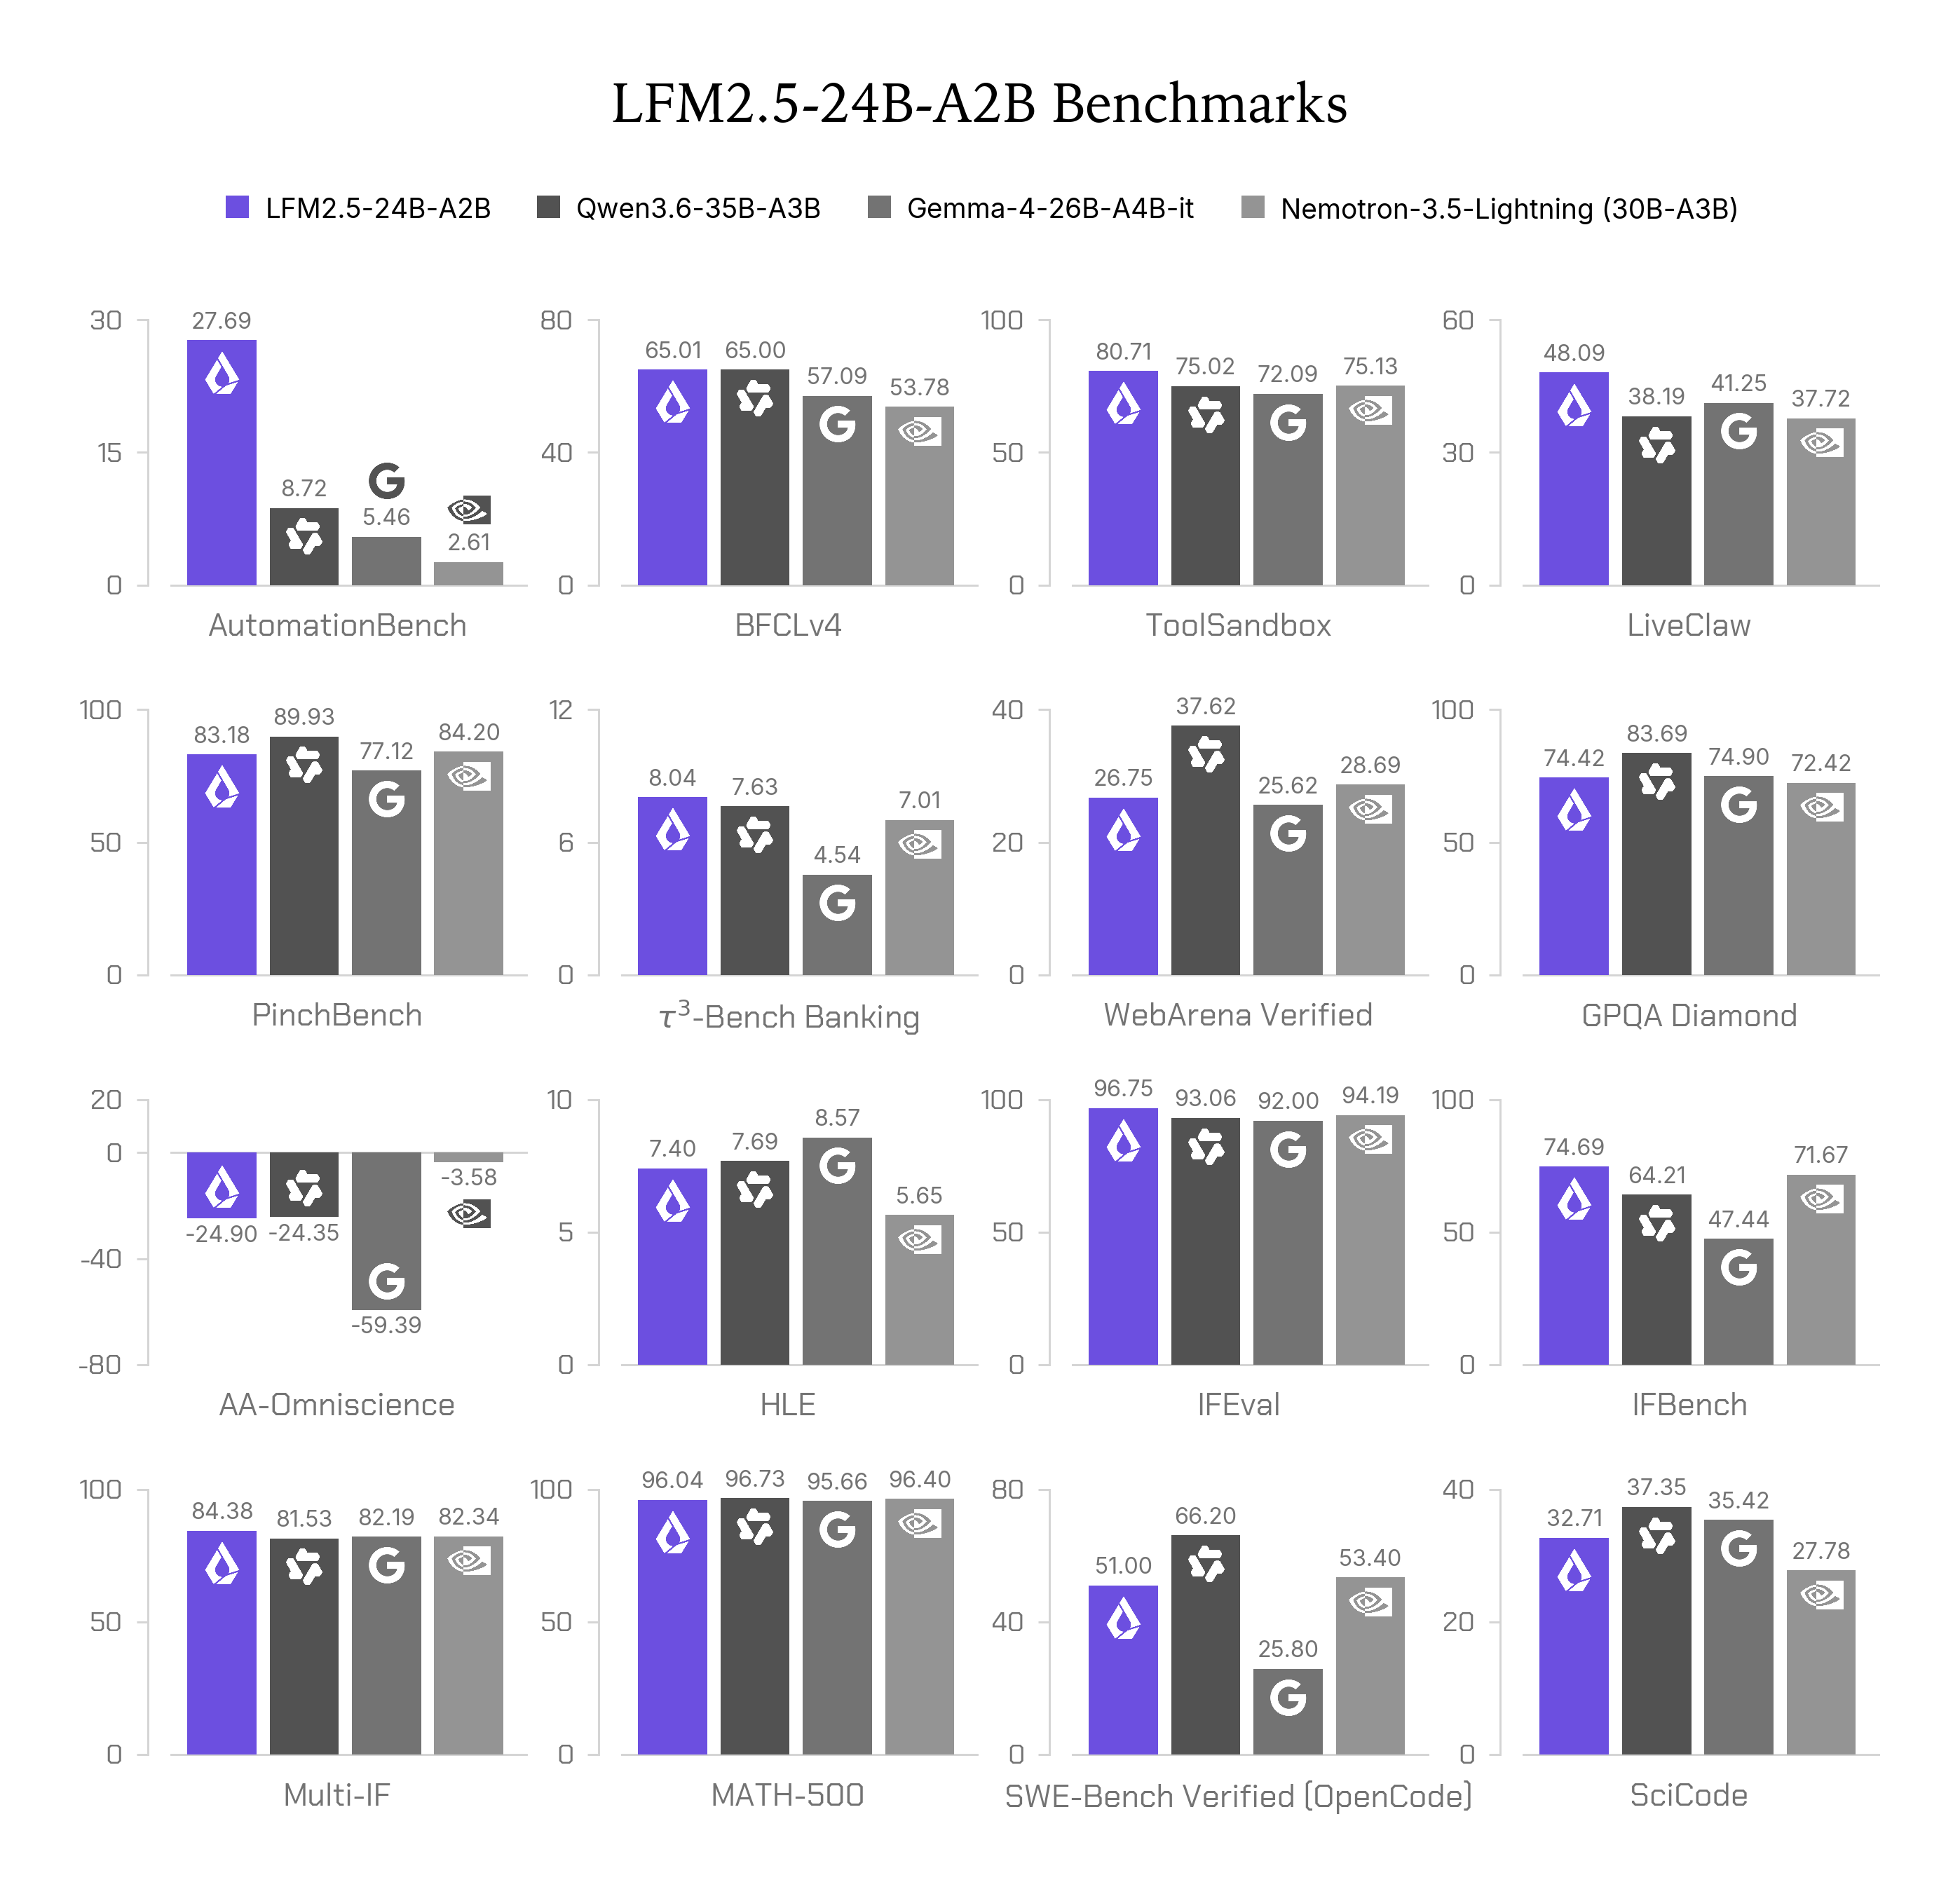
| LiveClaw | 48.09 | 38.19 | 41.25 |
| BFCLv4 | 65.01 | 65.00 | 57.09 |
| MATH-500 | 96.04 | 96.73 | 95.66 |
| SWE-Bench Verified (OpenCode) | 51.00 | 66.20 | 25.80 |
| GPQA Diamond | 74.42 | 83.69 | 74.90 |
The model keeps 24B total parameters while activating only 2B per token.
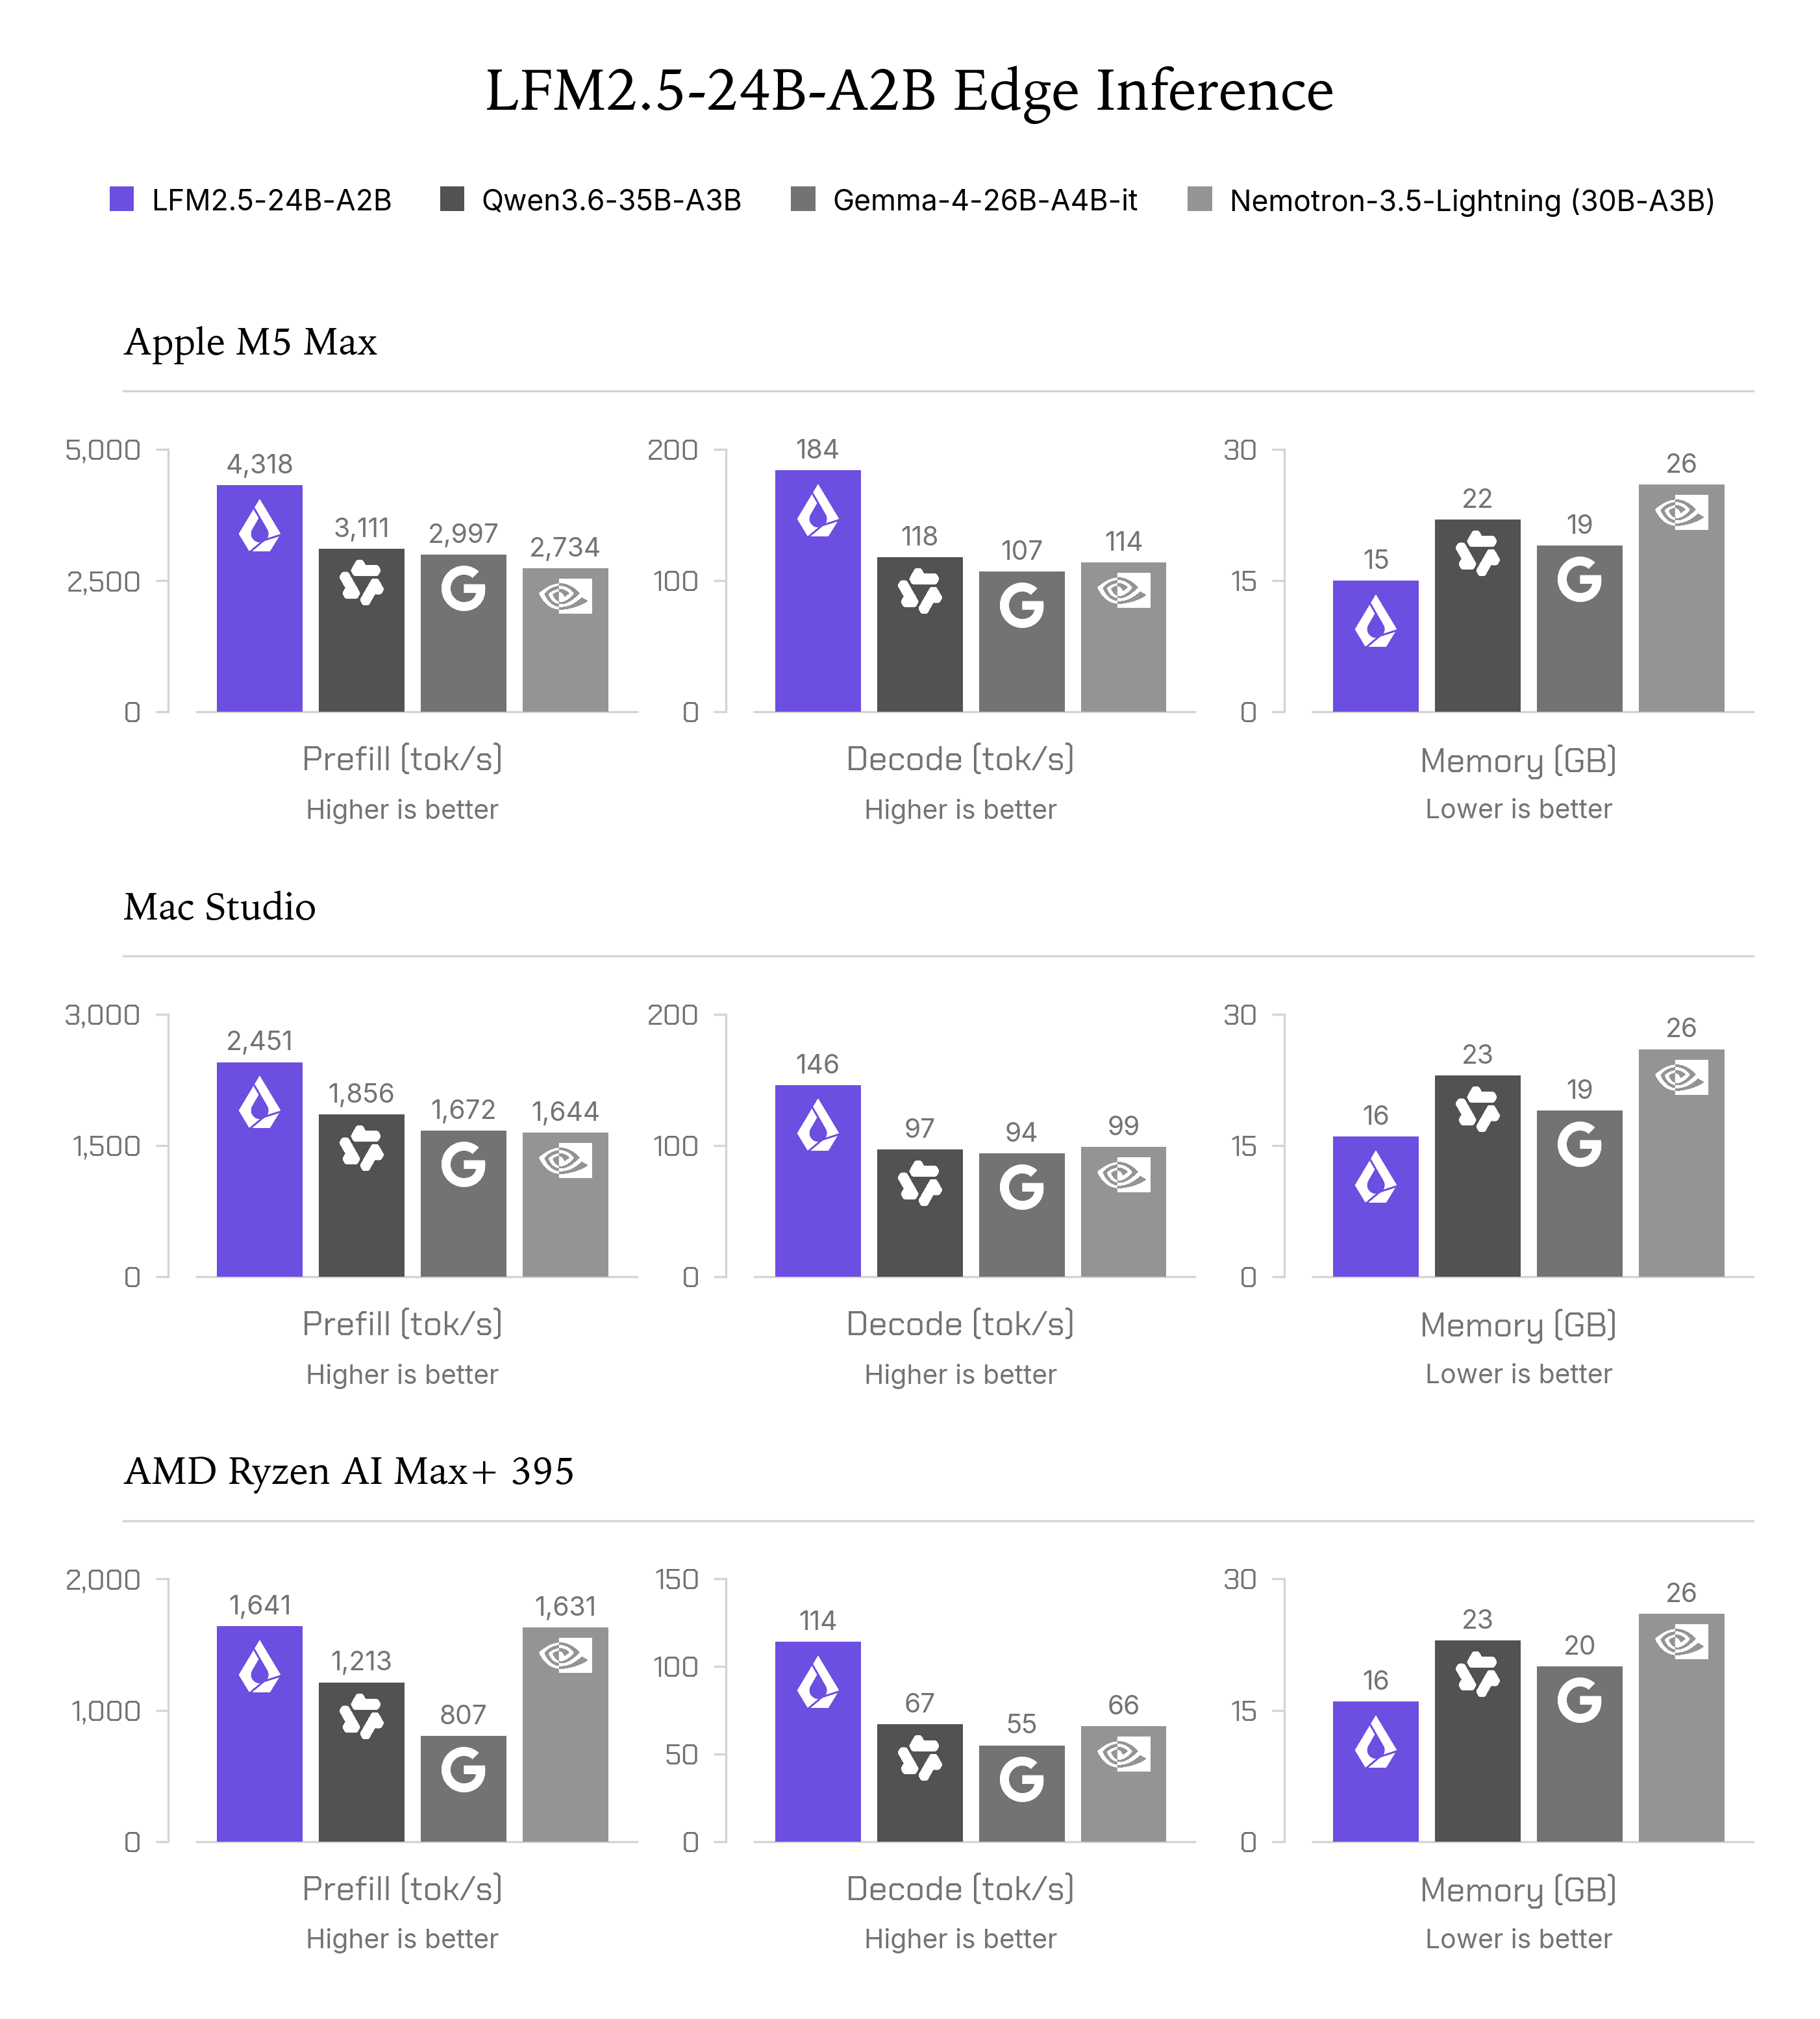
The page reports 184 tokens/s on an Apple M5 Max and 114 tokens/s on a Ryzen AI Max+ 395.
It does not give a Mac Studio figure.
The architecture has 40 layers, 64 experts, top-4 routing, and 131K context.
Pre-training reaches about 33T tokens, and the tokenizer expands to 128K.
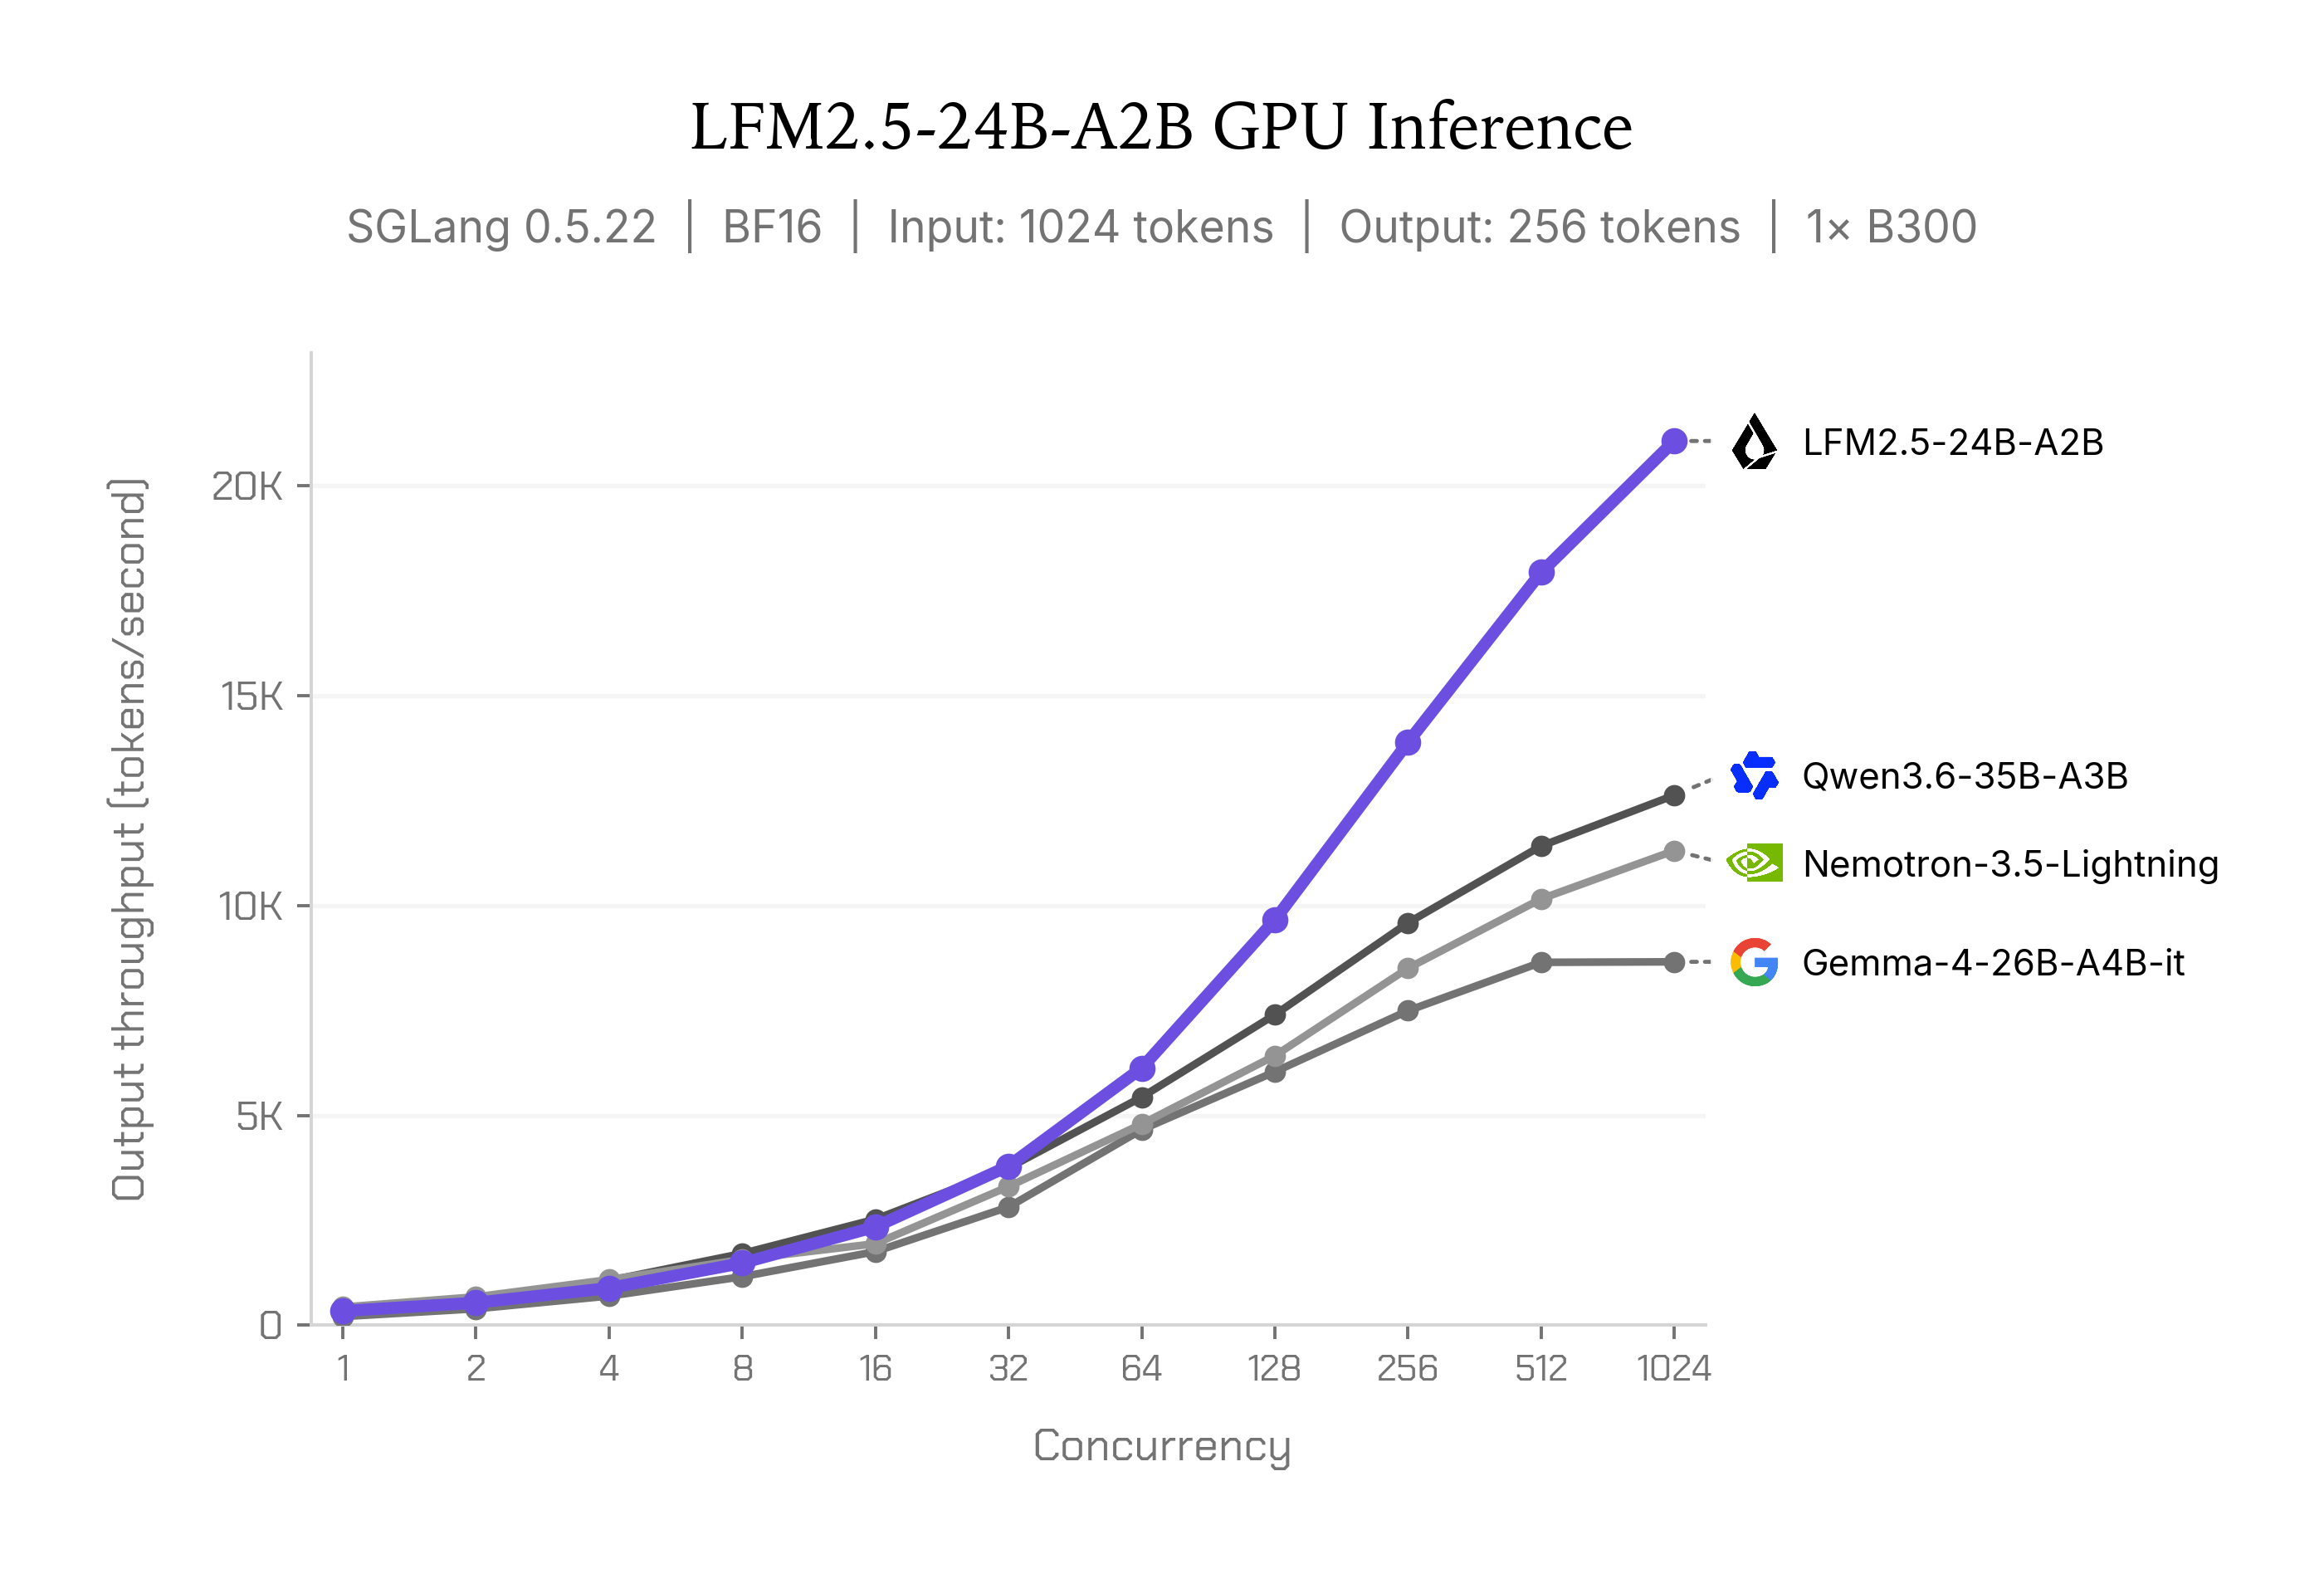
At high concurrency, the page gives over 21K output tokens/s on a single B300.
SWE-Bench Verified sits at 51.00 versus 66.20 for Qwen3.6-35B-A3B, and GPQA Diamond sits at 74.42 versus 83.69.
Power draw, memory footprint, and sustained agent-loop throughput on the named hardware remain unmeasured.
Treat it as a tool-use and instruction-following agent, not a general replacement for a bigger model.
After huggingface.co. We did not report this. The pictures, if any, are theirs.