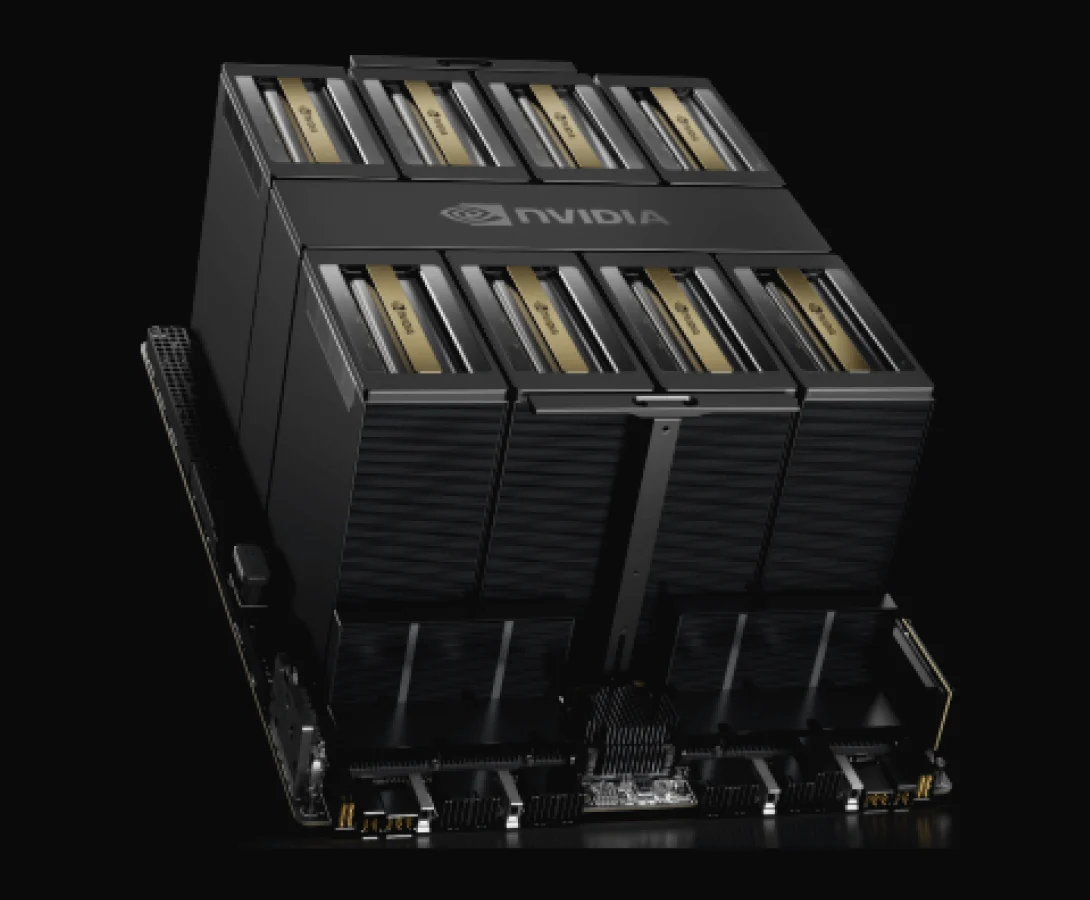
DGX B300: rack power and node memory
Rack power is the first constraint on the DGX B300: about 14 kW for an eight-GPU 10U system.
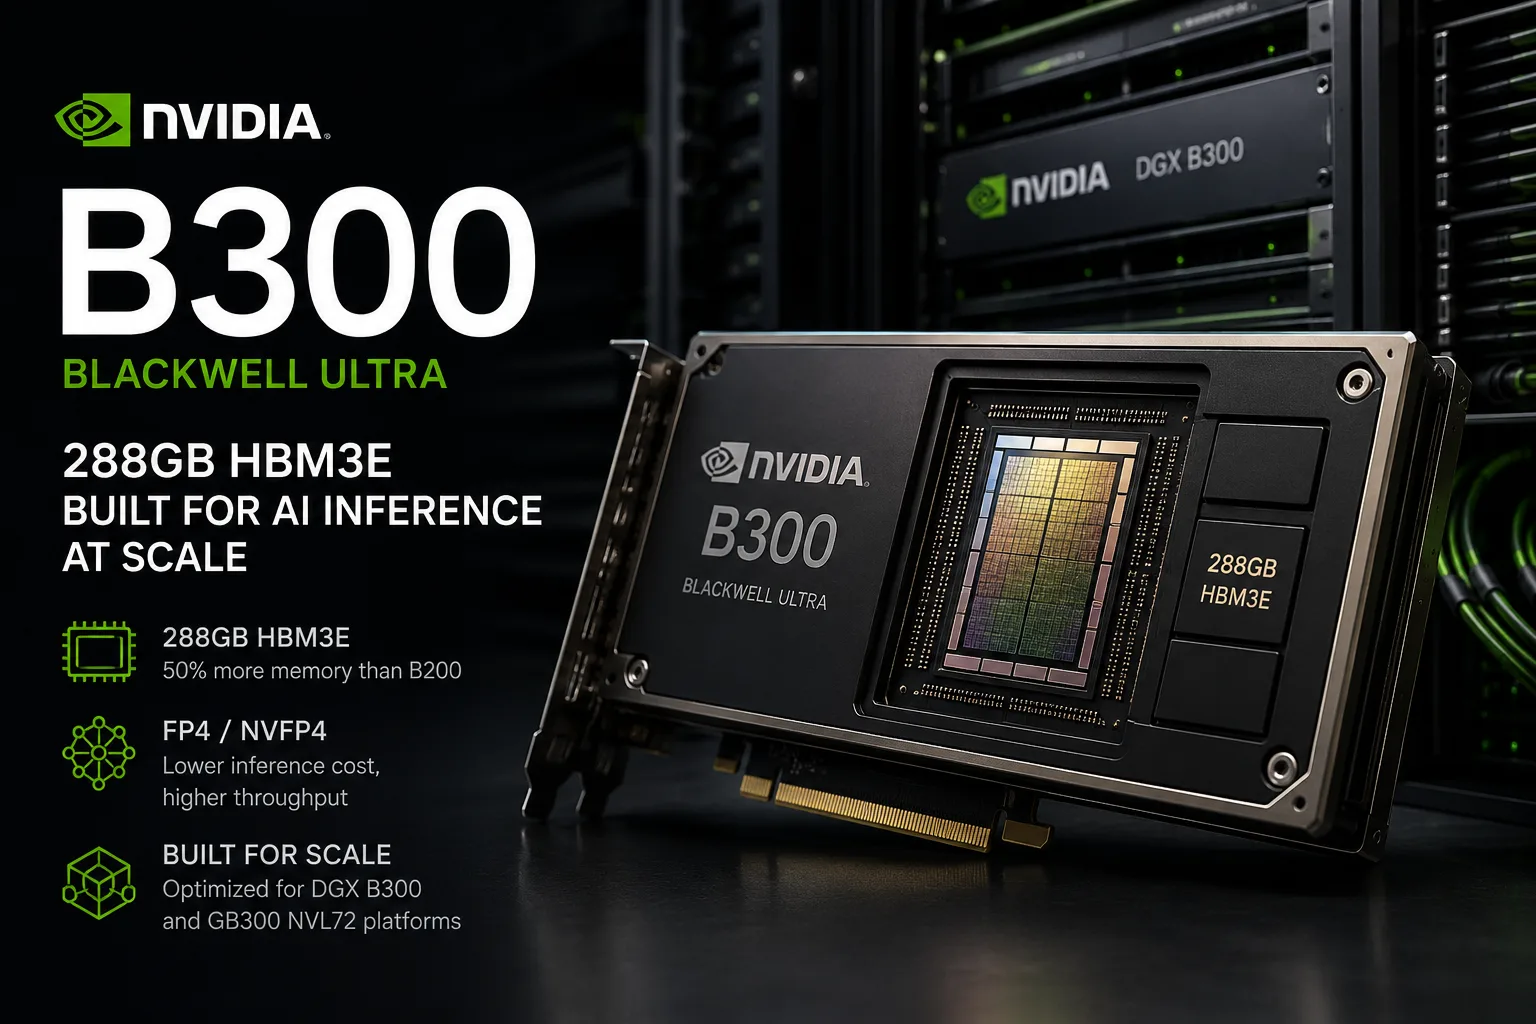
| NVIDIA DGX B300 | |
|---|---|
| GPUs | 8x NVIDIA Blackwell Ultra SXM |
| Total GPU memory | 2.1 TB |
| FP4 Tensor Core | 144 PFLOPS sparse | 108 PFLOPS dense |
| FP8 Tensor Core | 72 PFLOPS sparse; dense is 1/2 sparse |
| NVLink bandwidth | 14.4 TB/s aggregate bandwidth |
| Networking | 8x OSFP ports serving 8x single-port ConnectX-8 VPI up to 800 Gb/s; 2x dual-port |
| Storage | 2x 1.9 TB NVMe M.2 OS; 8x 3.84 TB NVMe E1.S internal storage |
| Power consumption | ~14 kW |
Across eight Blackwell Ultra SXM GPUs, the page gives 2.1 TB of total GPU memory. The number does not settle per-GPU capacity, TDP, or cloud price.
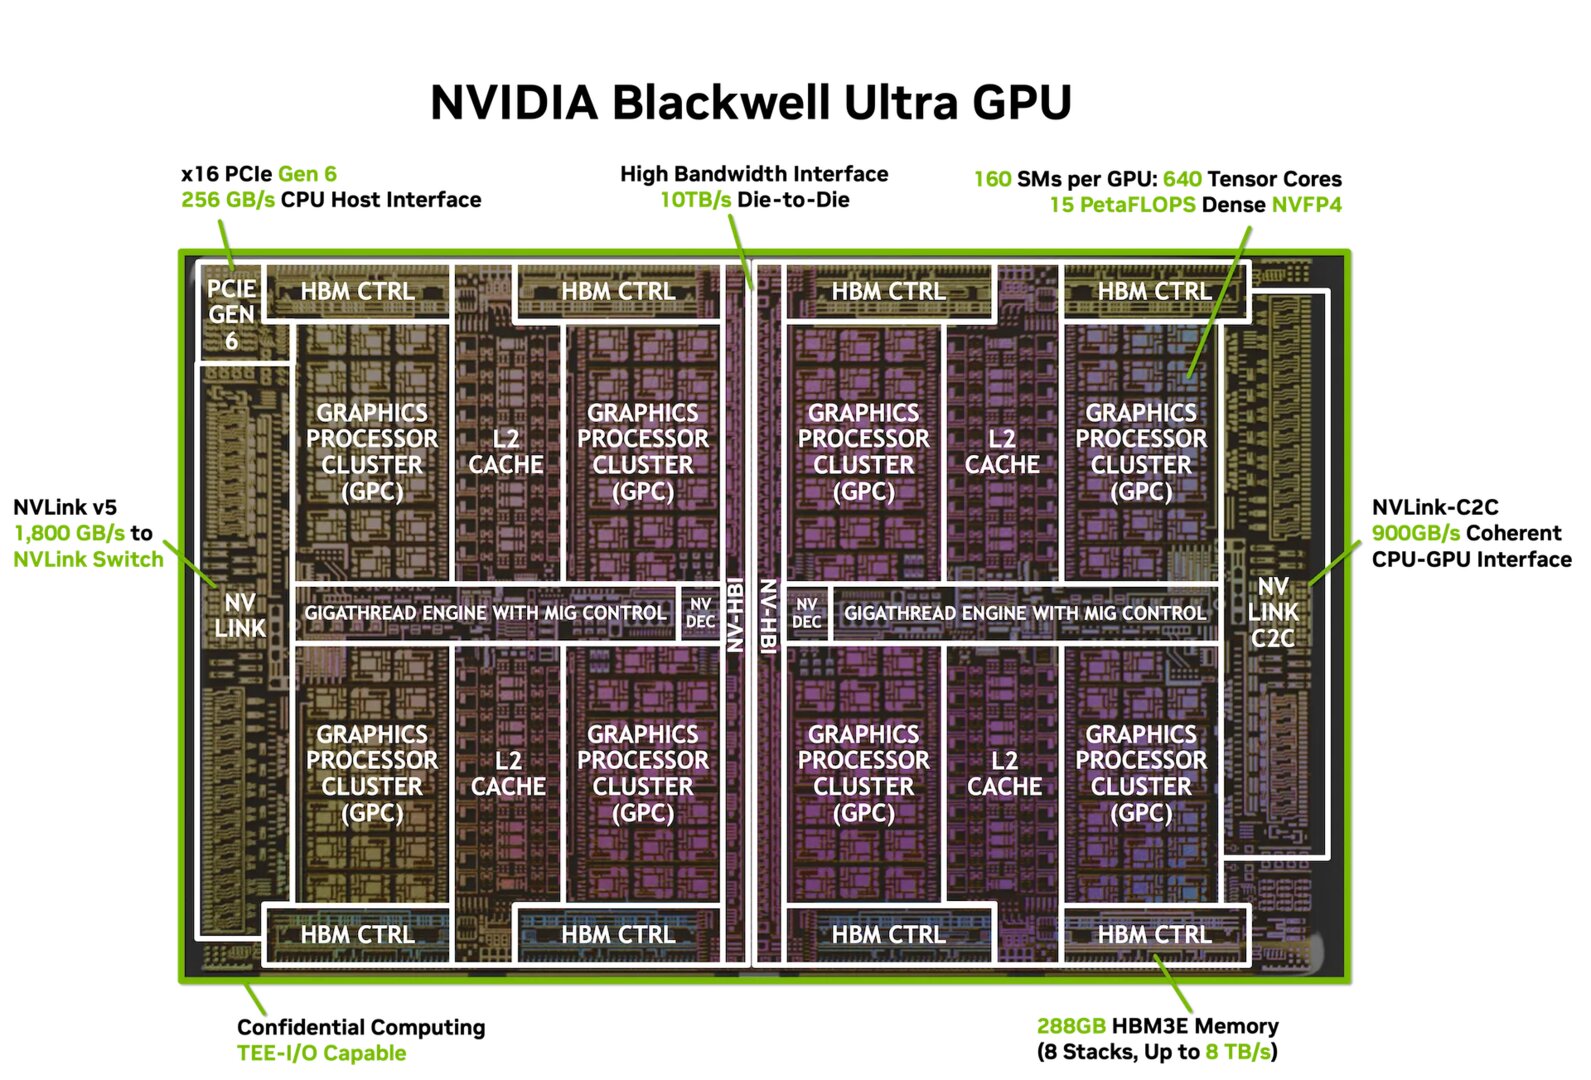
The compute figures are node-level too: 144 PFLOPS sparse FP4, 108 PFLOPS dense FP4, and 72 PFLOPS sparse FP8. NVLink aggregate bandwidth is 14.4 TB/s, which points to a node built to move data internally.
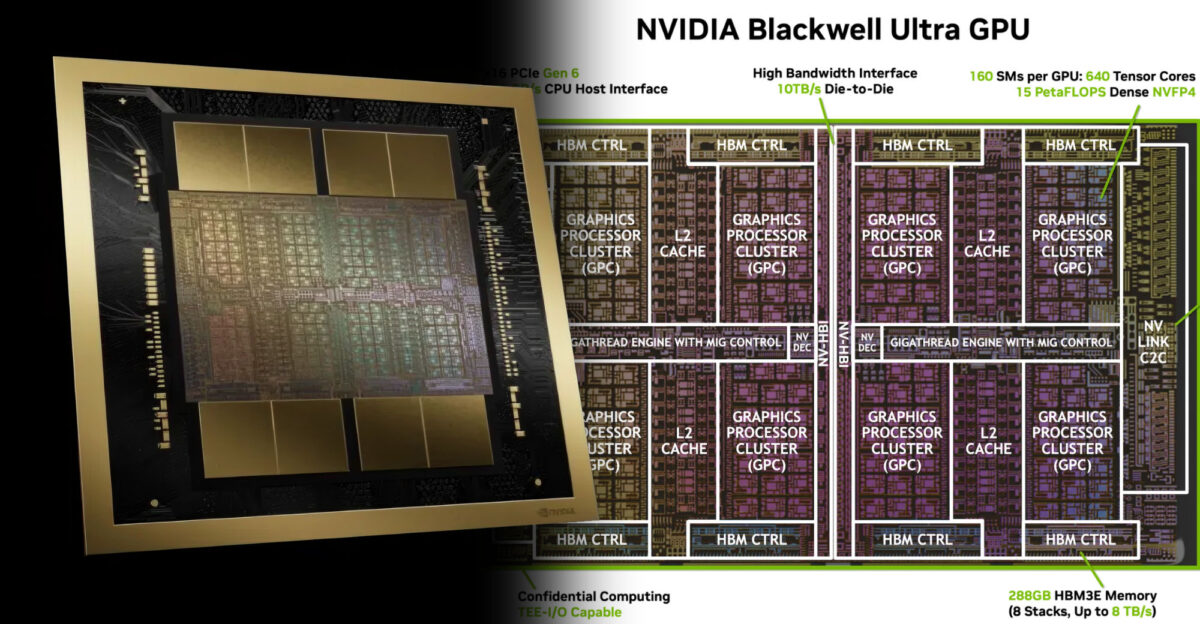
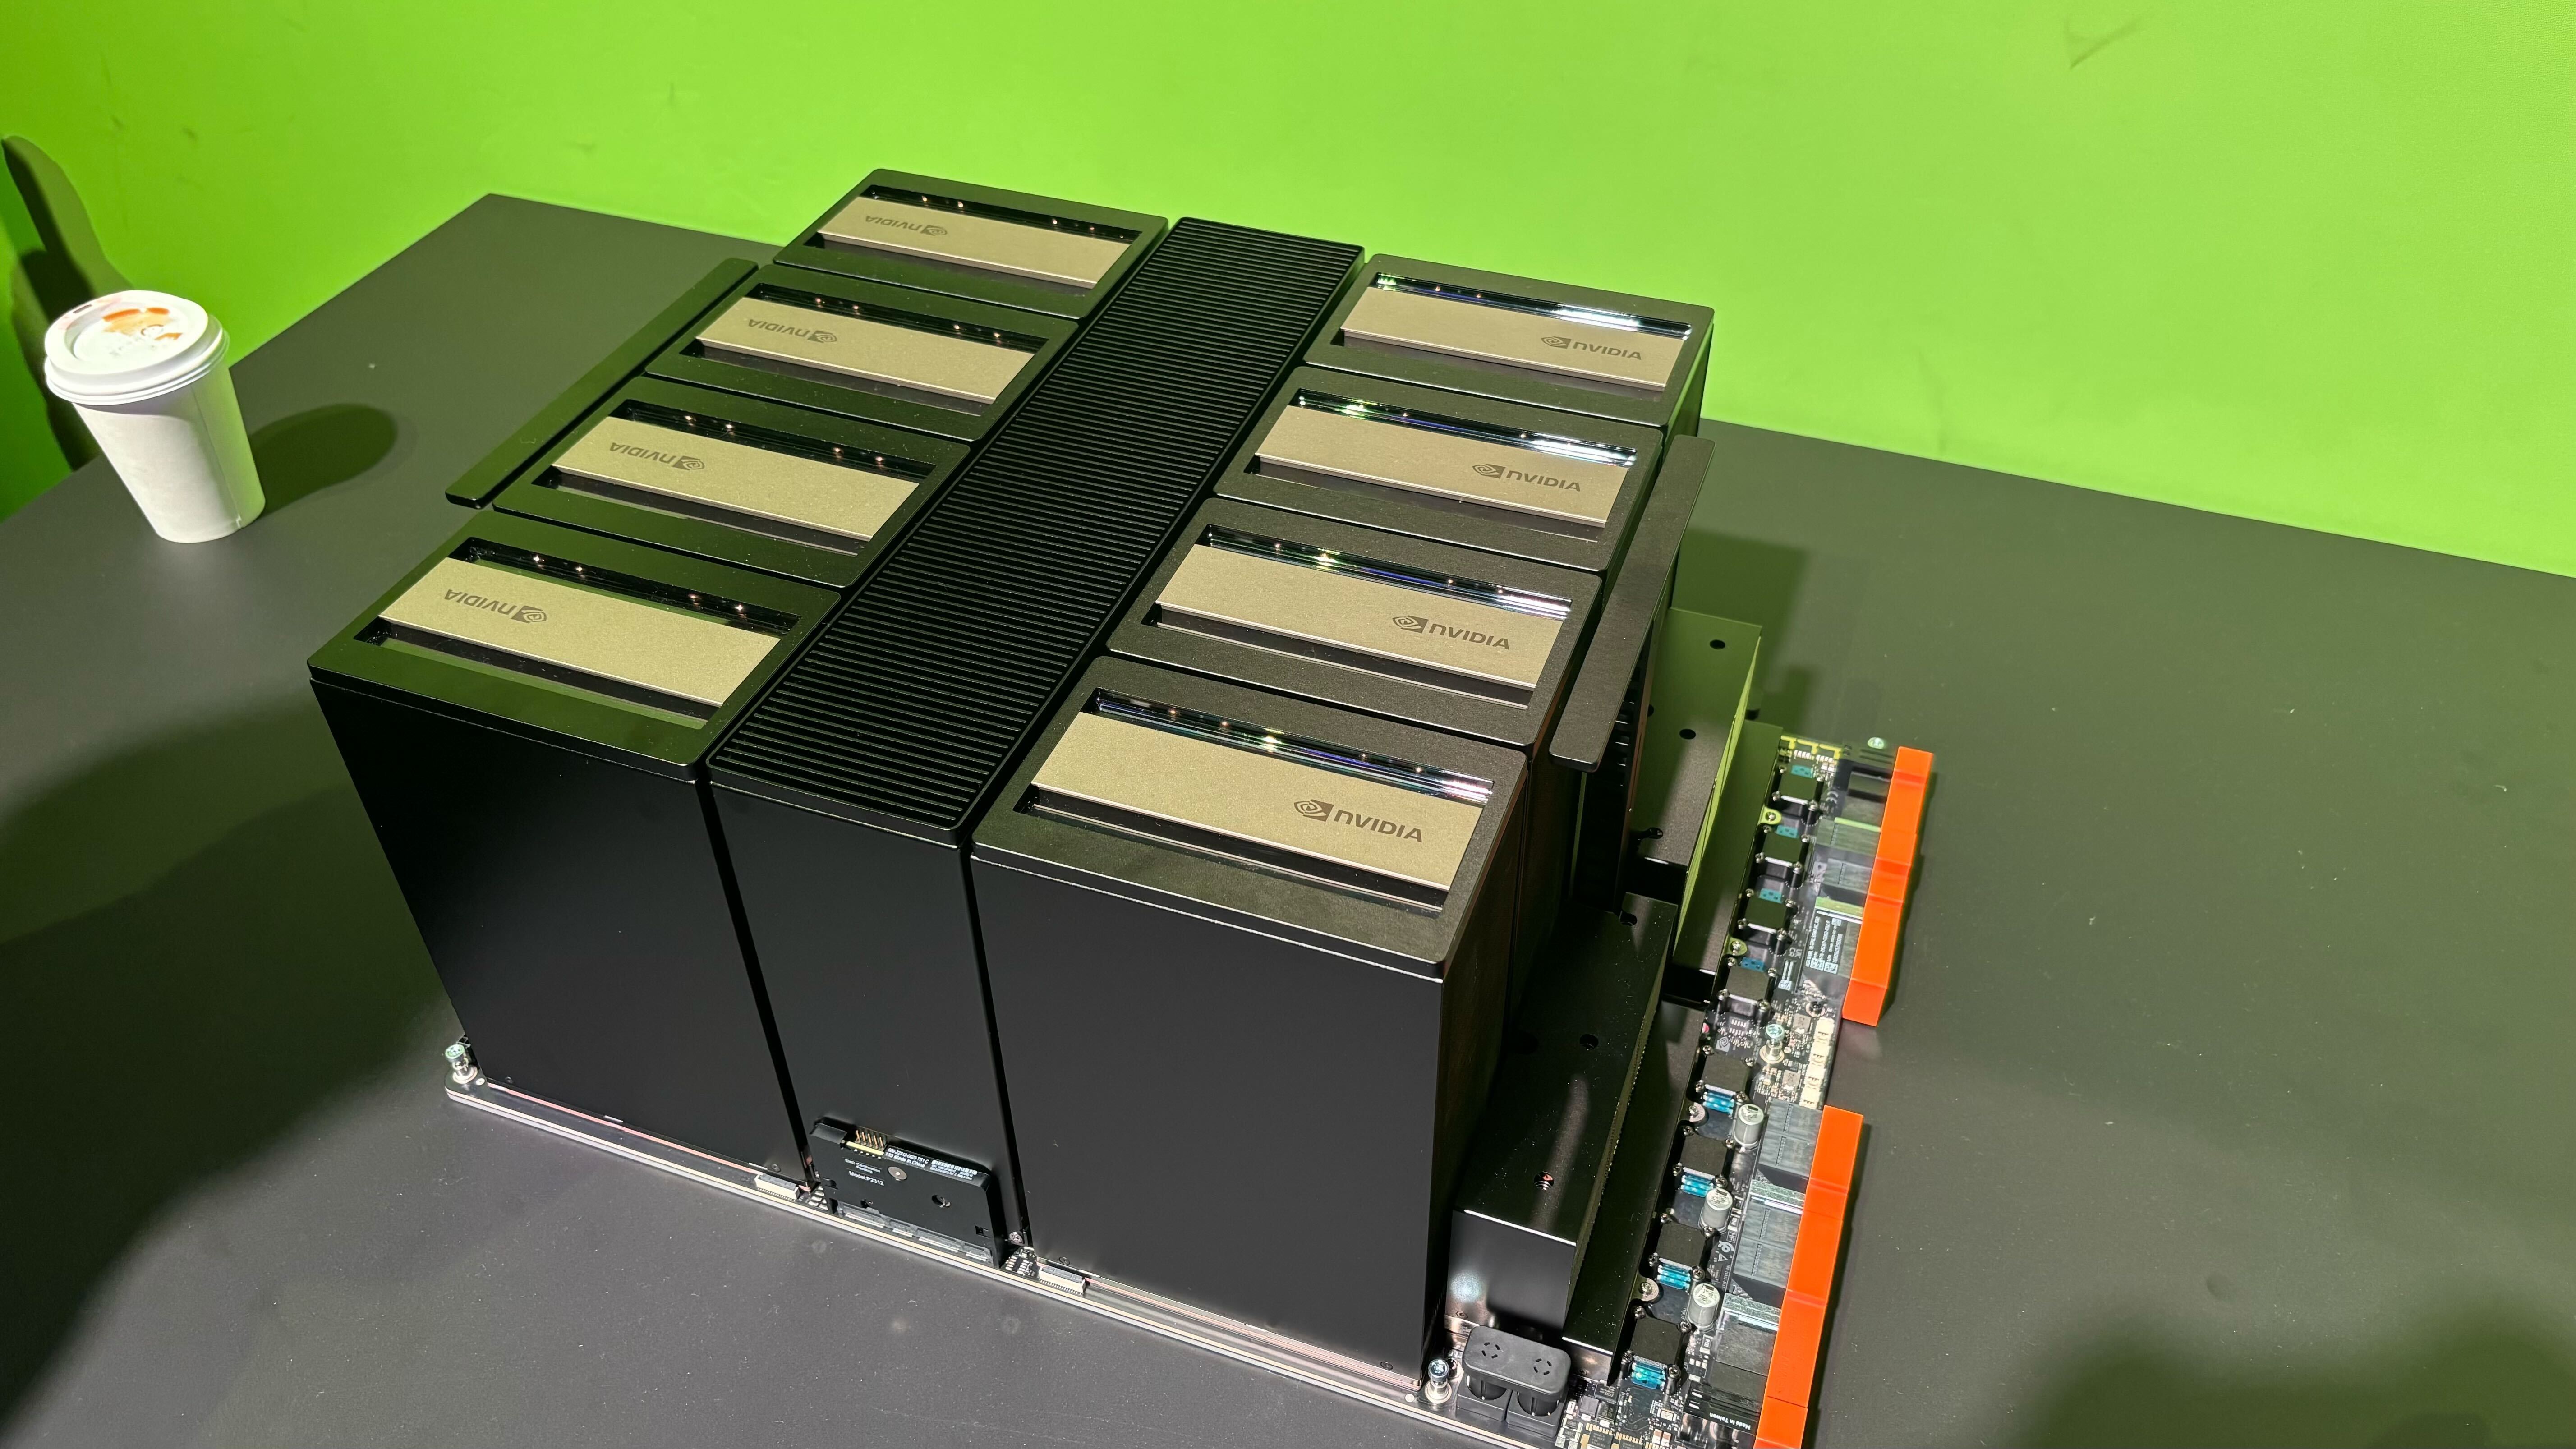
What is missing is the per-GPU breakdown: memory, dense FP4 or FP8, TDP, per-link NVLink bandwidth, ship date, and cloud pricing. The useful comparison is whole-node power, memory, and network, not a single chip.
Lead with rack power, keep the spec node-level, and flag the missing per-GPU breakdown.
After nvidia.com. We did not report this. The pictures, if any, are theirs.