What a million tokens costs on a rented H100 or B200
Nebius posts 4.50 dollars an hour for an H100 and 8.50 for a B200 from 8 October 2026. Lambda posts 3.99 and 6.69 on its instance page. Neither page prices a million tokens.
| On-demand per GPU-hour | Where it is posted | Million tokens | |
|---|---|---|---|
| H100, Nebius | $4.50 | Nebius compute pricing | |
| H200, Nebius | $5.40 | Nebius compute pricing | |
| B200, Nebius | $8.50 | Nebius compute pricing | |
| B300, Nebius | $9.50 | Nebius compute pricing | |
| H100 SXM, Lambda instance | $3.99 | lambda.ai/instances | |
| B200 SXM6, Lambda instance | $6.69 | lambda.ai/instances | |
| B200, Lambda 16-GPU cluster | $9.86 | Lambda cluster pricing | |
| Rubin or GB200 NVL72 | not listed on the Nebius price article |
People looking up the cost of a million tokens usually want one dollar figure. A rented GPU is sold by the hour. Turning that hour into tokens needs a second public number: how many tokens the same instance produces in one second, on a named model, on that provider's own stack. When either number is missing, a million-token cost is not drawn. This brief does not fill it from a benchmark of a different machine.
Nebius prints the rates in its document Compute pricing in Nebius AI Cloud. The page says on-demand prices for B300, B200, H200, and H100 changed on 1 October 2026, and that from 8 October 2026 the preemptible price on several of those platforms is a dynamic spot rate, displayed as a floor. The dollar figures on that page are before tax. The billing unit is one second and the pricing unit is one hour, so thirty minutes is half the hourly rate. A stopped virtual machine is not charged for the GPU. The bars are the on-demand rates read on 10 October 2026. The 8 October note on that page is a preemptible floor, and it is not drawn. The line above the bars is what an H100 hour has cost across the months a posted rate could be read.
NVIDIA B300 NVLink is 9.50 dollars for one GPU-hour, with a preemptible floor of 0.99 dollars. Before 1 October the same block lists 7.85 dollars on demand. NVIDIA B200 NVLink is 8.50 dollars for one GPU-hour. The page ties one platform id to us-central1 and another to me-west1, at the same on-demand rate, with a preemptible floor of 0.99 dollars. Before 1 October that block lists 7.15 dollars. NVIDIA H200 NVLink is 5.40 dollars, in eu-north1, eu-north2, eu-west1, and us-central1, with a preemptible floor of 0.79 dollars. Before 1 October it lists 4.50 dollars. NVIDIA H100 NVLink is 4.50 dollars, and the page says that platform is only in eu-north1. The preemptible floor is 0.79 dollars. Before 1 October it lists 3.85 dollars.
NVIDIA RTX PRO 6000 stays at 1.80 dollars a GPU-hour across the October change, with a preemptible floor of 0.79 dollars from 8 October. NVIDIA L40S is listed as 1.35 dollars for the GPU plus separate CPU and memory lines. Because the page does not roll those into one GPU-hour, this brief does not invent an all-in rate. The page does not list a public hourly price for a Rubin rack or a GB200 NVL72, so those rows stay blank, and it does not print tokens per second beside any GPU.
Lambda's instance page, opened the same day, lists the chip, the onboard memory, the vCPUs, and a price per GPU-hour, plus applicable tax. The B200 SXM6 row with 180 GB and 208 vCPUs is 6.69 dollars. The H100 SXM row with 80 GB and 208 vCPUs is 3.99 dollars. The A100 SXM row with 80 GB and 240 vCPUs is 2.79 dollars. The page groups further rows under smaller instance sizes. B200 SXM6 appears again at 6.79, 6.89, and 6.99 dollars, next to 104, 52, and 26 vCPUs. H100 SXM on those rows is 4.09, 4.19, and 4.29 dollars. An H100 PCIe row with 80 GB and 26 vCPUs is 3.29 dollars. A GH200 row with 96 GB is 2.29 dollars. Under the B200 section the page says the instances start at 6.69 dollars, and it says the part offers up to three times the training and fifteen times the inference of H100. It does not say how many tokens that hour produces.
Lambda's cluster page is a different listing, read the same day. For NVIDIA HGX B200 systems committed from two weeks to one year, the page shows 9.86 dollars a GPU-hour at 16 GPUs, 9.36 dollars at 64 GPUs, and 8.87 dollars at 256 GPUs and above. The cell for a commitment of one year or longer is a dash. H100 systems on that page show 6.16 dollars at 16 GPUs, 5.85 dollars at 64, and 5.54 dollars at 256. The longer commitment is a dash there as well. Those cluster rates sit above the instance rates. Both are Lambda's own pages. This brief keeps them on separate rows instead of publishing the cheaper one as the price of a B200.
If an hour price and a tokens-per-second figure were both posted for the same instance, the cost of a million tokens would be the hour price divided by the tokens per second, divided again by 3,600, then multiplied by 1,000,000. That is arithmetic, and a later revision should say so in the sentence. It assumes the GPU emits tokens at that rate for the entire hour, which a real job does not do when it waits on the prompt, the batch, or an idle gap. Even a clean pair of numbers would be a ceiling-style conversion, not a bill. Nebius and Lambda do not post the tokens-per-second half, so neither chart puts a price on a million tokens.
A spot floor is not the on-demand rate. Nebius says the preemptible price can change as often as every fifteen minutes, that it stays at least one cent under the on-demand rate, and that the number on the documentation page is a minimum. The phrase is "from 0.79" or "from 0.99", not the charge a running job will see. The on-demand column is the figure a reader can compare next month without logging into a console.
An H100 hour has not moved in one smooth line, and the two rates on the chart are different offers. The SXM5 pay-as-you-go hour was $4.85 from November 2023 through July 2024, and $3.50 on 15 September 2024. The later NVLink hour was $2.95 from October 2025 through May 2026, $3.85 from 1 June 2026, and $4.50 from 1 October 2026. The months between September 2024 and November 2025 are left empty. The posted offer changed, and those in-between months were not in the copies read for this brief. A third quote, $2.118 for the GPU alone with the processor and memory billed beside it, is not drawn.
The useful update is the dated move on the Nebius page itself. From 1 October 2026 the on-demand H100 line goes from 3.85 to 4.50 dollars, the H200 line from 4.50 to 5.40, the B200 line from 7.15 to 8.50, and the B300 line from 7.85 to 9.50. Those four pairs are on one document, with the old rate left in place under a "before" heading. Lambda's instance rows do not carry a date. The 6.69 and 3.99 dollar figures are what that URL showed on 10 October 2026, and a revision should open the URL again rather than treat them as a contract.
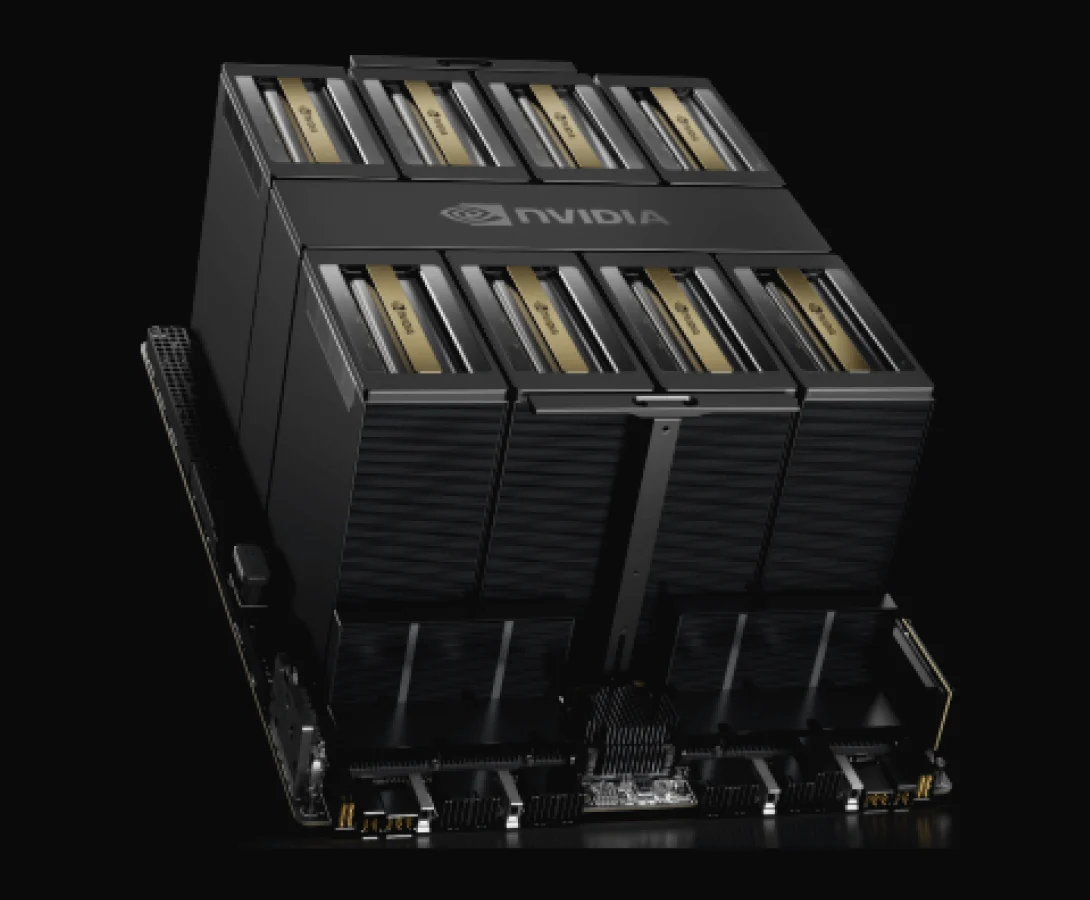
The photograph is the HGX baseboard Lambda publishes beside its B200 instances. It is a picture of the machine on the 6.69 dollar row. It is not a chart of tokens, and it does not make the empty million-token cell into a measurement. Until a provider prints both the hour and the throughput for the same box, the cost of a million tokens on these GPUs is not a number this desk will invent.
After Nebius. We did not report this. The pictures, if any, are theirs. Also filed by Lambda, Lambda clusters.