Concurrent HBM and host memory access lifts LLM inference throughput by 31 percent
BOOST, a runtime system from Georgia Tech, Nvidia, and Stanford, improves LLM inference throughput by 31 percent on Grace Hopper by concurrently accessing HBM and host DRAM.
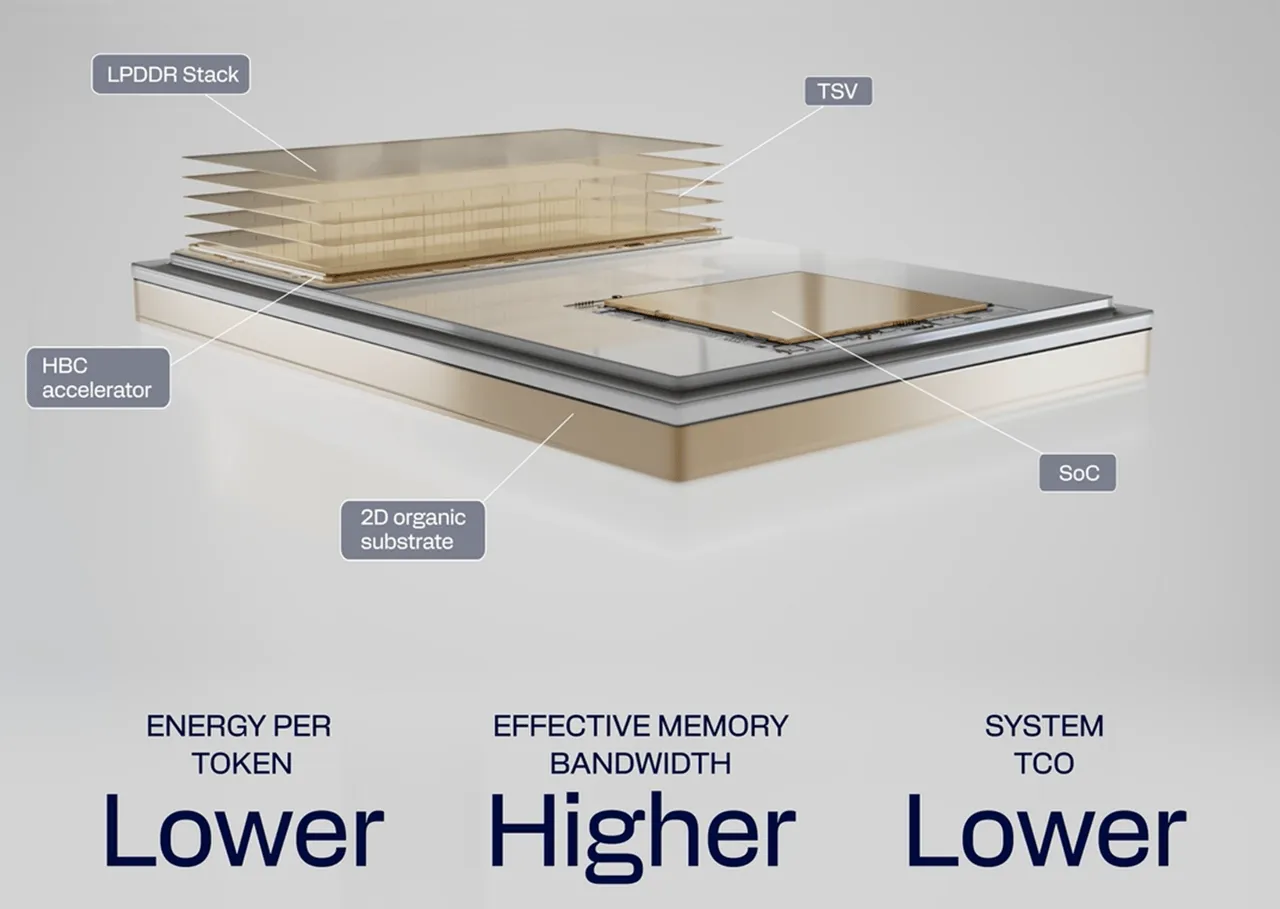
That is the average throughput gain BOOST delivers in high-throughput LLM serving on a Grace Hopper system, and it comes without a single kernel modification. The system, published by researchers at Georgia Tech, Nvidia Research, and Stanford, is the first runtime to provide concurrent and proportional access to both GPU memory tiers simultaneously. It extracts the combined bandwidth of HBM and host DRAM for inference workloads that previously could only use one tier at a time.
For static model weights, BOOST applies modulo-based page placement across the two memory tiers, which eliminates access-ratio variance between HBM and host DRAM. For the dynamically provisioned attention key-value pairs that grow and shrink during inference, the system makes the free KV page pool wave-aware, so allocation decisions track the actual access pattern of the current kernel wave rather than a fixed allocation scheme. The result is that both tiers are read concurrently at a proportional rate matched to the workload's demand, rather than one tier sitting idle while the other saturates.
At iso-batch size, HBM-only serving is the baseline. BOOST improves Time-per-Output-Token by 4.3 percent over that baseline. The alternative approach, prefetching data from host memory into HBM, actually degrades TPOT by 6 percent. In high-throughput serving mode, the gap widens: BOOST delivers a 31 percent throughput improvement on average, while prefetching trails by 15 percent relative to BOOST. The implication for data-center operators is direct. Grace Hopper systems already ship with substantial host DRAM alongside HBM. BOOST turns that existing capacity into usable inference bandwidth without hardware changes, kernel rewrites, or additional memory purchases.
The paper does not report absolute throughput numbers in tokens per second, nor does it specify which model sizes or batch configurations were tested beyond the Grace Hopper platform. The 31 percent figure is an average across configurations; the per-model breakdown is not in the abstract. Whether the wave-aware allocation strategy generalizes to non-Grace Hopper architectures, or to systems where host memory is connected via a different interconnect, is not addressed in the available excerpt. The integration target is vLLM specifically, and no other serving framework is mentioned.
Watch whether vLLM upstreams the BOOST integration or whether Nvidia ships it as a proprietary runtime layer. The competitive question is whether AMD's MI-series platforms, which also pair HBM with host DRAM, can adopt a similar wave-aware allocation strategy. If the technique is architecture-agnostic, it becomes a software differentiator that any GPU vendor can claim. If it depends on Grace Hopper's specific memory controller behavior, the advantage stays with Nvidia's data-center stack.
The wave-aware modulo placement for static weights and the dynamic KV pool management for attention state are the two load-bearing components; neither requires hardware changes, making this a pure software-layer optimization. The 6 percent TPOT degradation from naive prefetching confirms that uncoordinated host-to-HBM transfers are counterproductive, validating the concurrent-access design over sequential staging.
TPOT improved 4.3% over HBM-only at iso-batch · Throughput improved 31% on average in high-throughput mode · Prefetching degrades TPOT by 6% · Evaluated on Grace Hopper, integrated into vLLM
After SemiEngineering. We did not report this. The pictures, if any, are theirs.