CoreWeave puts Vera Rubin NVL72 into production with a narrow SWE-2 gain
CoreWeave says Vera Rubin NVL72 is live on its cloud, with Cognition reporting up to 4.8x total token throughput for SWE-2 inference versus GB200 NVL72.
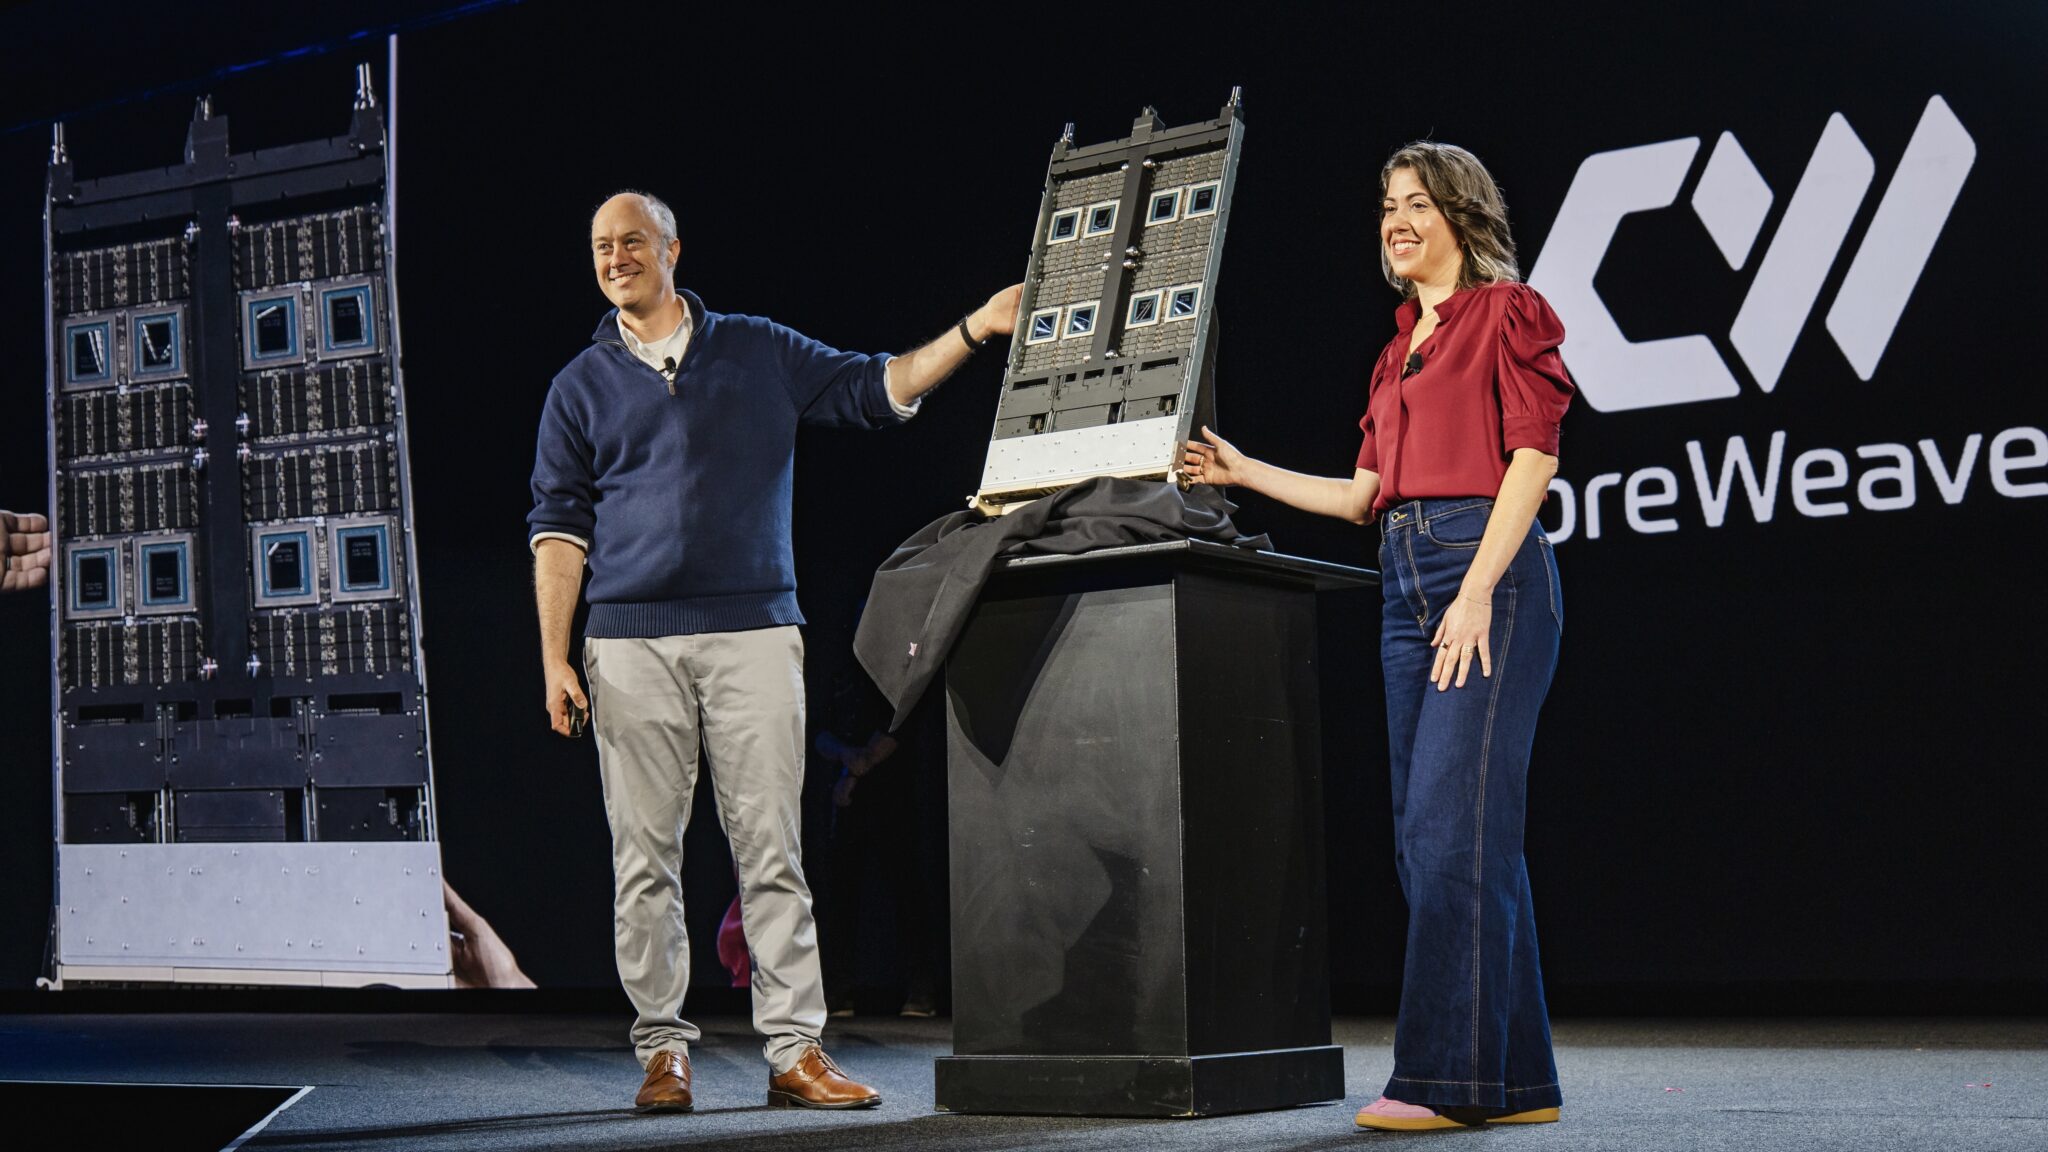
CoreWeave says Vera Rubin NVL72 systems are available on its cloud with Spectrum-X 102.4T Ethernet networking. Cognition is named as the first customer running production workloads on the platform. The packet has no readable figure, so the frame is text-only.
The document frames the gain around one inference case: Cognition sampled tasks from FrontierCode, deployed agents, and measured Vera Rubin NVL72 against GB200 NVL72. It reports up to a 4.8x increase in total token throughput for SWE-2 inference workloads. That number is the main Rubin performance figure in the primary text.
Die Brief reads the 4.8x as a workload-specific claim, not a platform-wide speedup. Buyers are constrained when they need agentic coding with long contexts and high concurrency, because those are the conditions where token volume drives cost. The number does not prove lower cost per token, lower latency, or better training performance. For the buyer, the useful change is that Rubin can be rented for a narrow production inference path, not that every workload gets the same multiplier.
What is still unmeasured is the rest of the production picture: power, latency, cost per token, and non-SWE-2 workloads. Vera CPU tests show more than 3x faster agentic sandbox startups, but that separate claim does not prove the GPU rack delivers the same gain. Pricing, capacity limits, and failure rates are also left out.
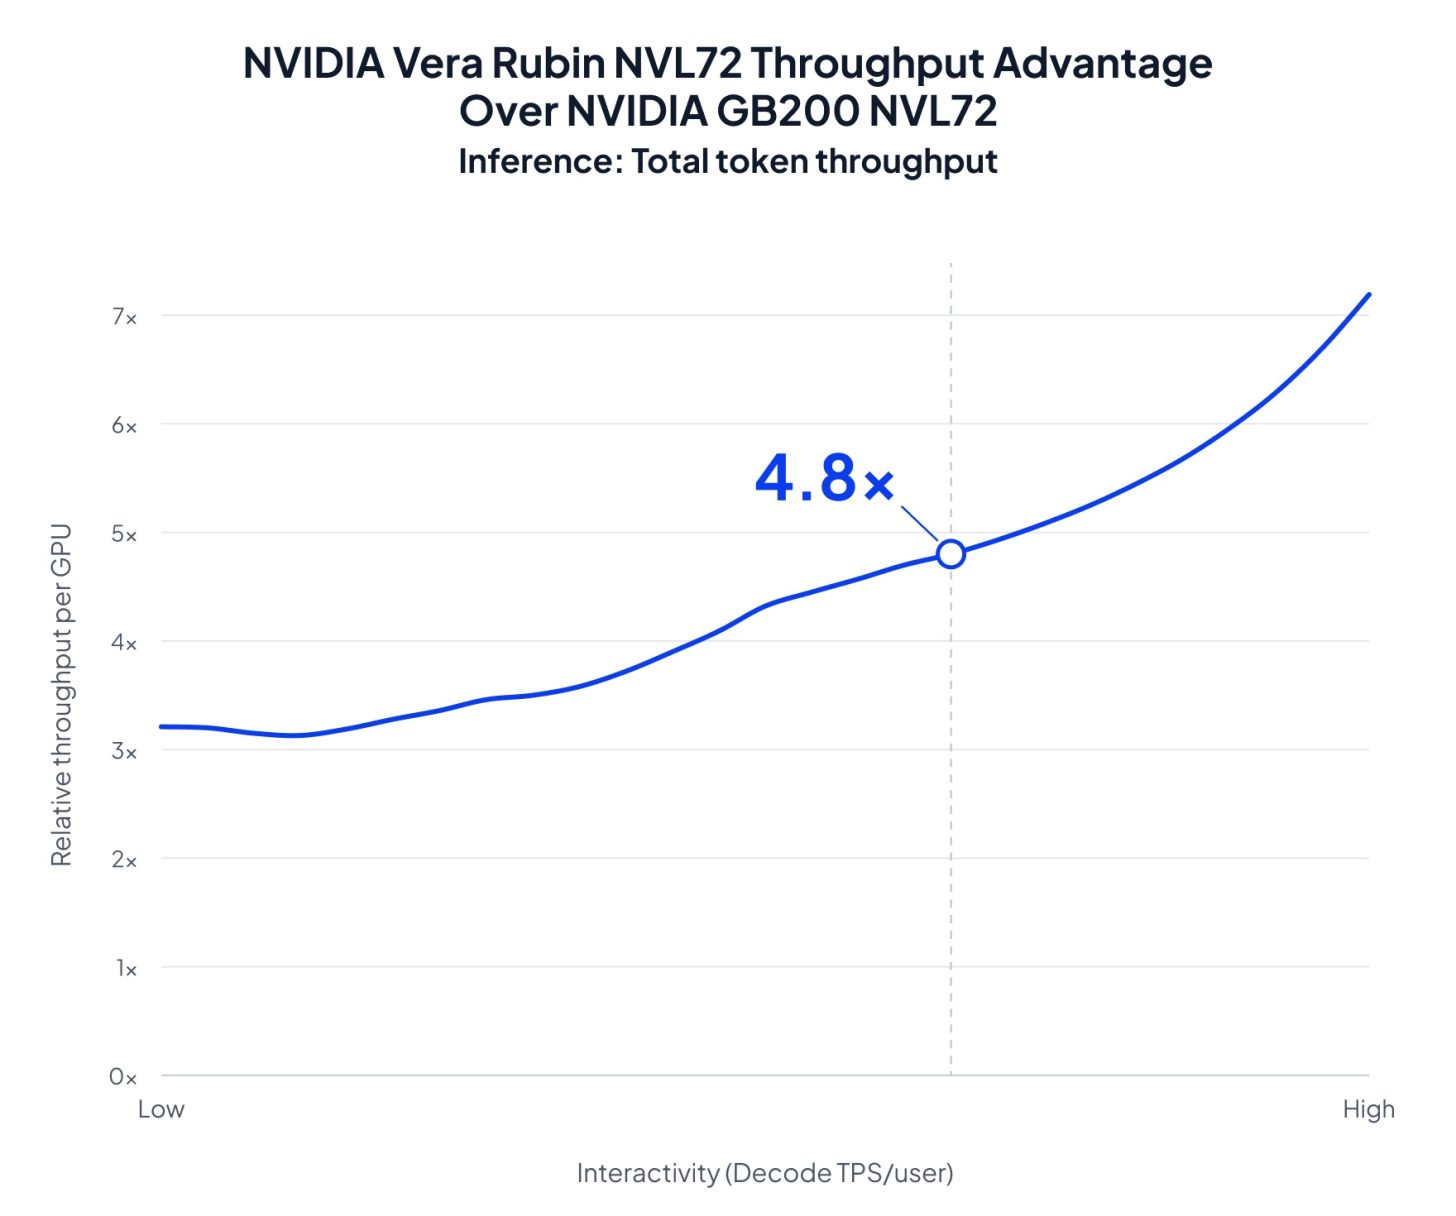
Die Brief reads the 4.8x as a workload-specific claim, not a platform-wide speedup. It constrains buyers who need agentic coding with long contexts and high concurrency, and it does not prove lower cost per token or latency.
The document does not measure power, latency, cost per token, or non-SWE-2 workloads.
The primary document supports a Rubin inference gain only for SWE-2-style agentic coding, so buyers should treat it as a stack-level result, not a general GPU multiplier.
Vera Rubin NVL72 · Spectrum-X 102.4T Ethernet networking · 4.8x increase in total token throughput · SWE-2 inference workloads · GB200 NVL72 · more than 3x faster agentic sandbox startups
After signal65.com. We did not report this. The pictures, if any, are theirs.