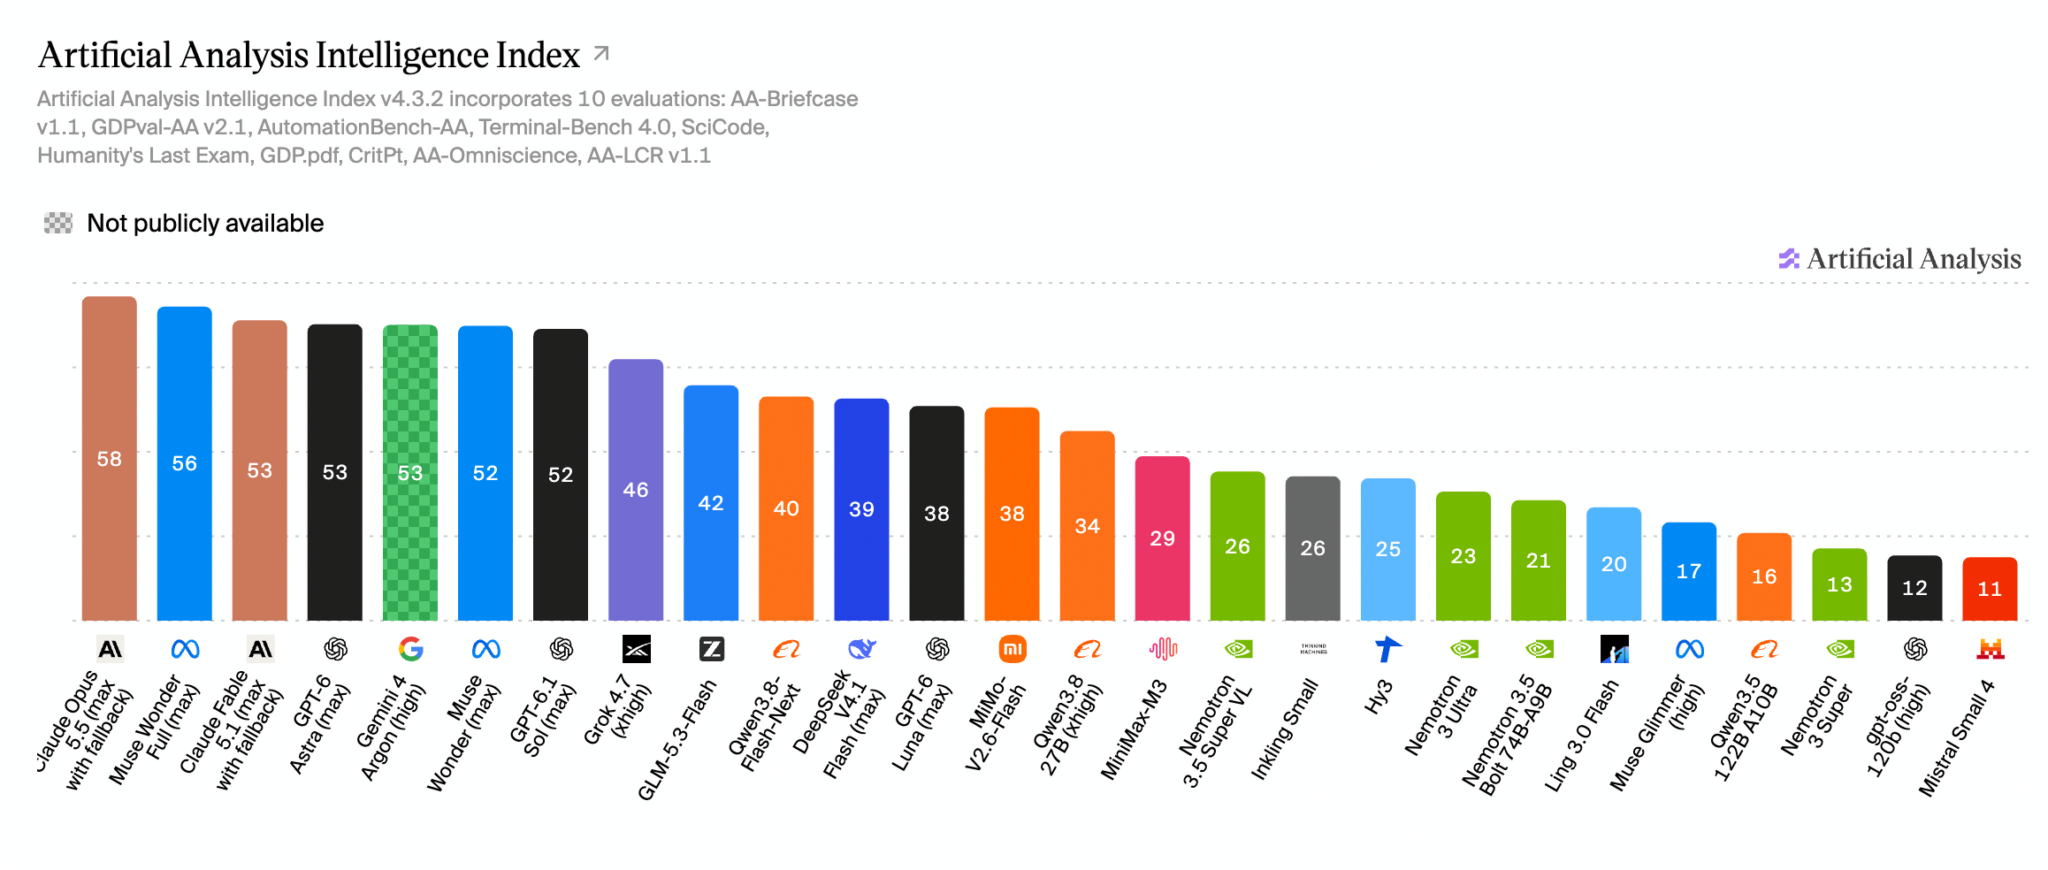
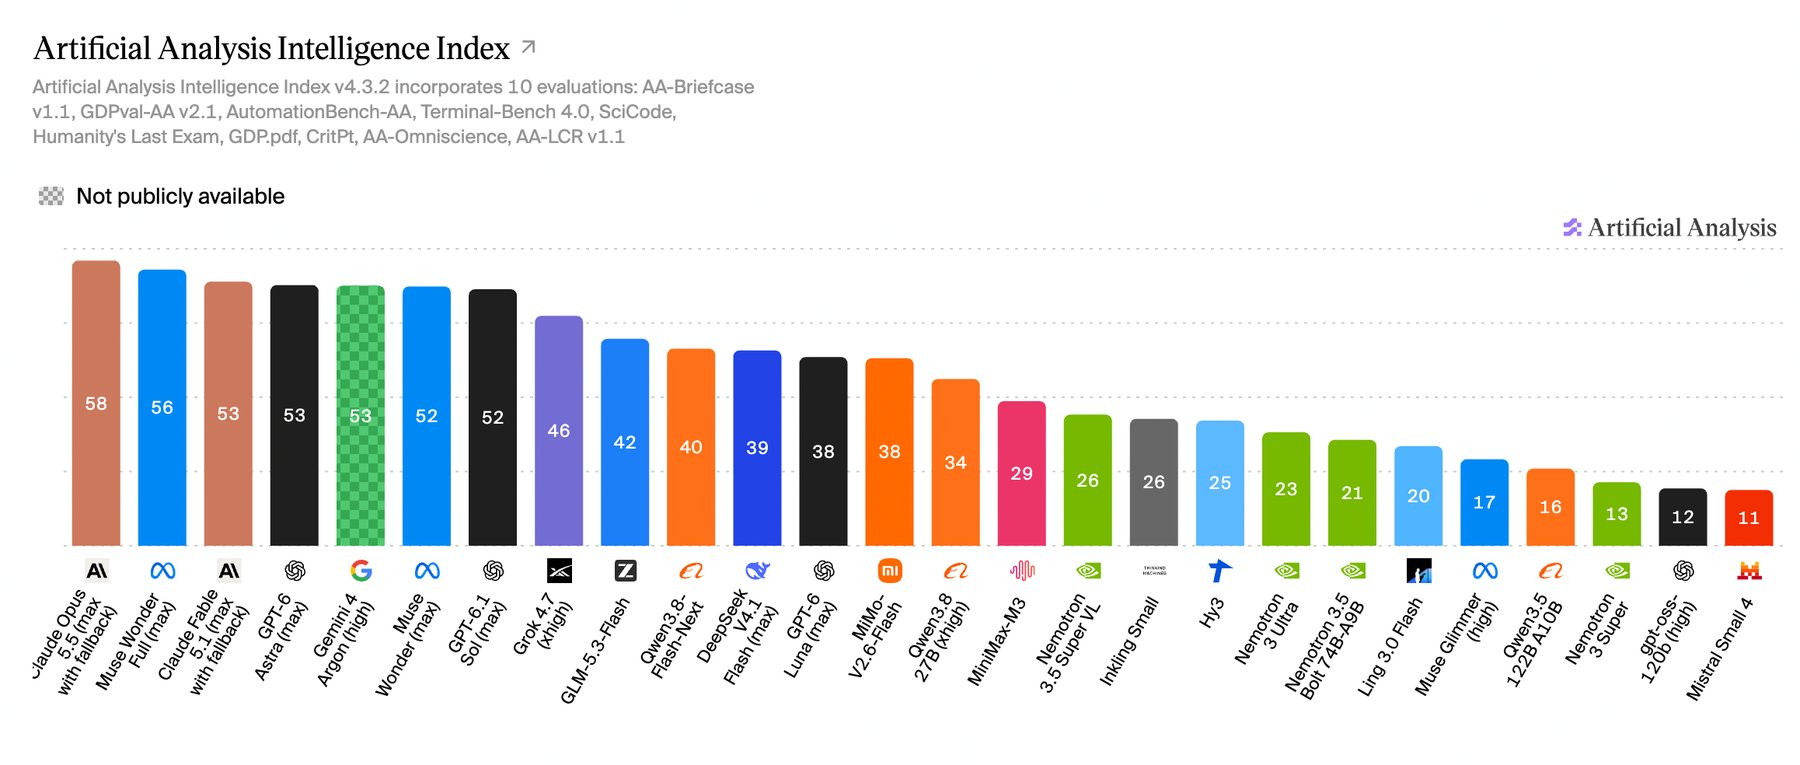
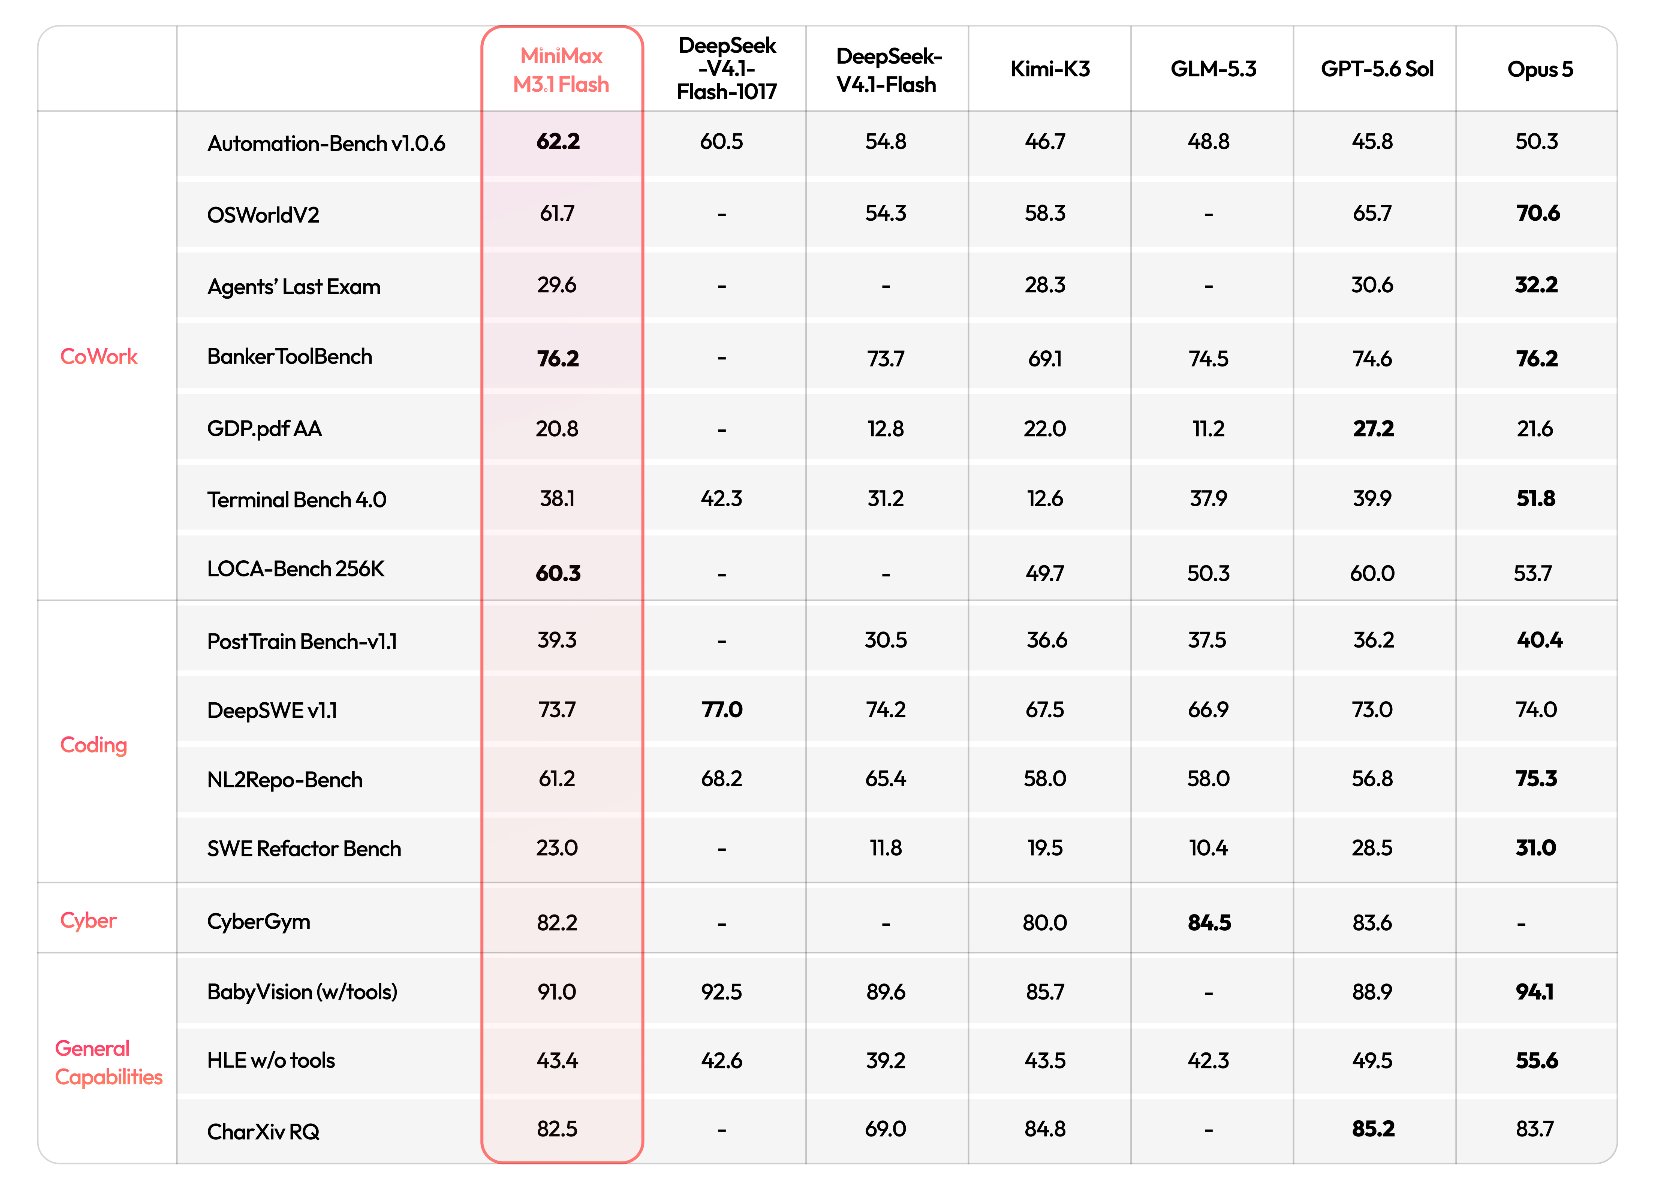
Nvidia releases a compressed 24GB local agent checkpoint
The 2.0625-bit quantization is the key detail in Nvidia's Nemotron 3.5 Bolt 24GB release.
| Nemotron 3.5 Bolt 74B-A9B 24GB | |
|---|---|
| parameters | 74B-A9B |
| active parameters | 9B |
| parent parameters | 120B-A12B |
| quantization | IQ2_XXS at 2.0625 bits per element |
| AIPerf SPEED-Bench-Coding TPS | 83.99 |
| AA AgentPerf Local Replay Duration (s) | 600.80 |
| memory footprint | 24GB |
Nvidia says the model is compressed from Nemotron 3.5 Super VL. The parent model has 12B active and 120B total parameters, while the checkpoint has 9B active and 74B total parameters.
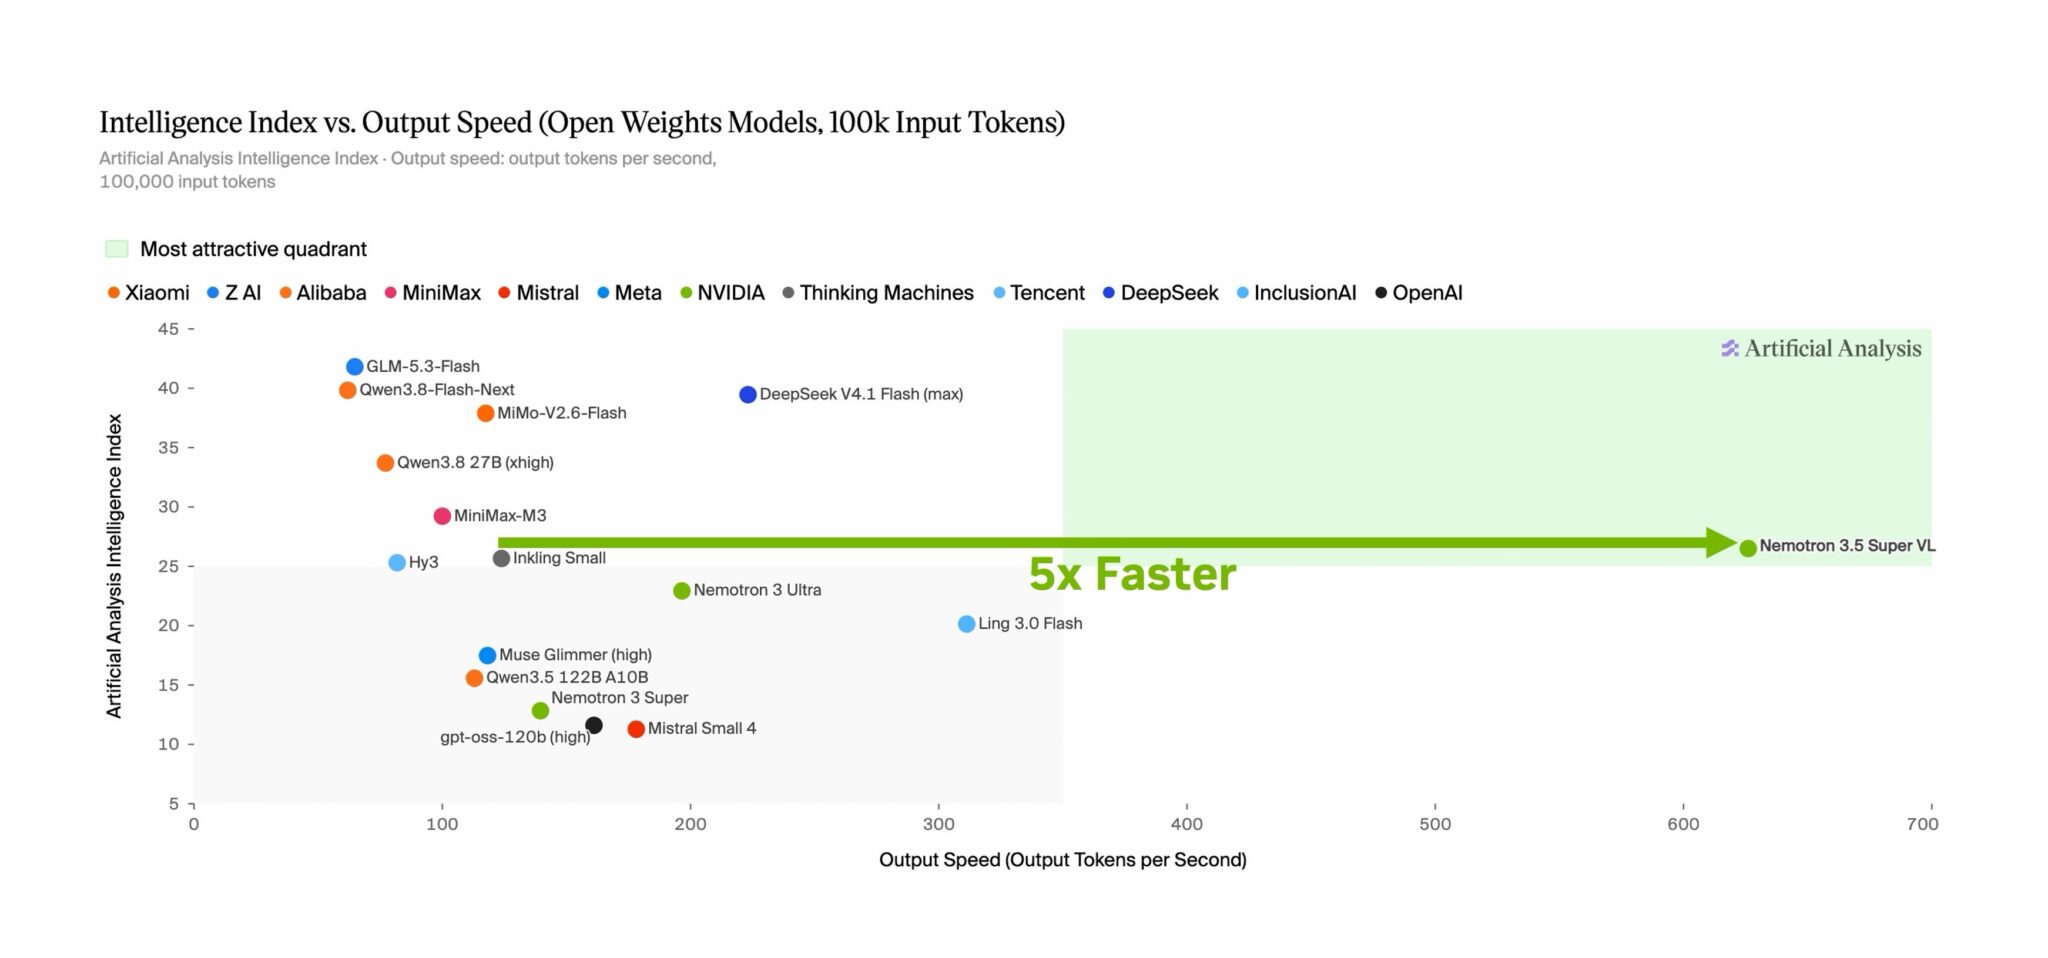
The report calls the checkpoint a local agent model for RTX/DGX Spark. It reports 84 TPS on AIPerf SPEED-Bench on RTX Spark.
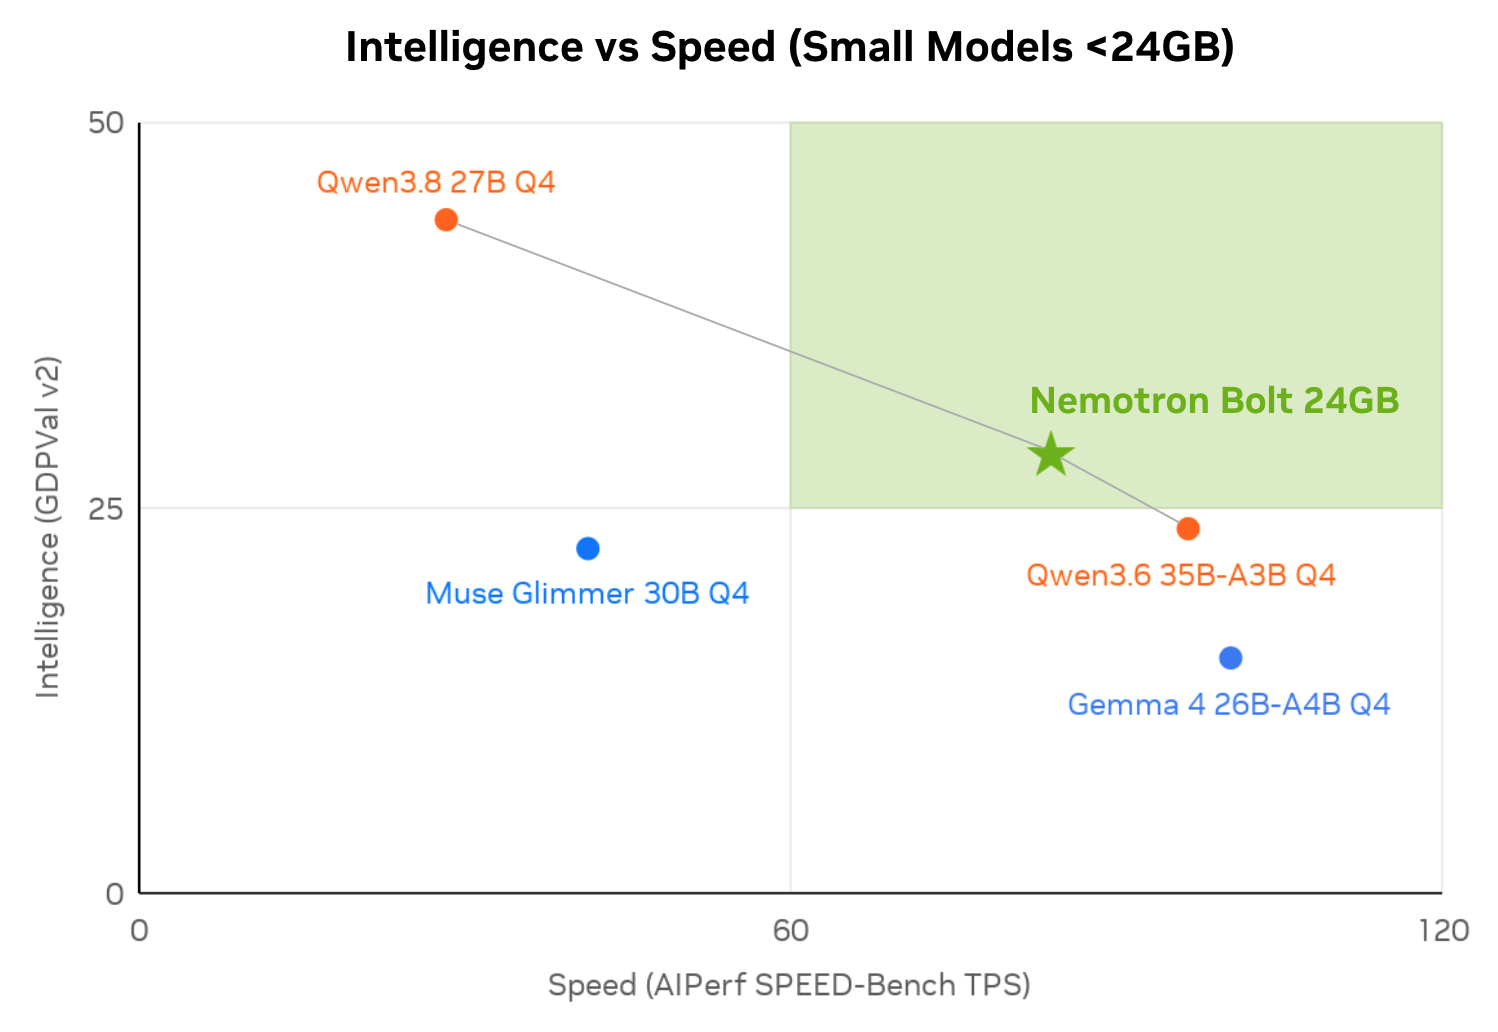
The 24GB memory budget is the binding constraint. The draft says the checkpoint can sit on RTX/DGX Spark, but it does not establish that Super VL is released, priced, or measured outside the compression path.
Unmeasured items include Super VL standalone accuracy, context length, price, and enterprise latency under production concurrency. Power draw and memory bandwidth are also absent.
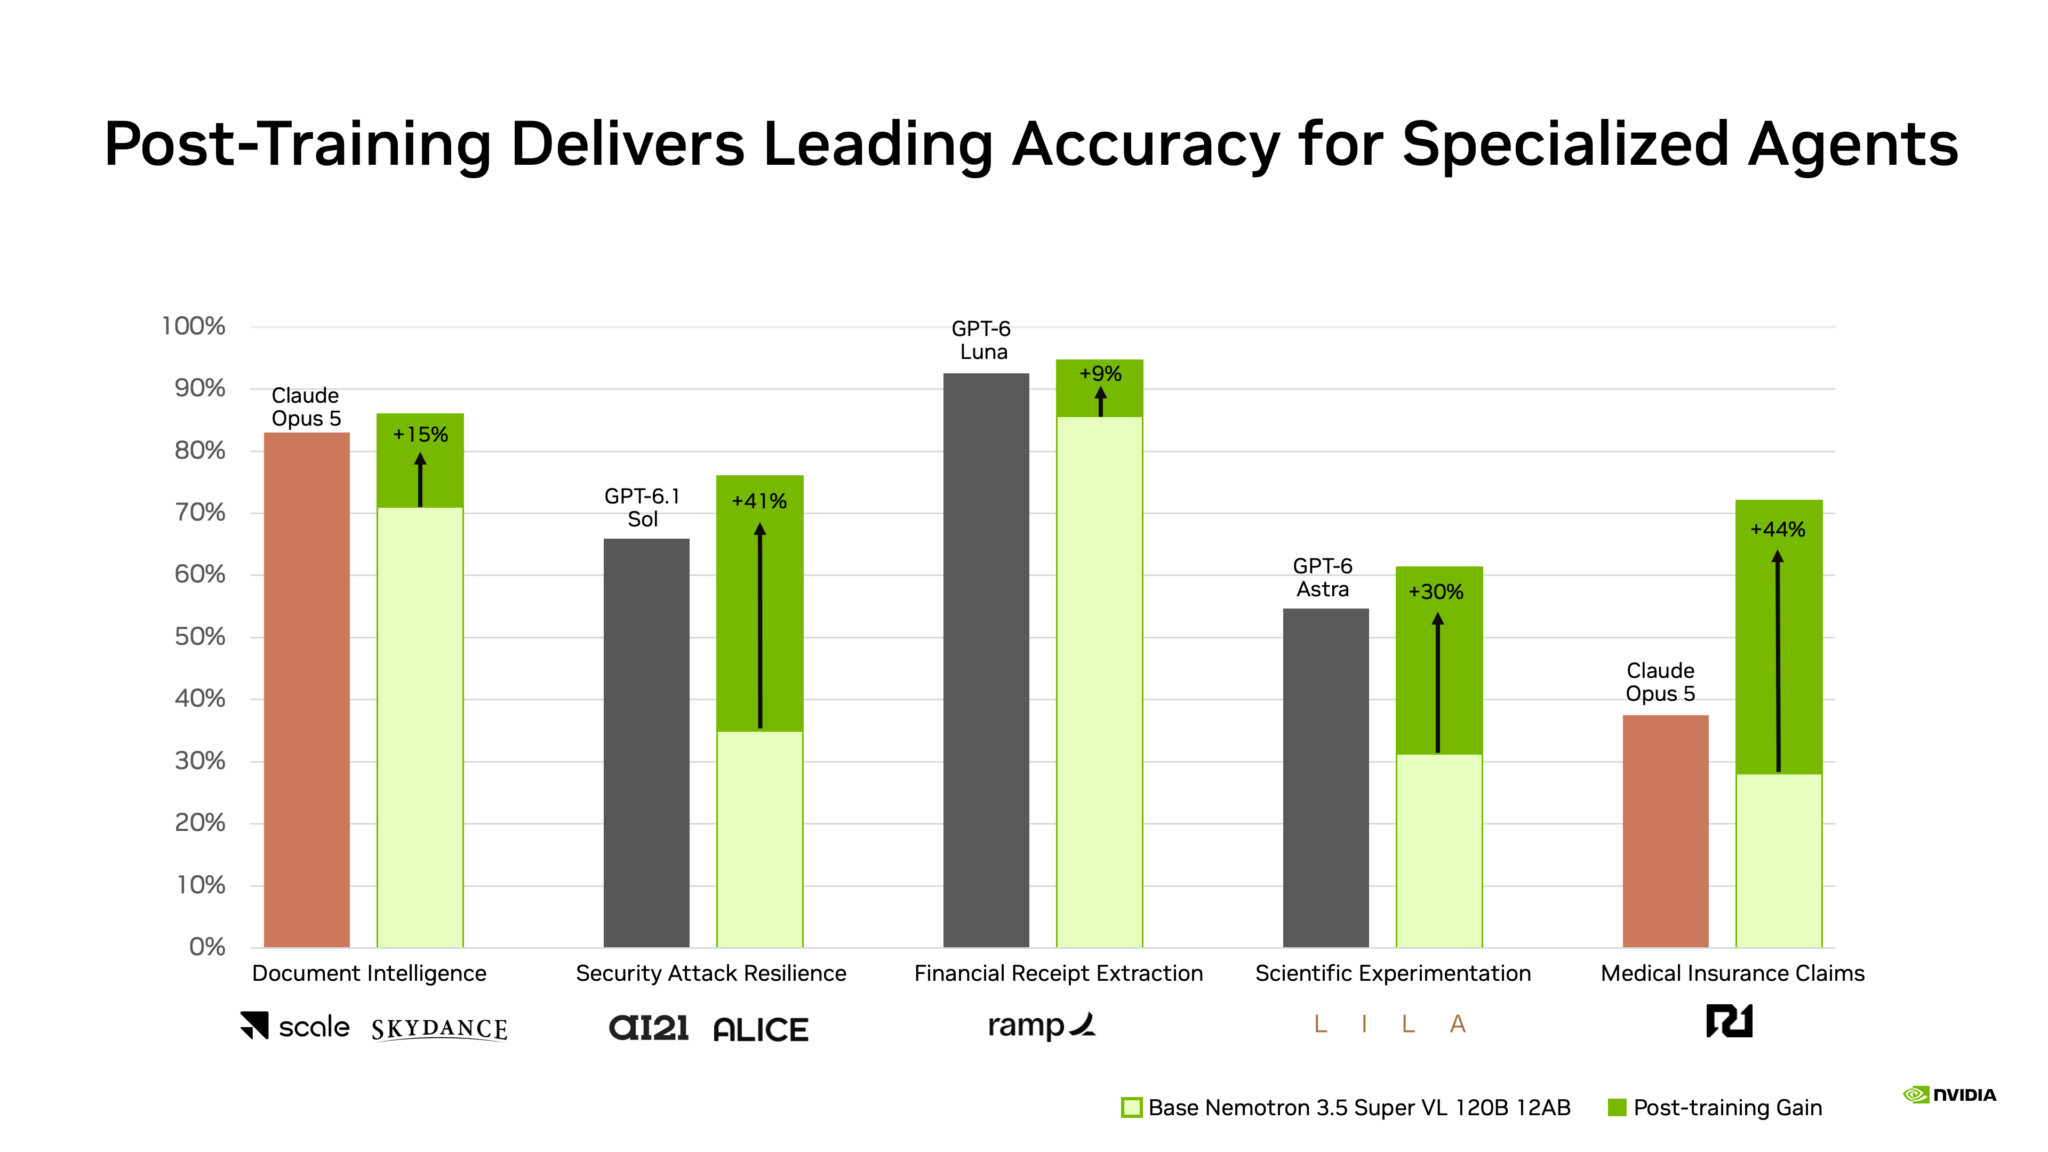
The 84 TPS figure is tied to the stated setup. The draft does not say it holds outside llama.cpp, Windows 11 ARM x64, and RTX Spark.
The change is a local agent checkpoint with a speculative drafter. It is not a general-purpose enterprise model with published cloud costs.
The release is a compressed local agent checkpoint, not a proof that the parent model is released or that enterprise latency is met.
After research.nvidia.com. We did not report this. The pictures, if any, are theirs.