Nvidia's open Nemotron agent model moves to enterprise and edge
Open weights are the lead, with enterprise agents first and two Bolt memory tiers behind it.
| Nemotron 3.5 Super VL | Nemotron 3.5 Bolt 74B-A9B 24GB | Nemotron 3.5 Bolt E4B 4GB | |
|---|---|---|---|
| parameters | 120 billion | 74B-A9B | E4B |
| memory | 24GB | 4GB | |
| ship date | available now | available now | Oct. 23 |
| benchmark | 5x faster | ||
| size comparison | roughly one-fifth of largest reasoning model |
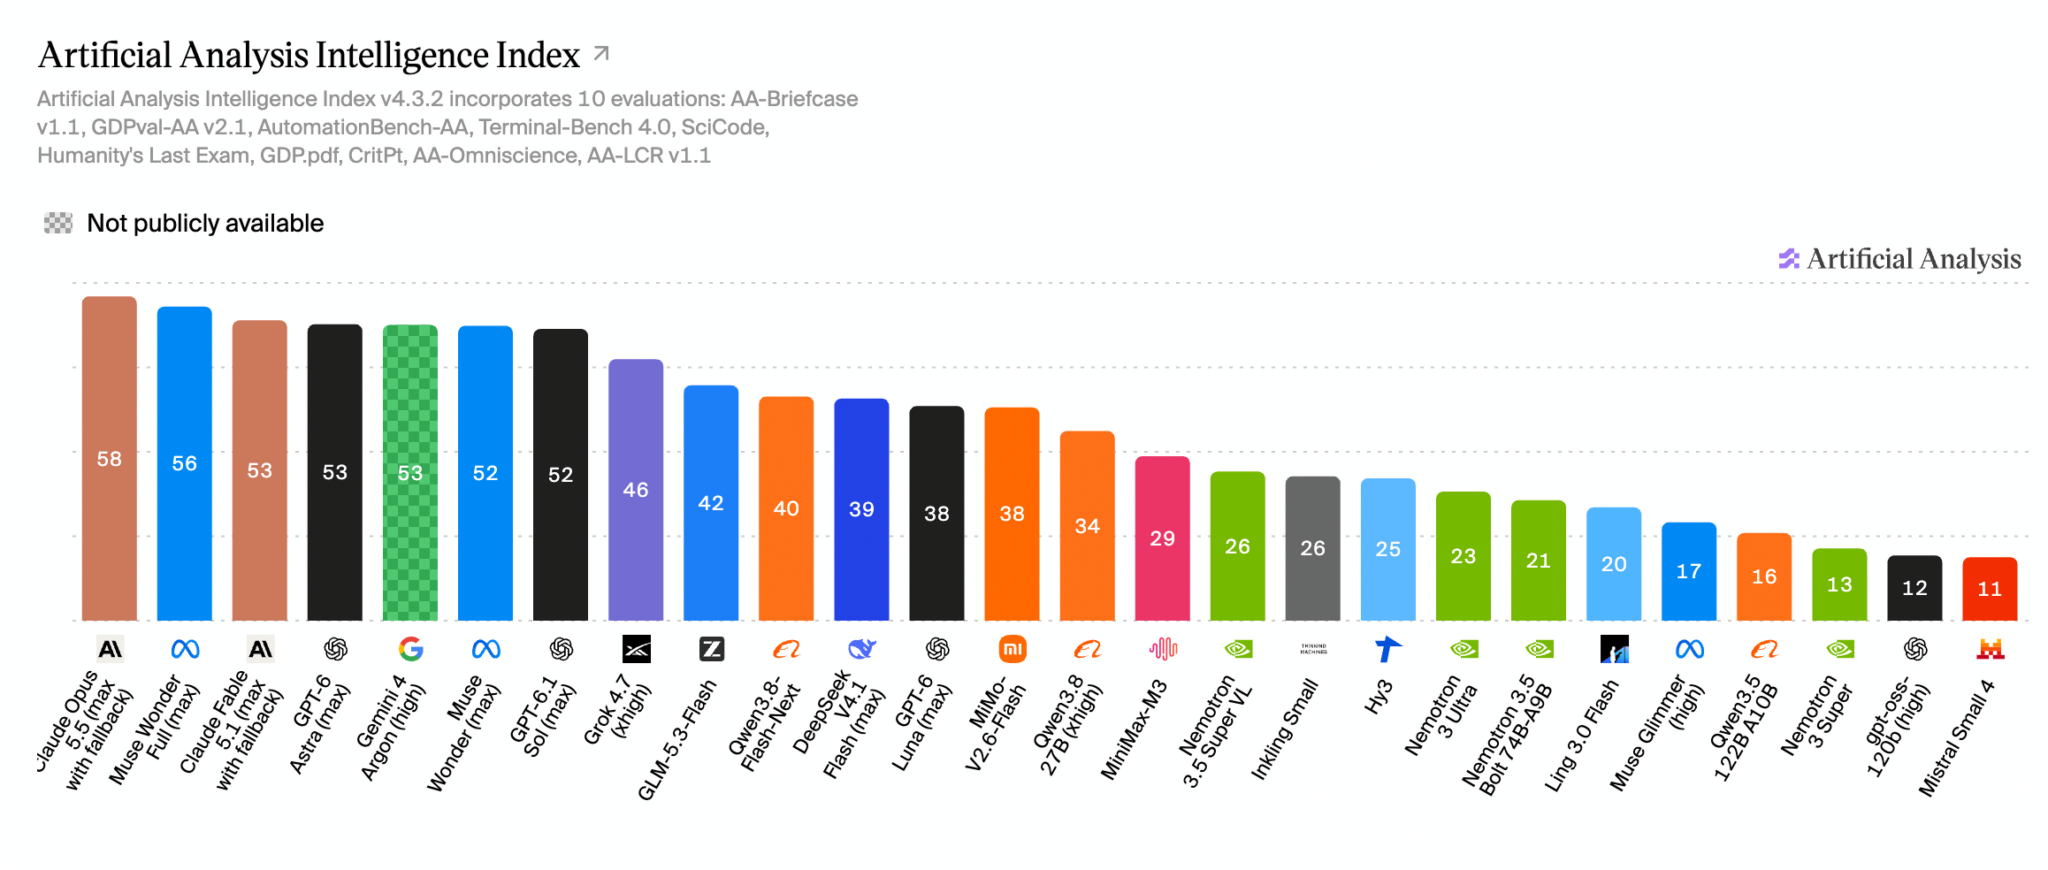
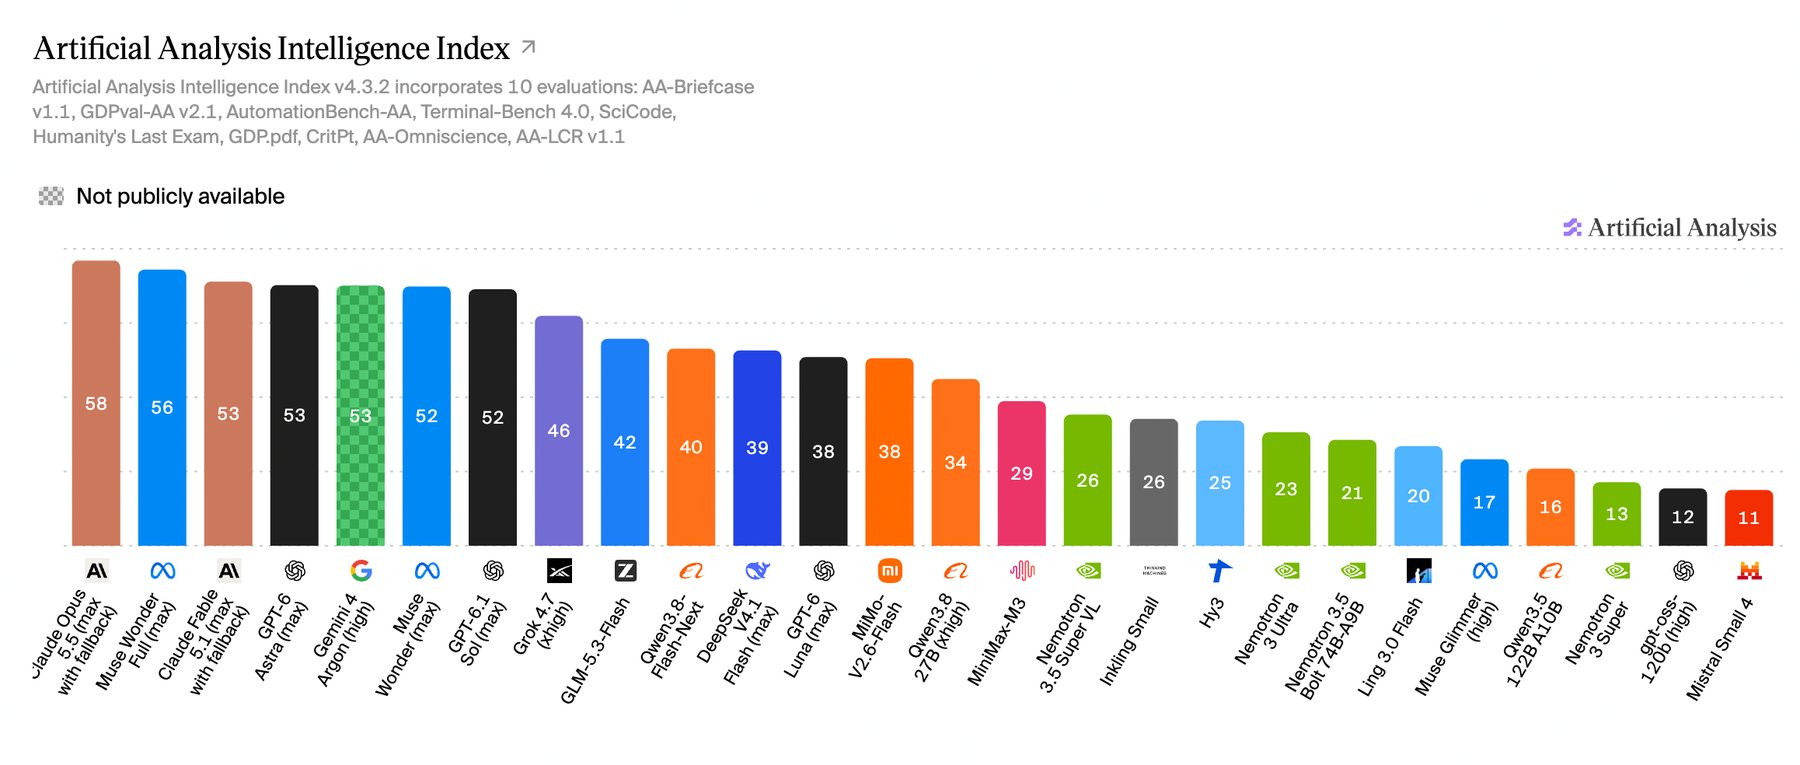
The 120-billion-parameter open model is built for continuous enterprise agents, and only 12 billion parameters are active per token.
The enterprise buyer gets open weights, but the page ties the models to Nvidia infrastructure and local Nvidia systems.
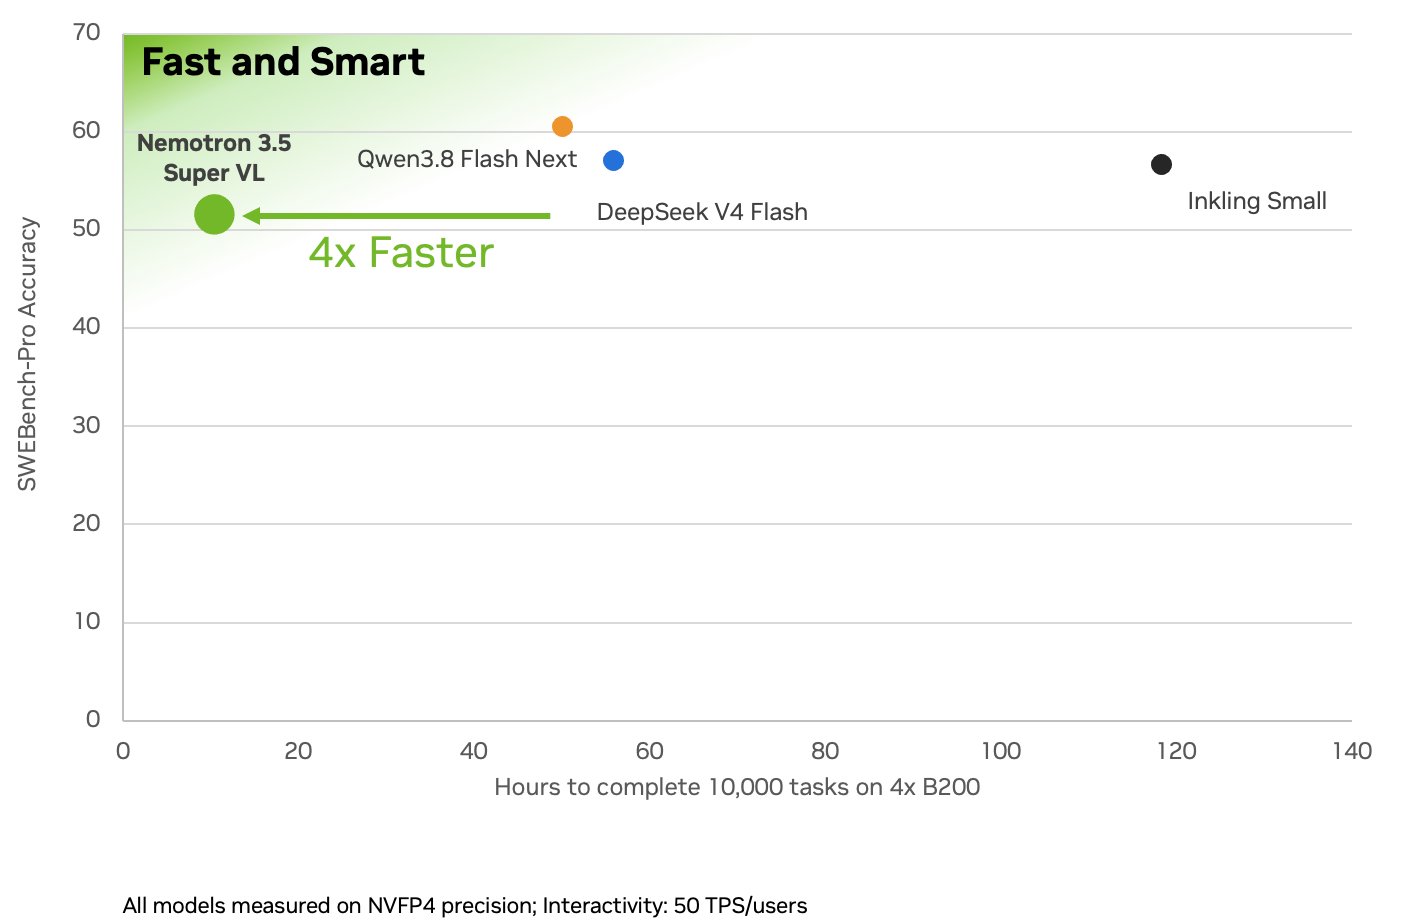
The 24GB Bolt model is available now, and the 4GB version is scheduled for Oct. 23.
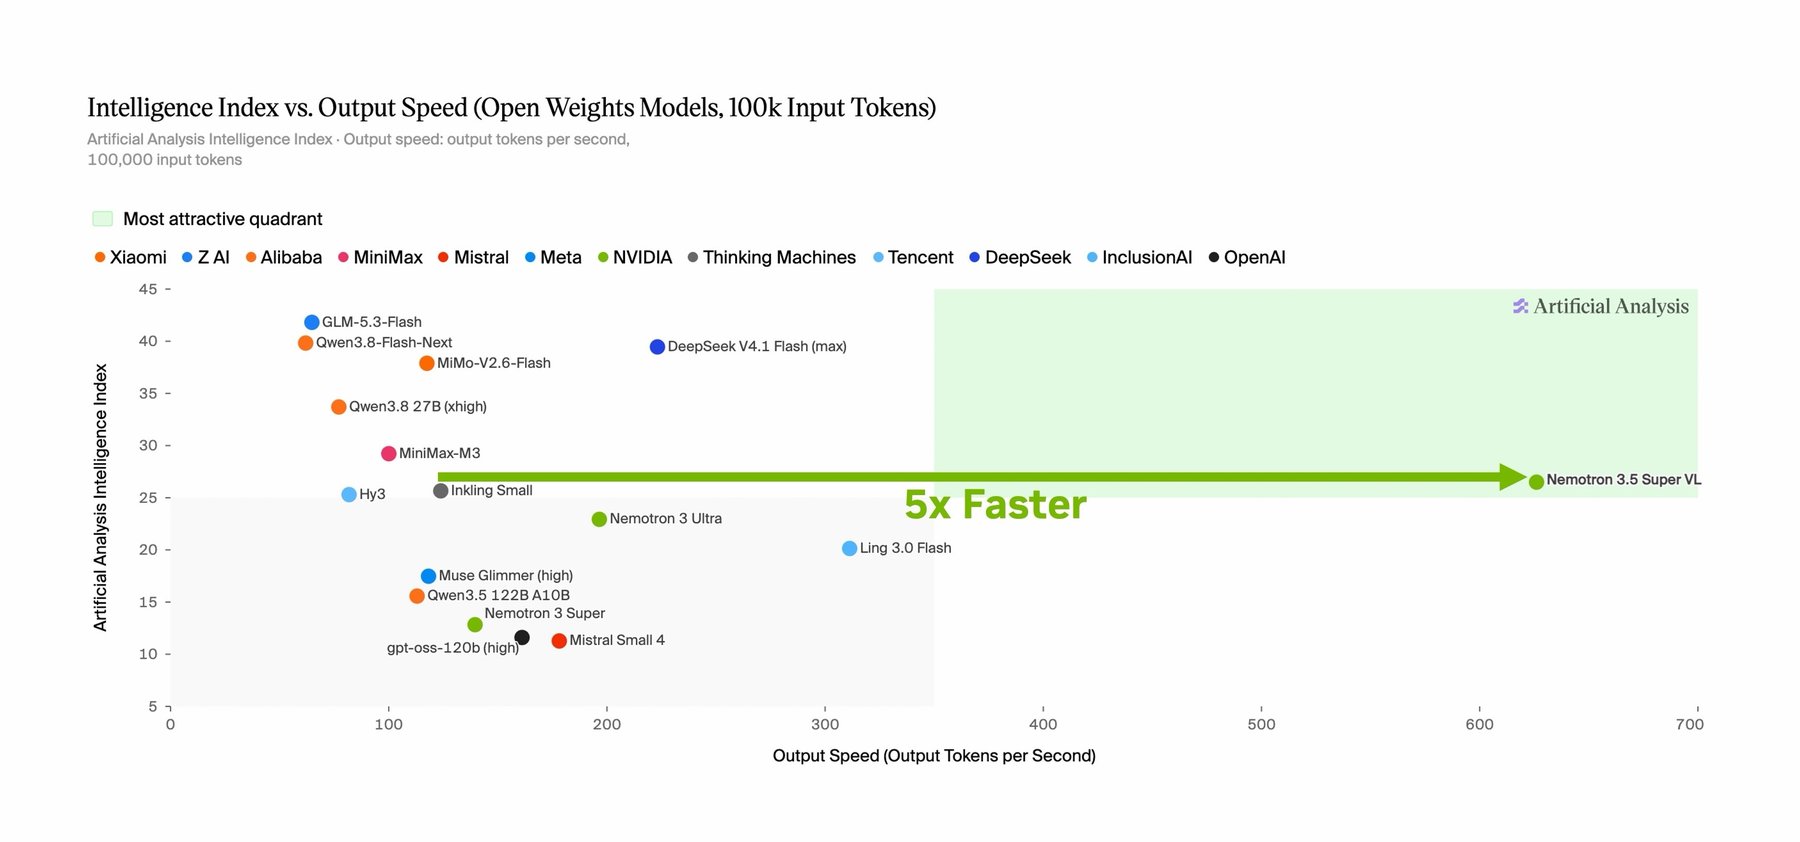
The accuracy claim is a one-fifth-size comparison with Nvidia's largest reasoning model, not a proof that Super VL beats every closed frontier model.
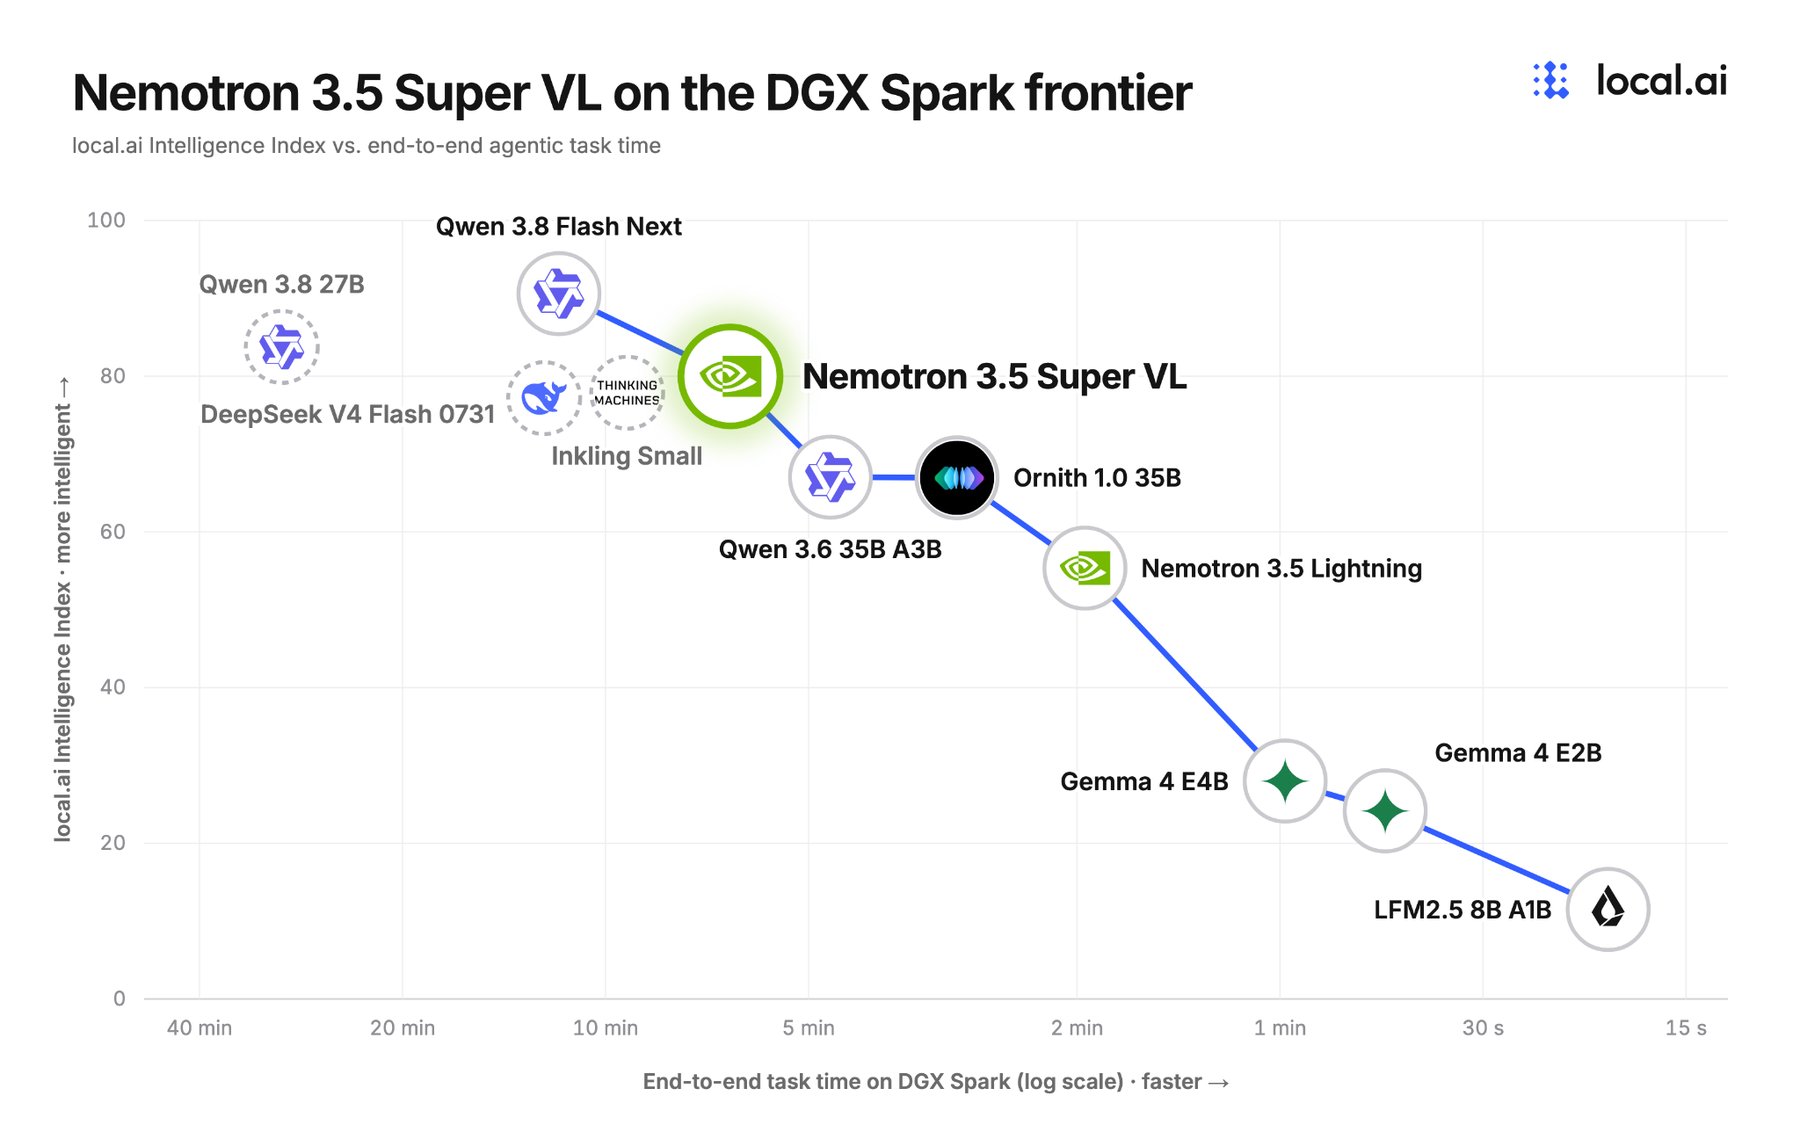
The 5x speed figure, independent accuracy, and throughput outside Nvidia's own claims remain unmeasured.
The token cost per agent task, latency on local systems, and edge-model accuracy also stay open.
The useful shift is open enterprise agents, but the Nvidia stack still shapes the cost.
After github.com. We did not report this. The pictures, if any, are theirs.