NVIDIA and IIT Madras open a 2.8-trillion-token Indic corpus
Native-script tokens outnumber romanized tokens in the Indic corpus, and the generation recipe is open.
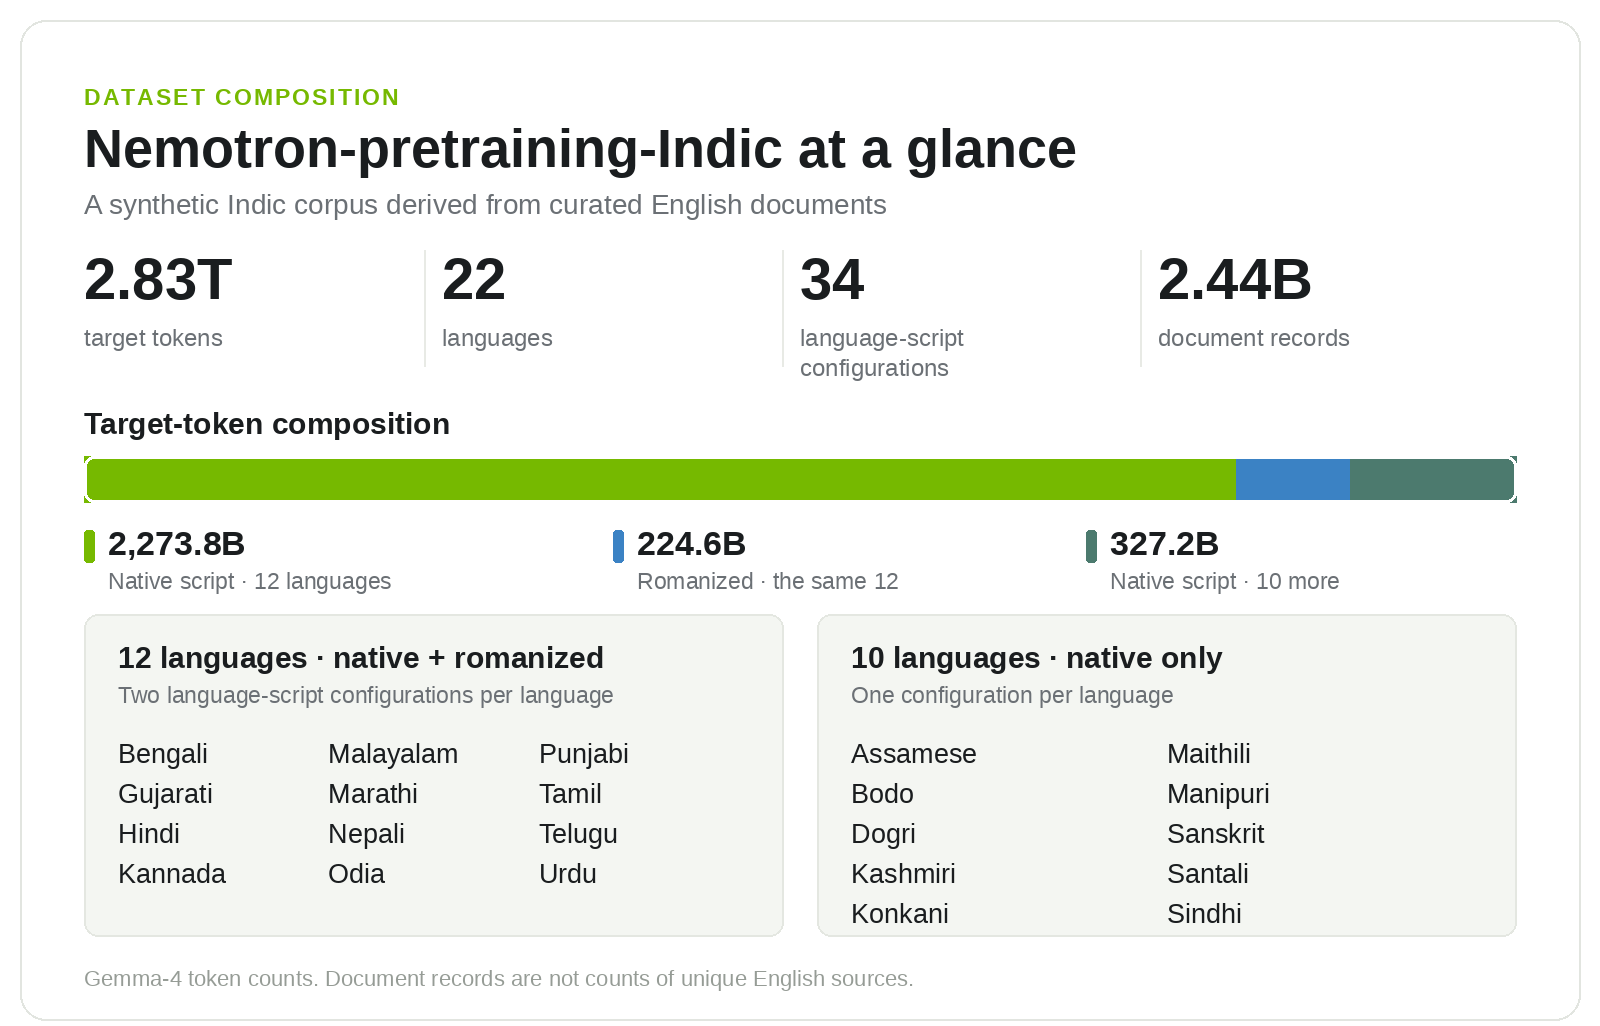
| Nemotron-pretraining-Indic-v1 | |
|---|---|
| total tokens | 2.8 trillion tokens |
| native-script tokens | 2,601.0 billion |
| romanized tokens | 224.6 billion |
| languages | 22 |
| romanized languages | 12 |
| language-script configurations | 34 |
| tokenizer | Gemma-4 |
| recovered tokens | 438.4 billion |
The release pairs Nemotron-pretraining-Indic-v1 with an open GPU-accelerated pipeline.
The corpus covers 22 Indian languages. It holds about 2.8 trillion tokens.
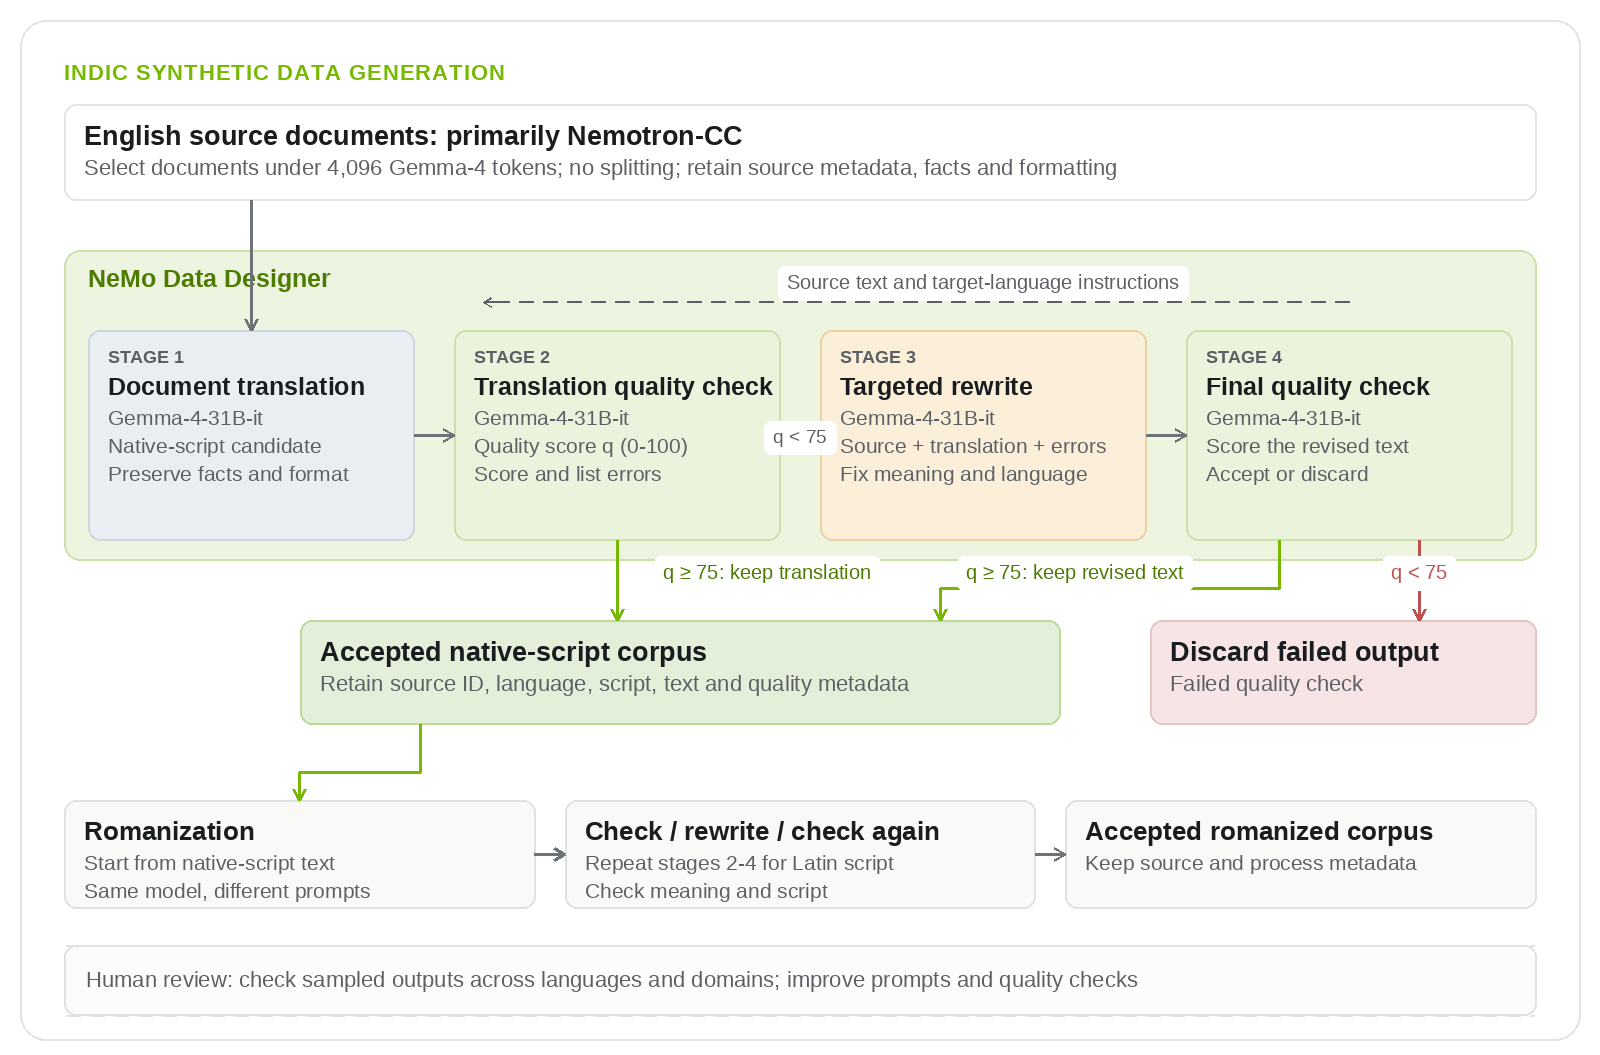
Native-script data covers all 22 languages, while romanized text covers twelve.
Counts use the Gemma-4 tokenizer. The workflow keeps outputs scoring at least 75 out of 100.
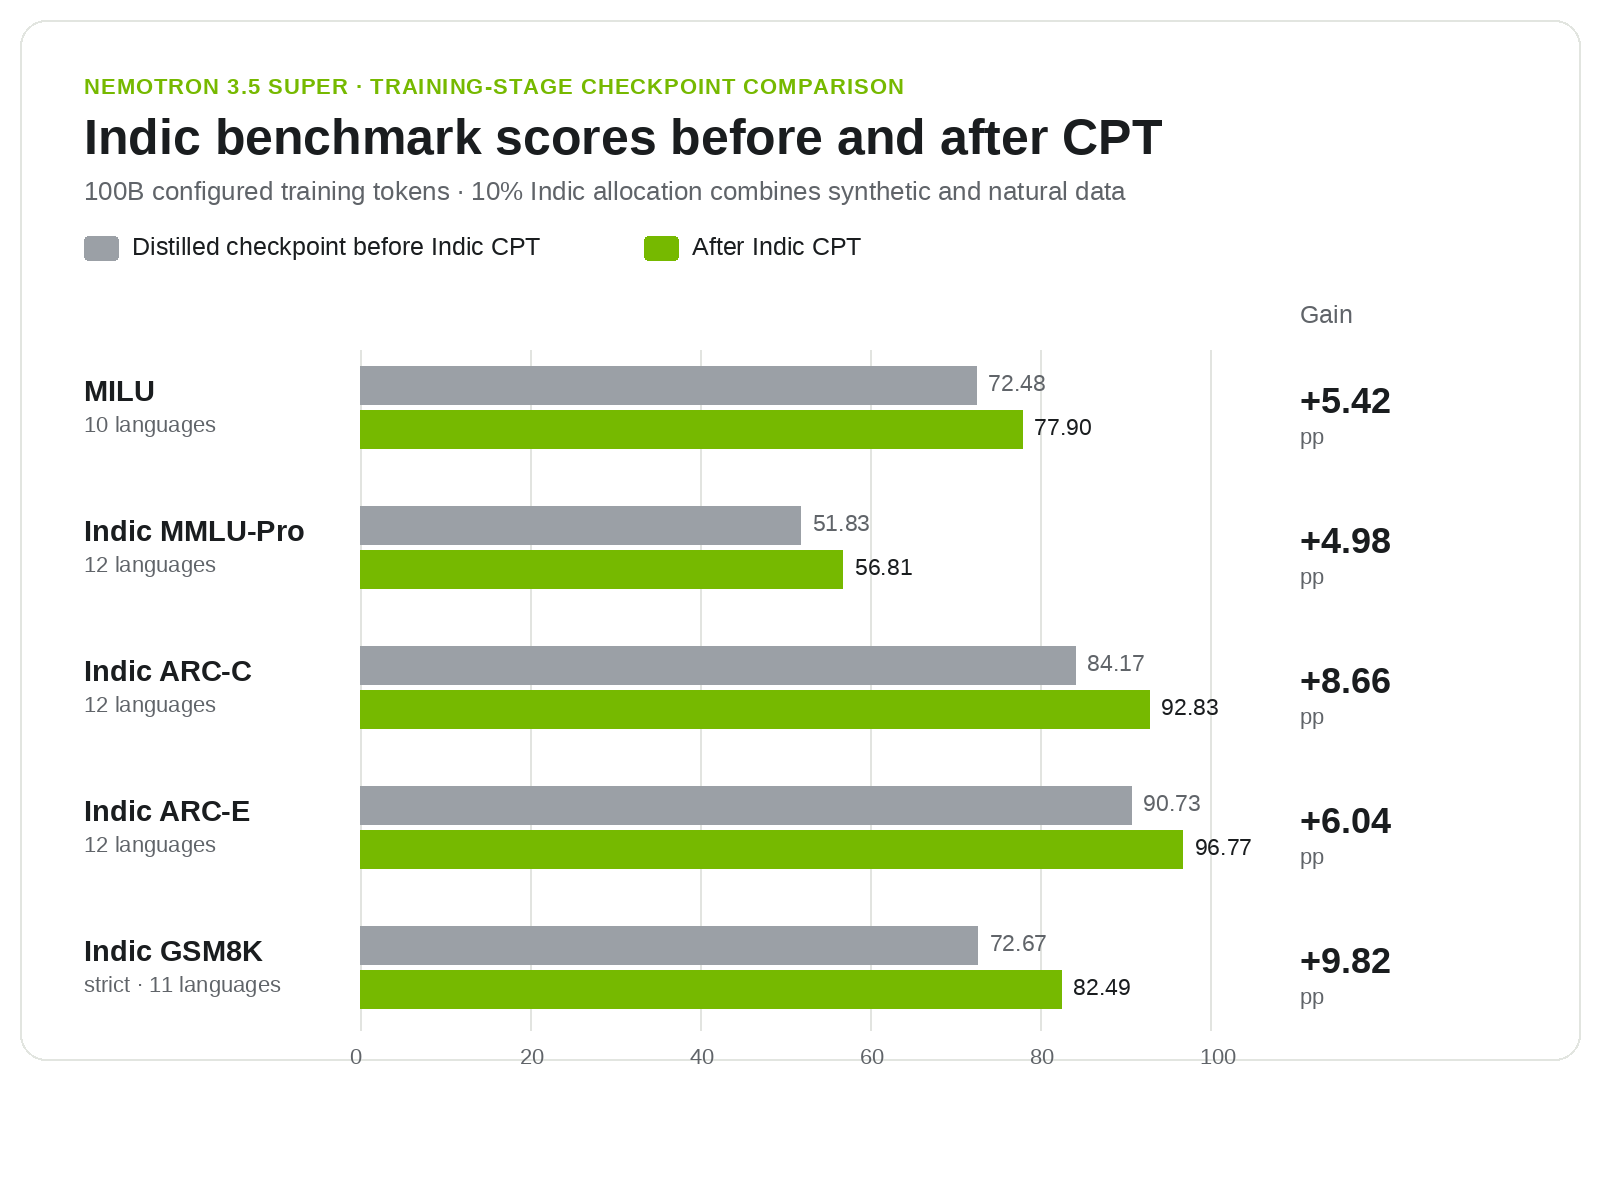
The measured effect is tied to Nemotron 3.5 Super VL. A 10 billion-token Indic continued-pretraining stage raised five benchmarks by 4.98 to 9.82 points.
The corpus alone is not measured. The release does not isolate synthetic Indic text from natural Indic text, and it does not report the same gains for other models, languages, or mixtures.
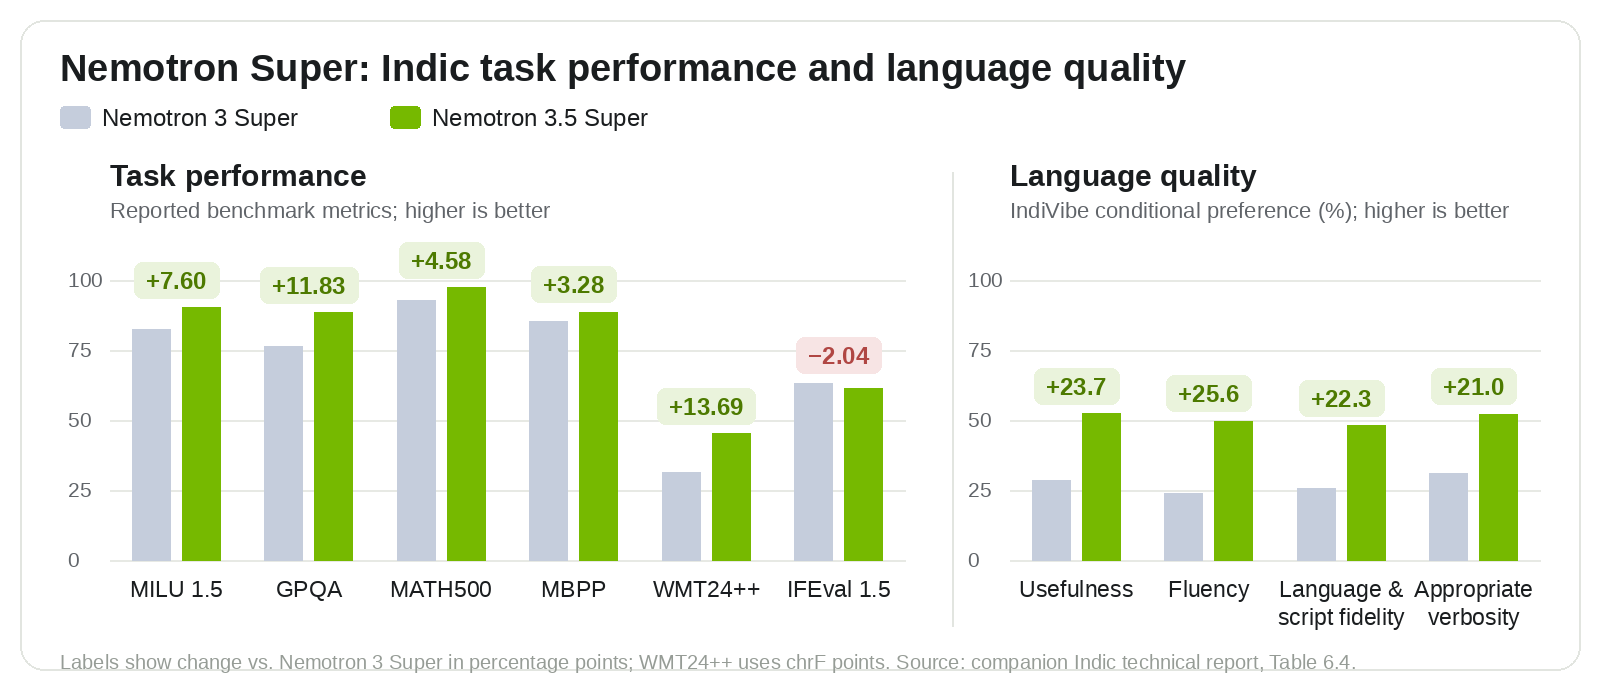
The corpus is a data supply, not a model result. Its value is proven only for one Nemotron checkpoint and one mixture.
Buyers should treat the token count as inventory, not as a guarantee of transferable gains.
The corpus is inventory, not proof of transferable gains.
After huggingface.co. We did not report this. The pictures, if any, are theirs.