Hy4 ships with vision and computer use, weights still locked
Tencent's Hy4 can read a 2.8-gigapixel aerial image and drive Blender, but Claude Opus 5.5 leads it on all twelve internal benchmarks and the weights remain unreleased.
| Hy4 | |
|---|---|
| Internal benchmarks | 12 (Claude Opus 5.5 leads all 12) |
| GPT 6.1 Sol wins | 8 of 12 |
| Hallucination rate | ~16% before, ~5% after |
| Finance test | 200+ professionals, ~600 tasks |
| Weights | not released, date unspecified |
| Availability | Tencent Cloud, OpenRouter, Yuanbao |
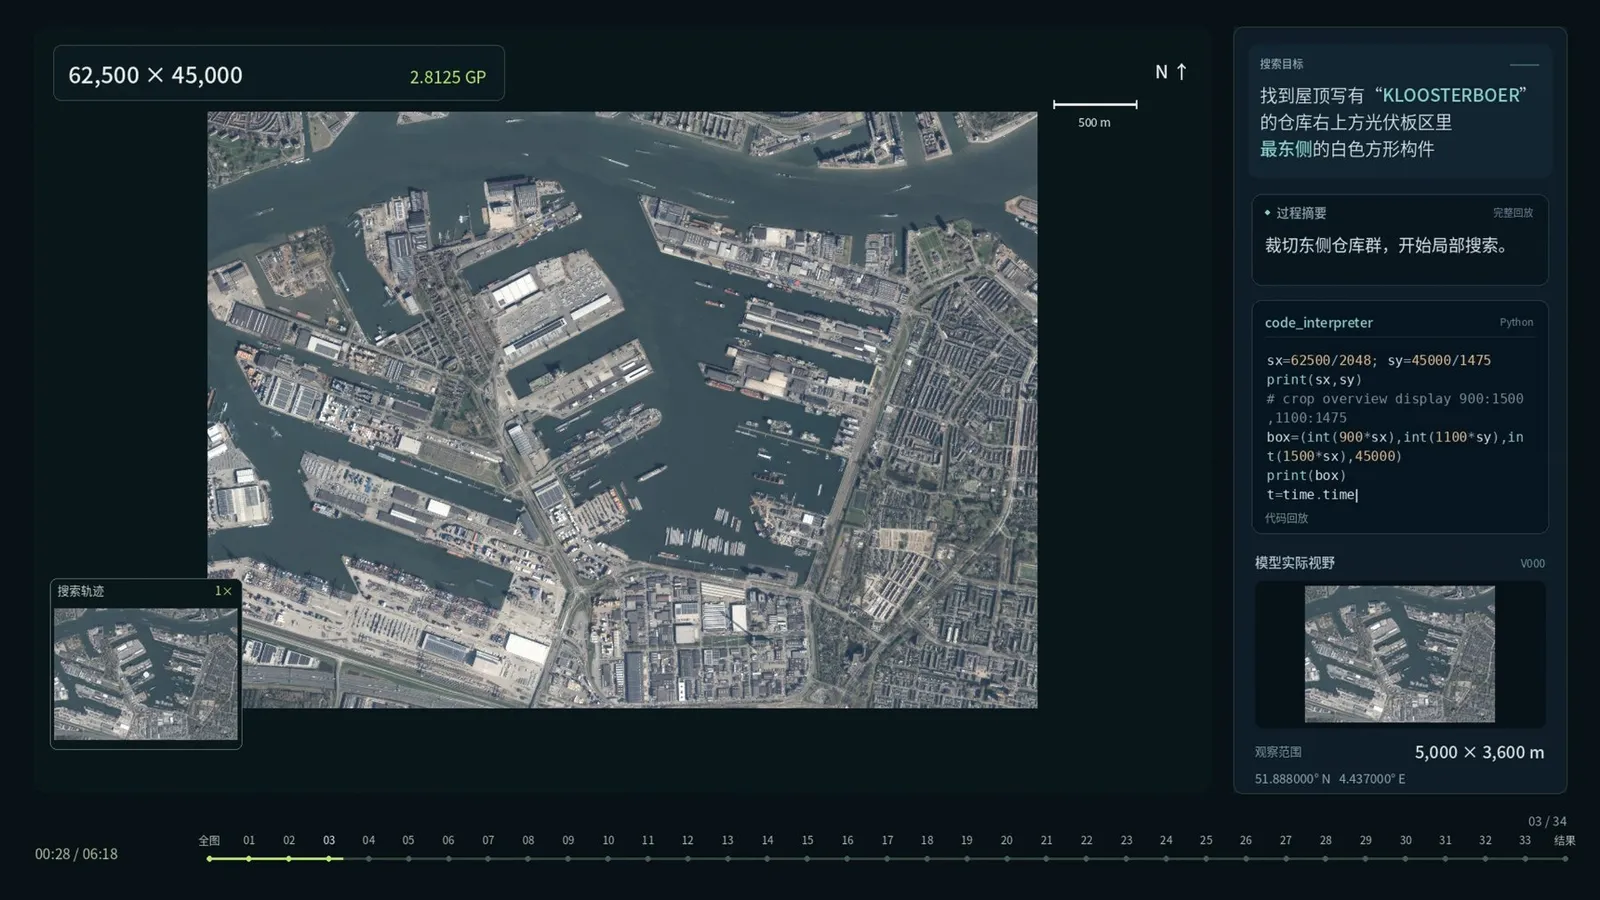
Tencent's Hy4, released November 4, 2026, can read a 2.8-gigapixel aerial image and locate a roughly two-meter component on a warehouse roof, and it can drive Blender, CAD tools, and game engines without a human in the loop. The model is available through Tencent Cloud, OpenRouter, and the Yuanbao app. The weights are not public. The release date for them is "still-unspecified" in Tencent's own materials.
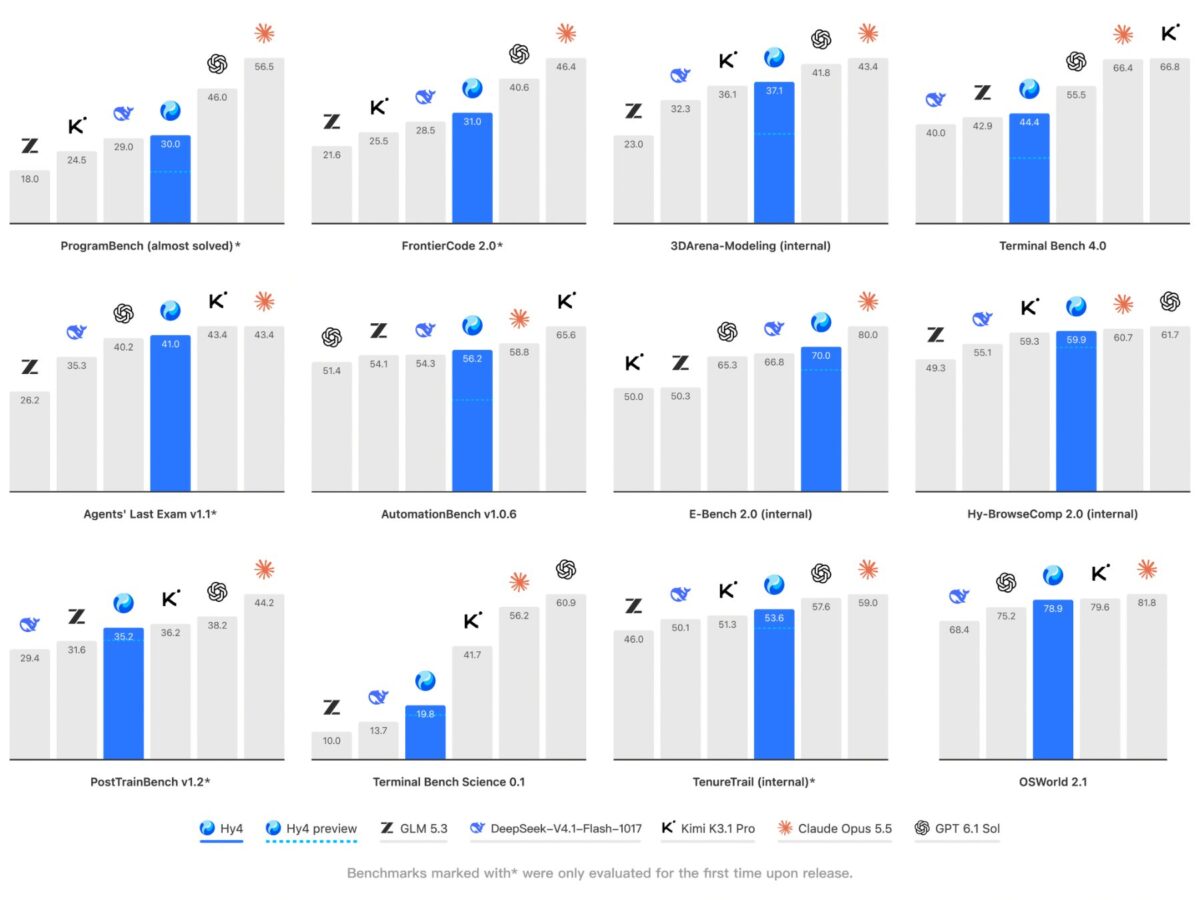
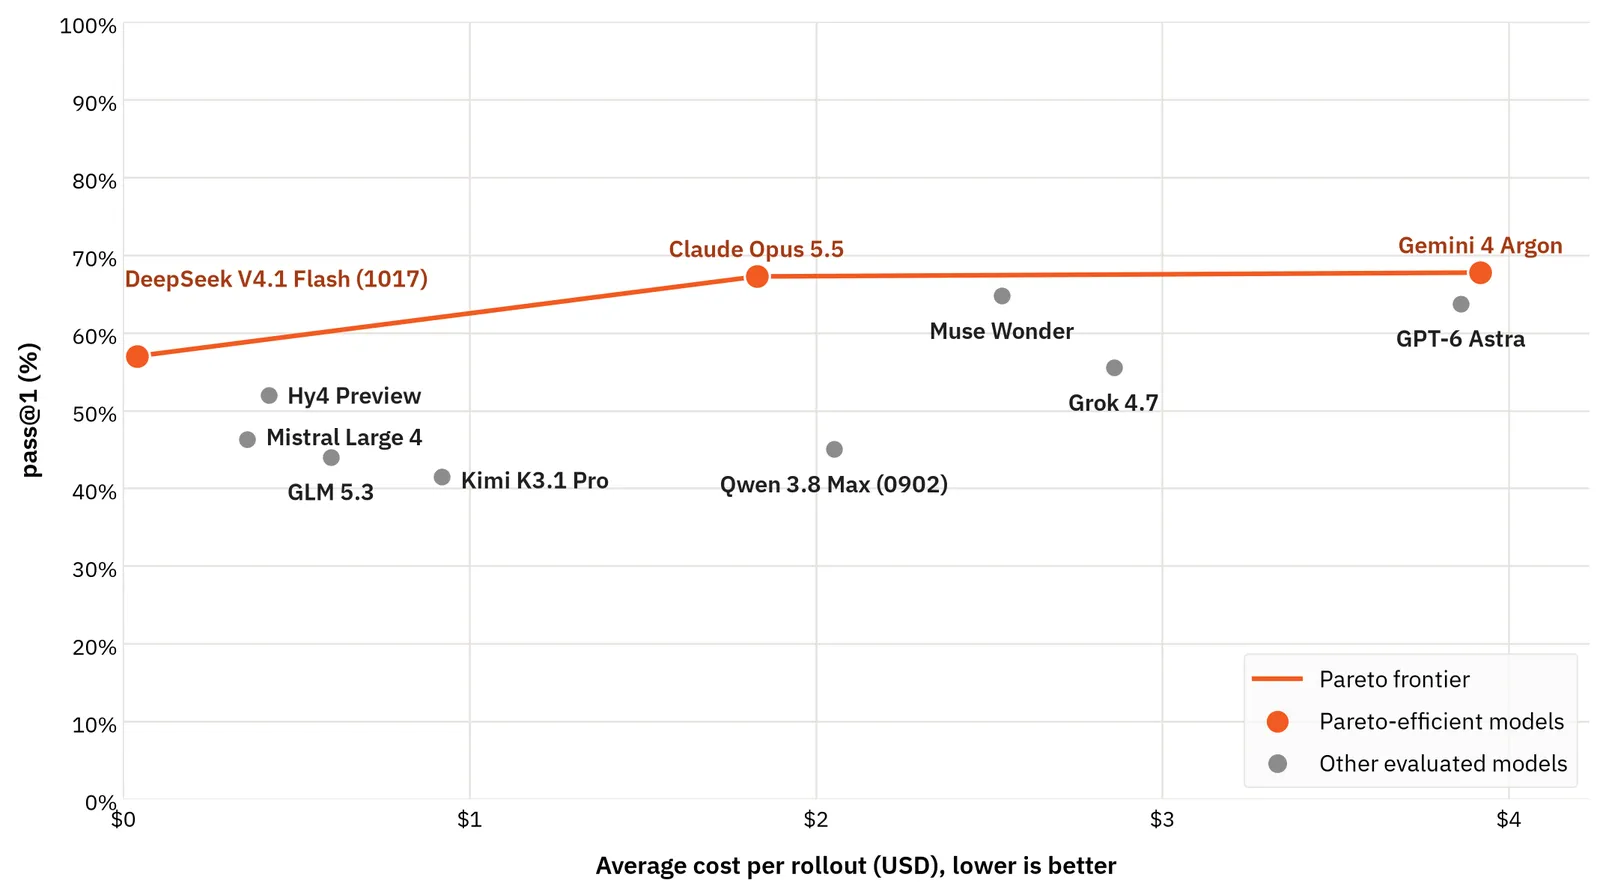
The figure that matters is the twelve-benchmark grid Tencent published alongside the launch. Claude Opus 5.5 leads Hy4 on all twelve. GPT 6.1 Sol takes eight of the twelve. In a separate finance test with over 200 professionals on nearly 600 real-world tasks, Hy4 ranked ahead of Deepseek V4.1 Flash, Kimi K3.1 Pro, and GLM-5.3 Flash. The hallucination rate in internal tests fell from nearly 16 percent to about 5 percent after a search revamp.
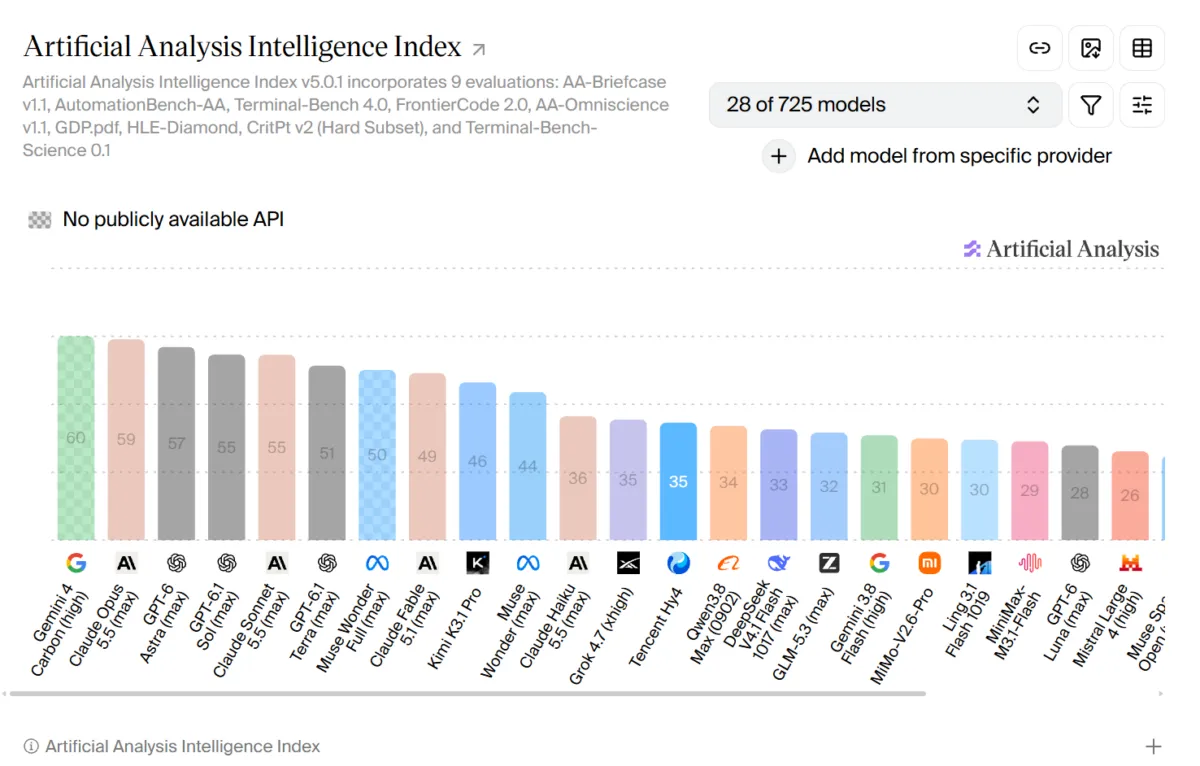
The constraint is structural, not technical. Tencent will not release weights until a date it has not set, so no third party can verify the training data, reproduce the twelve-benchmark scores, or confirm the hallucination figure. The second-place ranking among Chinese models rests on Artificial Analysis, which The Decoder cites but does not reproduce in full. A buyer on OpenRouter gets an API endpoint, not a model they can audit. The gap to Claude Opus 5.5 on hard math and coding is the number that will matter when the weights finally drop, because that is where the training-data question becomes testable.
Parameter count, dataset size, individual per-benchmark scores, and the weight-release date appear in no document in the packet. The 2.8-gigapixel demo is a single image, not a benchmark. The finance test names three rivals but gives no per-task scores.
The constraint is not the model's capability but the absence of weights: no third party can verify training data or reproduce the twelve-benchmark grid until Tencent sets a release date. The second-place ranking among Chinese models is an API-level claim, not a reproducible one.
Without weights, the twelve-benchmark scores and the 16-to-5 percent hallucination drop are vendor-internal numbers. The buyer on OpenRouter is purchasing an endpoint, not a model. The gap to Claude Opus 5.5 on hard math and coding becomes testable only after the weights drop.
After hy.tencent.ai. We did not report this. The pictures, if any, are theirs.