CWE-bench v2's open-weight field spans 13 points the blog skips
Four open-weight models span 13 points on the CWE-bench v2 leaderboard, but the blog post that introduced the 100-task, 91-CWE benchmark names only one of them.
| DeepSeek-V4.1-Flash-1017 | Hy4-preview | GLM-5.3 | |
|---|---|---|---|
| Resolve Rate | 57 | 52 | 44 |
| Cost per rollout | $0.04 |
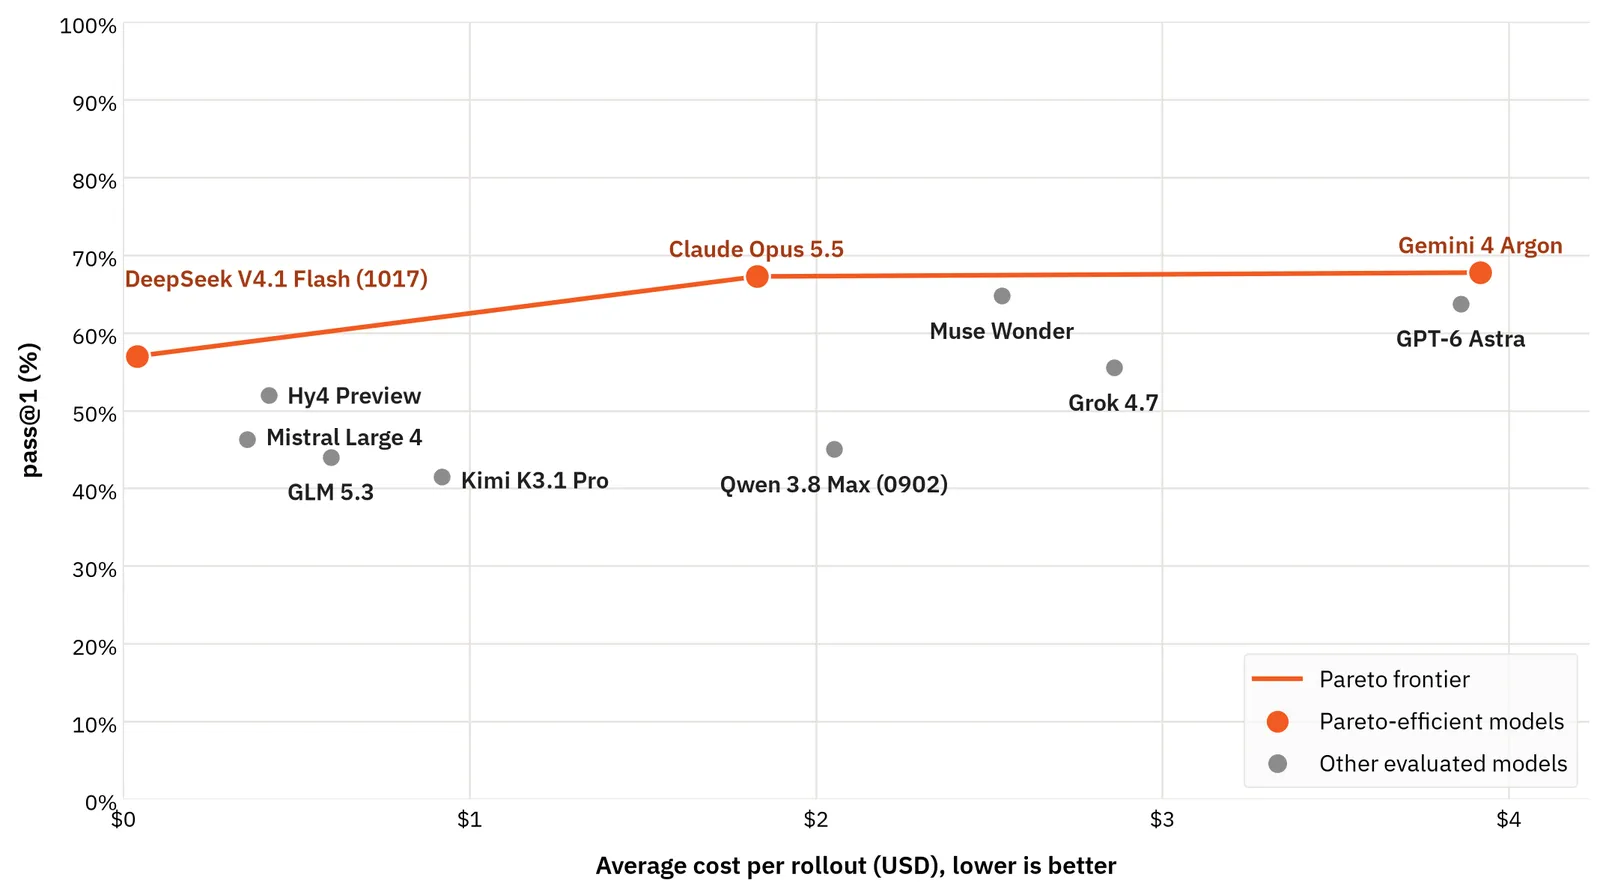
The primary post frames results around three names — DeepSeek V4.1 Flash (1017), Claude Opus 5.5, and Gemini 4 Argon — but the dataset page it links tracks four open-weight entries. The gap between the lowest and highest is 13 points.
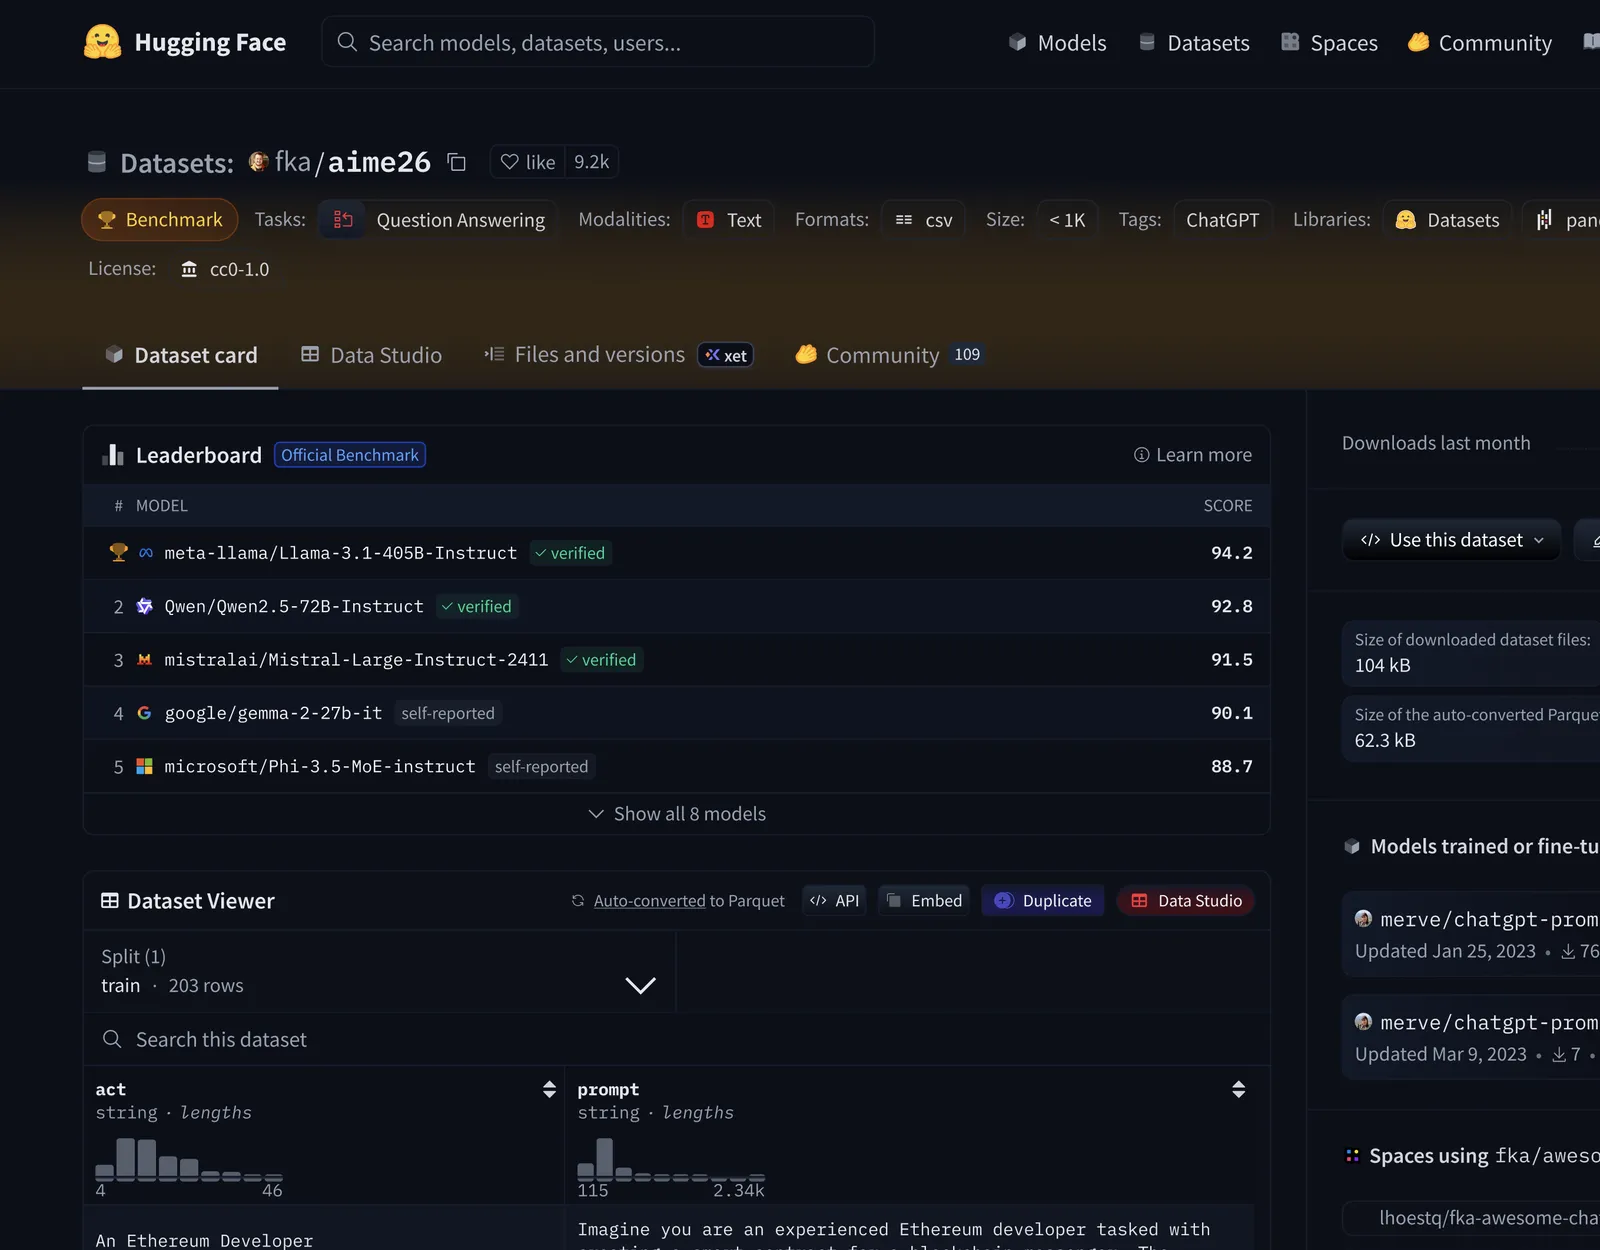
DeepSeek sits at 57, Hy4-preview at 52, Mistral-Large-4-1T-A52B at 46.3, and GLM-5.3 at 44. The blog never names the last three.
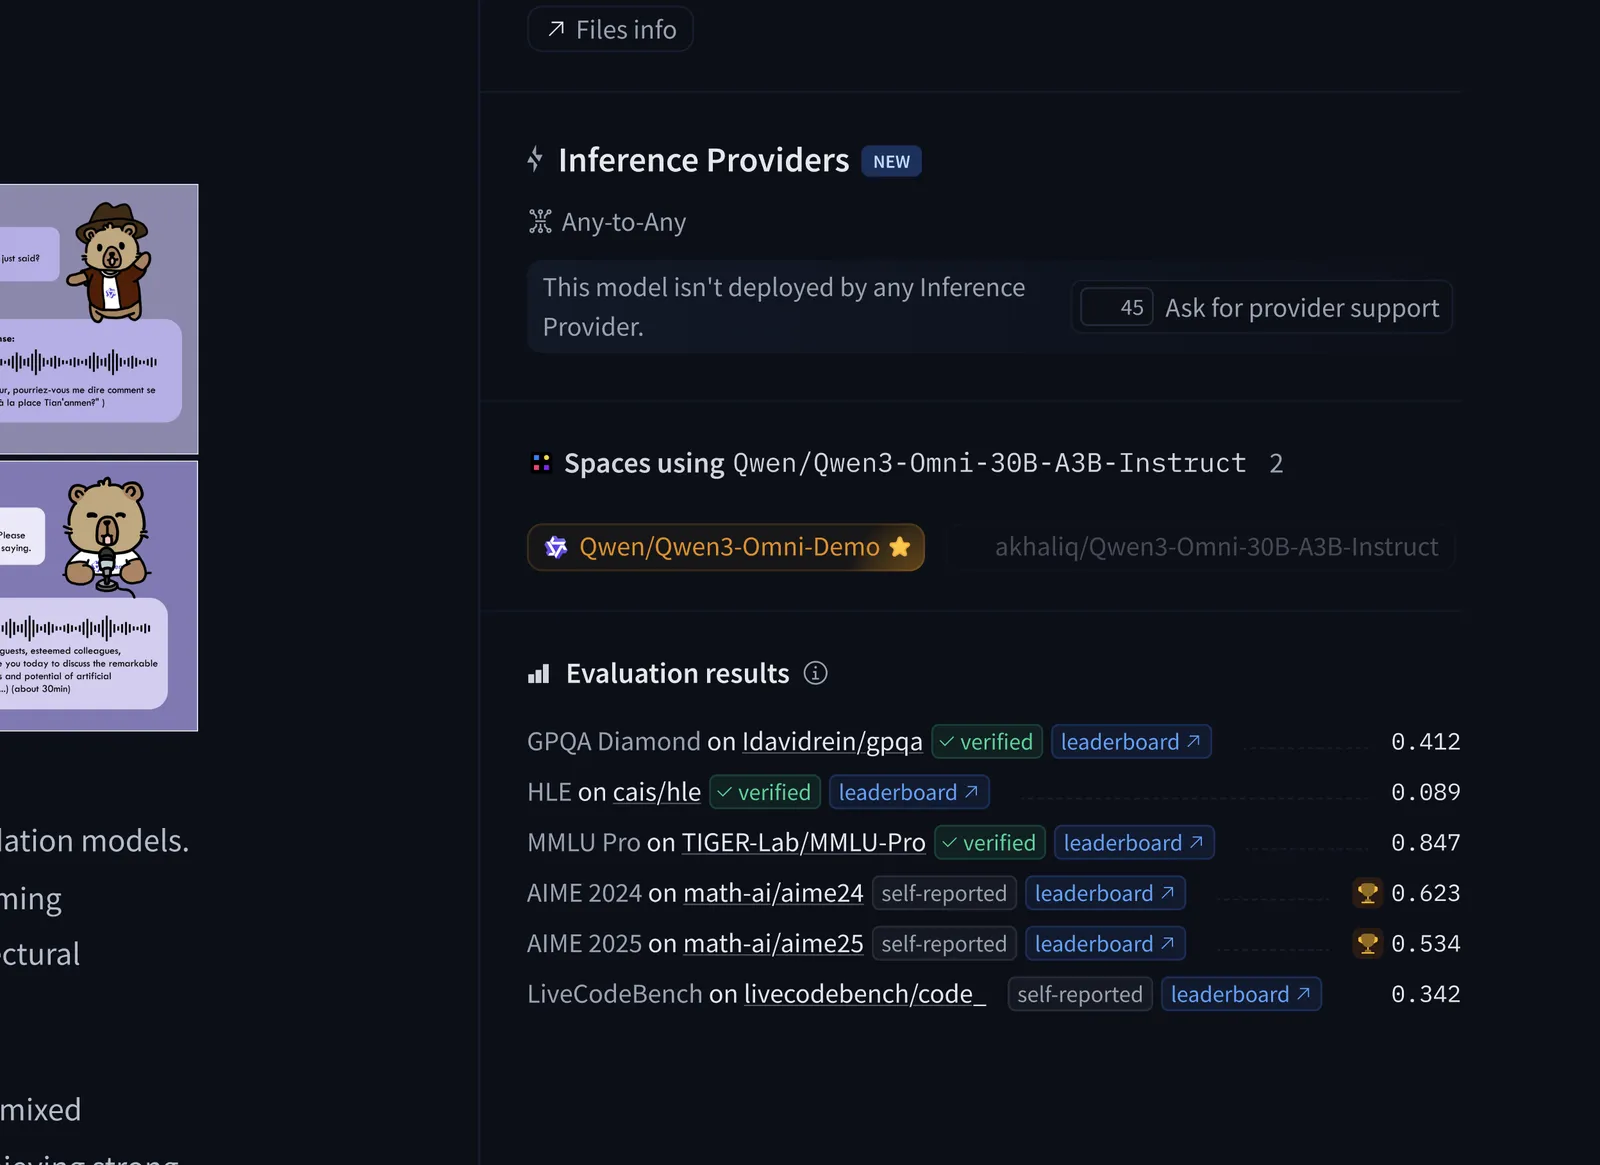
The Pareto frontier the blog highlights is a cost-quality comparison: DeepSeek at $0.04 per rollout, Opus at $1.83, Gemini at $3.92. It does not address the other three open-weight entries.
The held-out set's size and composition appear on no page. The identities and scores of the remaining eight evaluated models are absent. Open-weight entries carry no per-rollout cost.
Hy4-preview's 52 is the number that decides which document to trust. It is the only open-weight score the primary post does not surface, and it sits mid-spread in a field the three-model framing erases.
The dataset page is the document to trust. The 13-point spread it reveals, and the 52 that anchors the middle of it, is the fact the primary post omits.
After huggingface.co. We did not report this. The pictures, if any, are theirs.