NVIDIA's Olympus SMT knob cuts kernel variance, not just throughput
NVIDIA's seventh-revision SMT patch for Vera's Olympus cores adds asymmetric sibling priority, lifting NVPL throughput 6.73 percent and cutting standard deviation by roughly a factor of three.
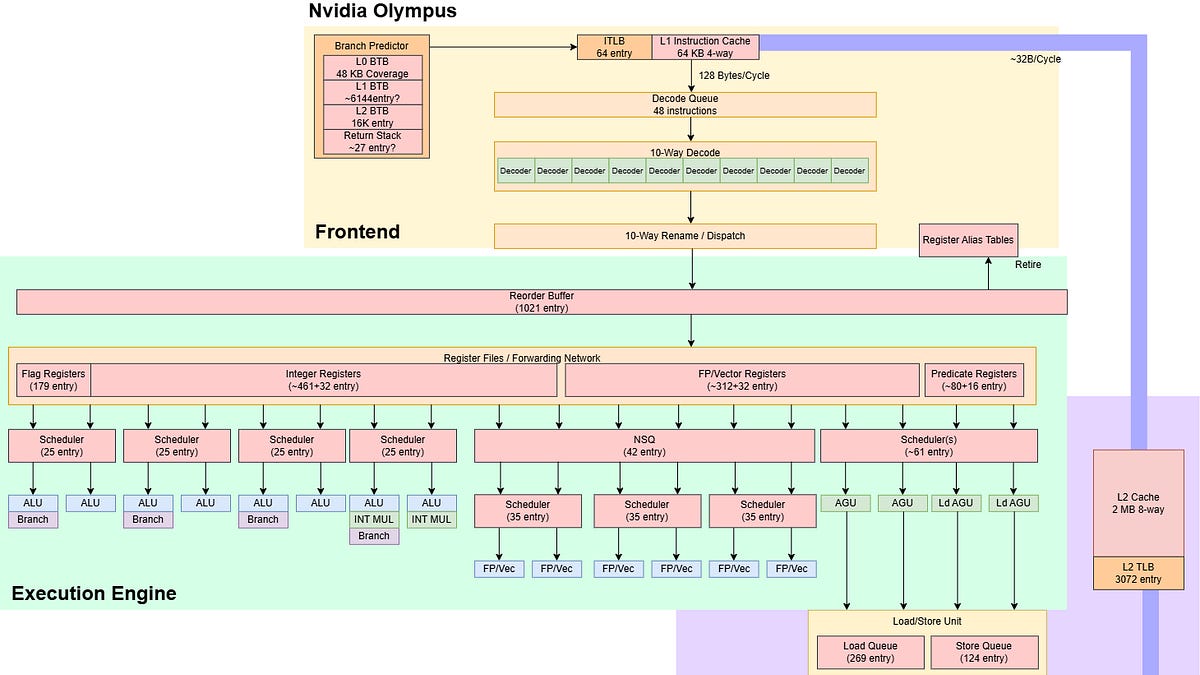
NVIDIA's Olympus cores require a vendor-specific SMT scheduling knob because the two threads per core are not equivalent. The kernel's generic scheduler, which assumes interchangeable siblings, does not handle this.
Andrea Righi's patch series, now at revision seven on the LKML, adds asymmetric SMT priority to the idle-selection code path and introduces a new knob, sched_smt_asym_packing, to force asymmetric packing at the scheduling domain. The entire change is under one hundred lines. It exists for systems where firmware cannot communicate the sibling preference, or where an operator wants to pin policy.
The series notes OpenBLAS throughput rising from 7.11876 to 7.34669 TFLOP/s, a 3.20 percent gain. NVPL throughput moves from 9.64742 to 10.29695 TFLOP/s, up 6.73 percent. Standard deviation on both workloads drops by roughly a factor of three, and the workloads settle consistently on the lower-numbered sibling.
The constraint here is not the silicon; it is the kernel's assumption that SMT siblings are fungible. The document does not prove the gain extends beyond BLAS-class and vendor-library workloads, and it offers no power or thermal data. For a datacenter buyer running NVIDIA's own stack, the 6.73 percent on NVPL is the operative number, because that is the library shipped with the hardware. The standard-deviation reduction matters more than the mean shift for HPC scheduling, where a 0.17 TFLOP/s swing in the baseline becomes a 0.018 TFLOP/s swing after the patch.
Routing this through mainline rather than a vendor fork signals that Vera is meant to run on stock distro kernels. That is a competitive statement aimed at AMD EPYC and Intel Xeon, whose SMT implementations have been in the kernel for a decade without a vendor-specific knob. The threat is not raw throughput; it is the predictability argument. A scheduler that pins work to one sibling and cuts variance by an order of magnitude changes the case for batch HPC jobs.
What the series does not measure: mixed-workload contention, power draw under the asymmetric policy, or head-to-head comparison against AMD or Intel SMT on comparable cores. Whether the patch lands in Linux 7.4 remains open. Phoronix has indicated further Vera SMT on/off benchmarks are coming, and those will be the first independent check on whether the 3-to-6 percent window holds outside NVIDIA's own test suite.
The constraint is the kernel's fungibility assumption, not the silicon, and the document does not prove the gain extends beyond BLAS-class workloads. For a datacenter buyer on NVIDIA's own stack, the 6.73 percent NVPL gain and the order-of-magnitude variance reduction are the numbers that change the procurement case.
The patch breaks the kernel's assumption that SMT siblings are interchangeable by pinning work to the lower-numbered sibling via sched_smt_asym_packing. The 0.17 to 0.018 TFLOP/s standard-deviation drop on NVPL is the architecturally significant result; the 6.73 percent mean shift is secondary for HPC scheduling.
OpenBLAS: 7.11876 to 7.34669 TFLOP/s (+3.20%) · NVPL: 9.64742 to 10.29695 TFLOP/s (+6.73%) · sched_smt_asym_packing knob, under 100 lines · Patch series at revision 7, targeting mainline
After lore.kernel.org. We did not report this. The pictures, if any, are theirs.