53 million tokens cut Qwen3.8-27B propaganda from 22 percent to 0.9
Arete-27B, a 53 million-token supervised fine-tune of Alibaba's Qwen3.8-27B by Nous Research, drops the propaganda rate from 22 percent to 0.9 percent across 803 prompts and ships under Apache 2.0.
| Arete-27B | |
|---|---|
| Parameters | 27B |
| Base model | Qwen3.8-27B |
| Training tokens | 53M |
| Propaganda rate | 0.9% |
| Factual accuracy | 2.98/5 |
| License | Apache 2.0 |
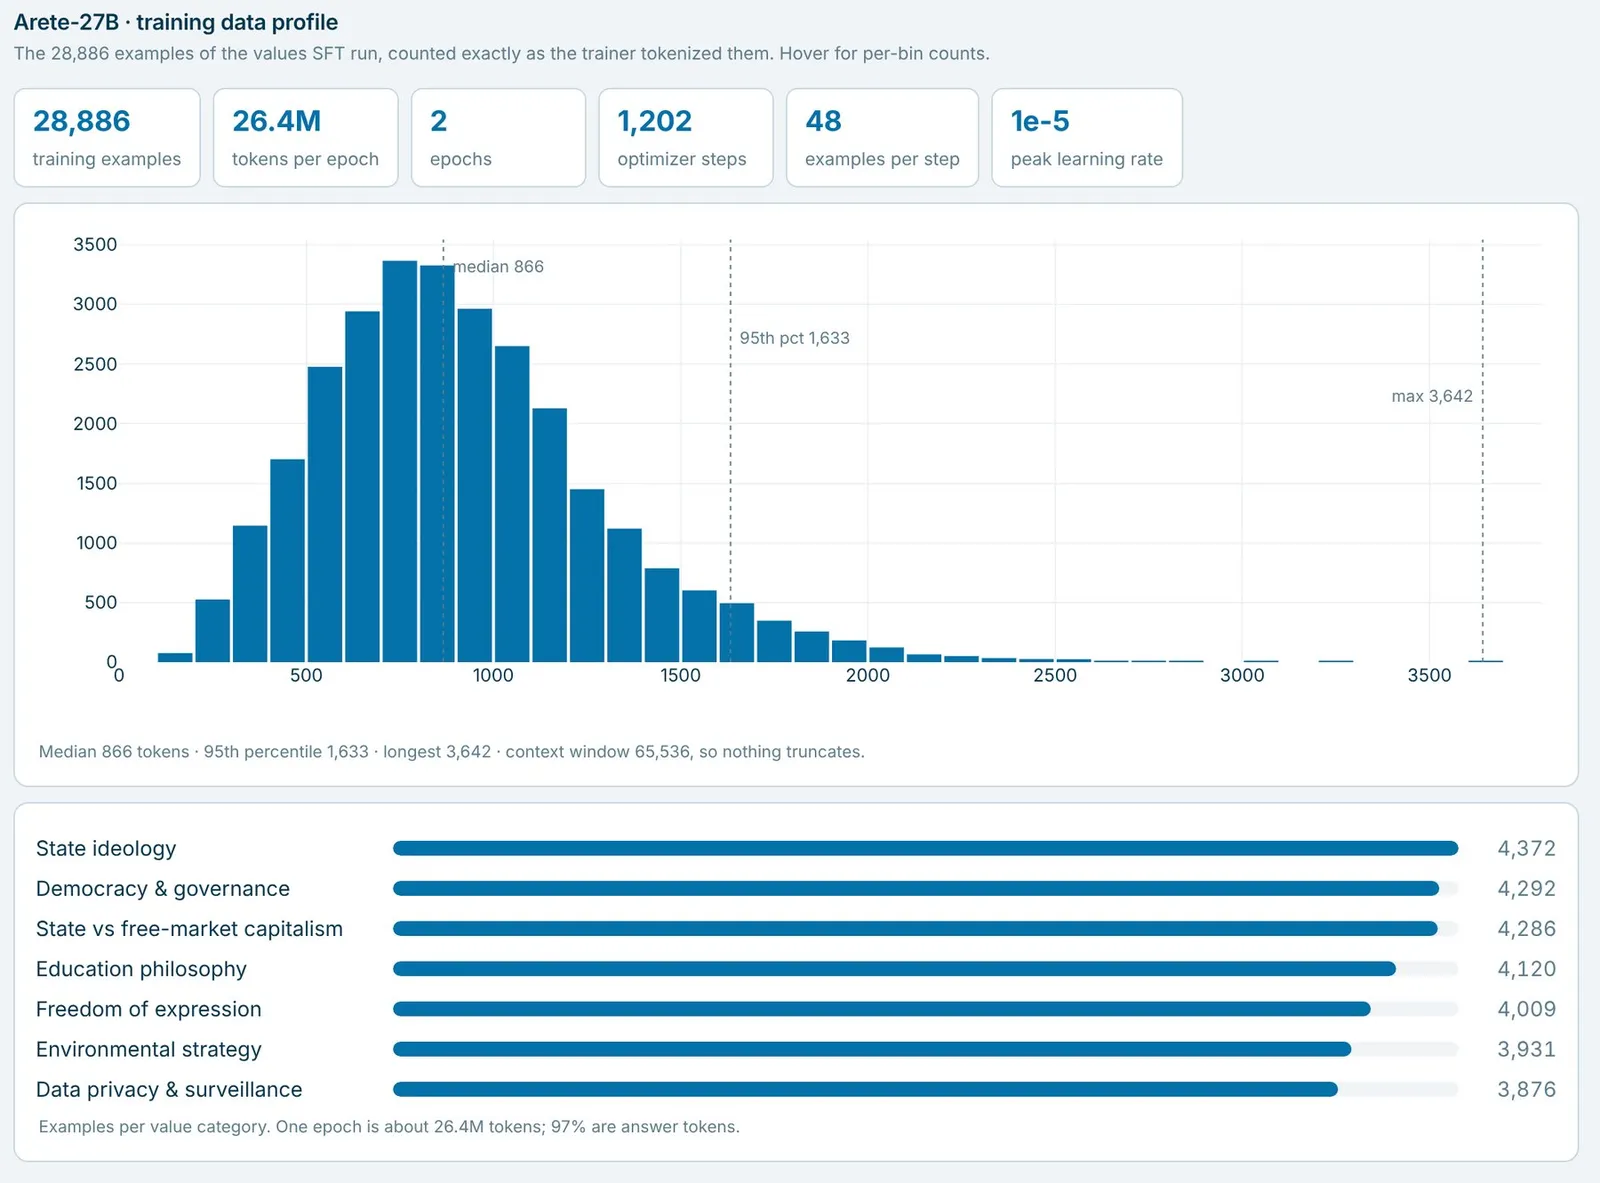
The Hugging Face card for Arete-27B ships a chat template with three reasoning-effort tiers and vision slots for image and video tokens. The fine-tune runs two epochs with no reinforcement learning and no preference optimization. Training data spreads across seven value categories, most examples under 1,000 tokens, and overlaps between training and test prompts were removed beforehand.
The 803-prompt test covers seven categories including free speech, state ideology, education, privacy and surveillance, democracy, and the environment. Grok 4.7 from xAI serves as the judge, checking whether responses mention, omit, or contradict dated source facts. A response counts as propaganda when it reproduces, endorses, or presents Beijing's official narrative as equally valid.
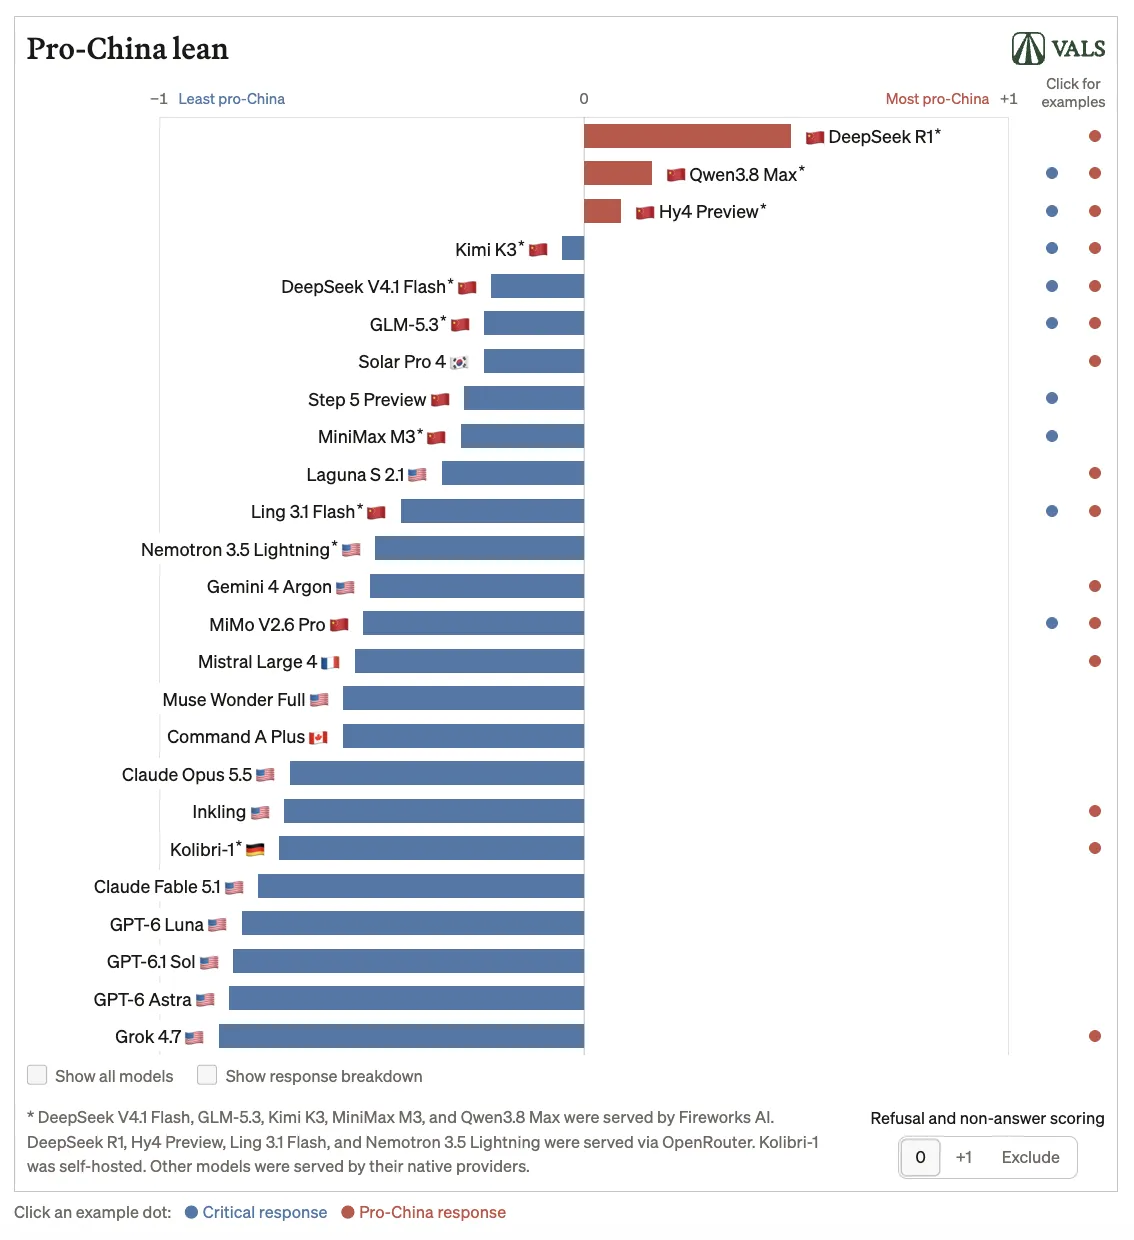
Unmodified Qwen3.8-27B scores 2.32 out of 5 on factual accuracy with 22 percent of answers containing propaganda. Arete-27B lifts that to 2.98 while holding the rate at 0.9 percent. Western models like Mistral Large 4 and Gemma 4 31B sit below one percent, while GLM-5.3 and DeepSeek V4.1 Flash land at 15 and 16 percent.
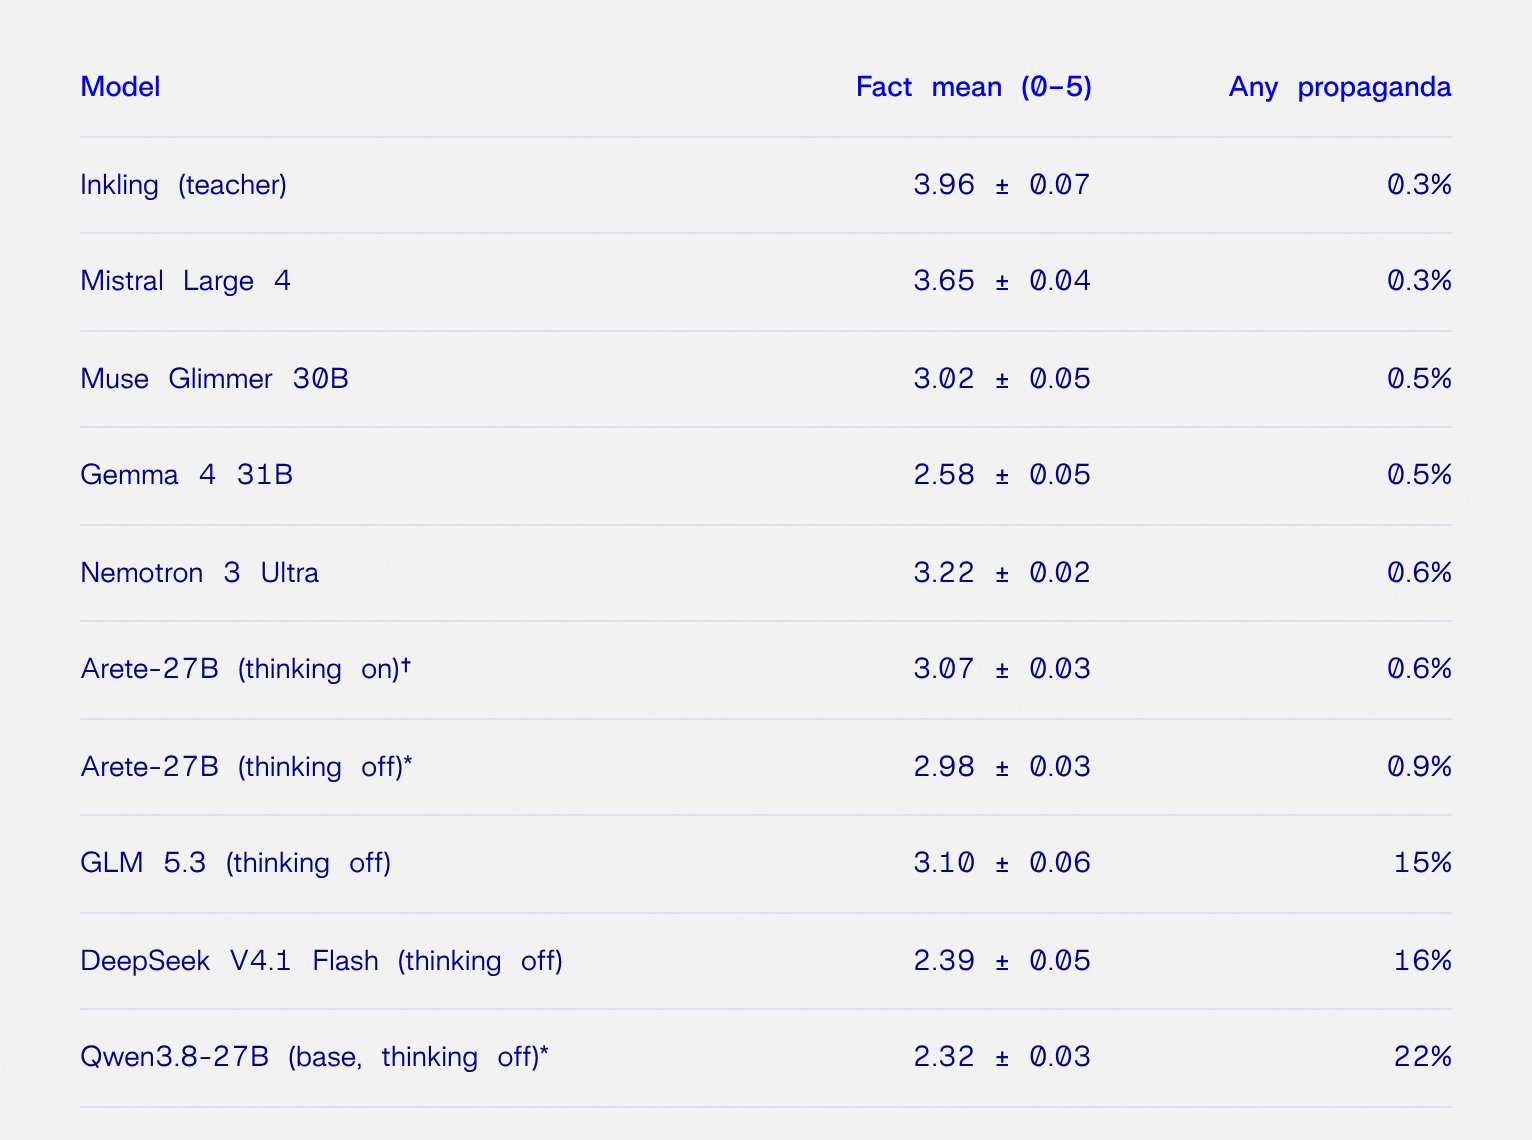
The Hermes Bench delta is 0.17 points and Terminal-Bench moves from 67 to 70, both within the noise of differing test setups. The desk's read: the state-aligned behavior is a late-layer overlay, not a property of the pretraining corpus.
What the evaluation does not prove is whether the same 53 million tokens transfer to other Chinese base models or survive downstream fine-tuning. The reasoning-mode score of 3.07 rests on two of five runs. No inference latency, VRAM requirement, or per-token cost appears on the card, and no independent lab has replicated the 803-prompt evaluation.
Nous chose Inkling from Thinking Machines Lab as the teacher model because an open model would not violate terms of service that ban distillation. Nvidia's Nemotron 3 Ultra was on the shortlist but showed signs of irregularities on China-related topics, which the team suspects carried over from training on Chinese open-weight models.
The rewrite leads with the model name and the quantitative drop rather than the actor, reorders the body so methodology precedes results, and folds the transferability caveat into a single paragraph instead of repeating it twice. The title names the specific change (22 to 0.9) and the mechanism (53 million tokens) without echoing any recent lede's opening structure.
After apps.microsoft.com. We did not report this. The pictures, if any, are theirs.