ALTK-Evolve's learned guidelines lift GPT-4.1 retail Pass^4
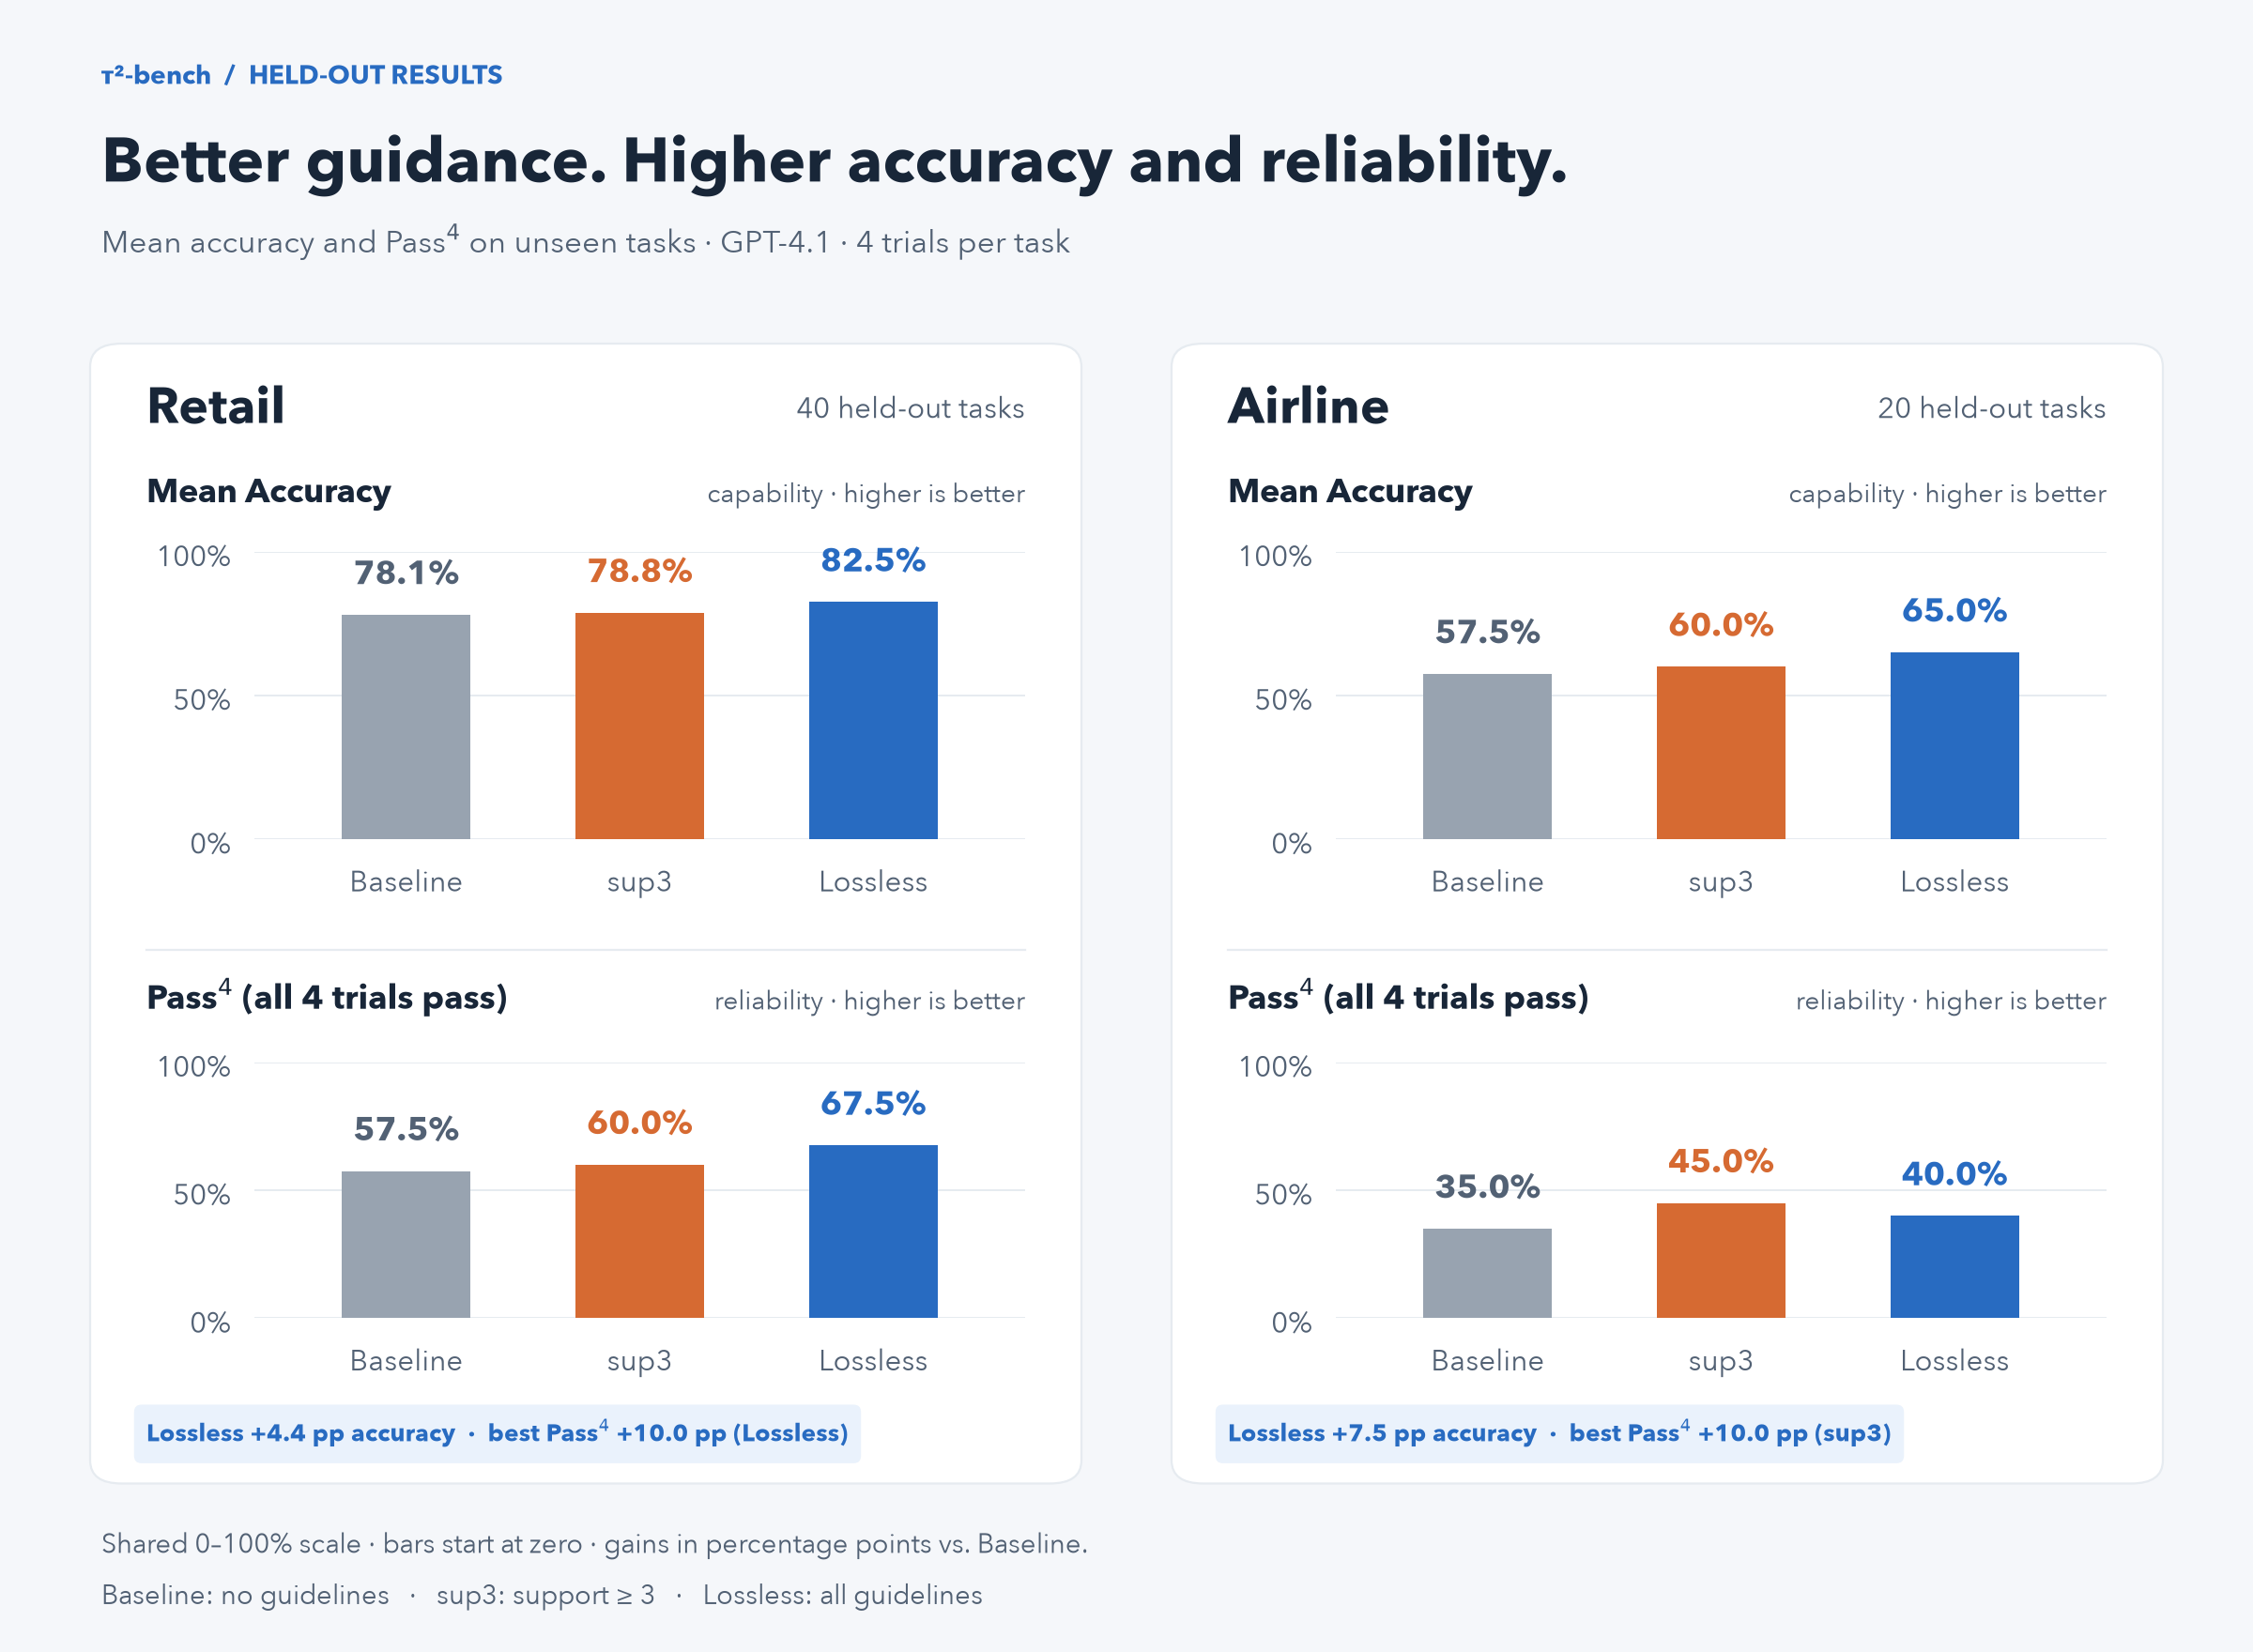
A stock ReAct GPT-4.1 agent reports 67.5 percent Pass^4 on τ²-bench retail after learned guidelines are appended to its prompt, above every retail entry in the snapshot.
| baseline | sup3 | lossless | |
|---|---|---|---|
| Retail Pass^4 | 57.5% | 60.0% | 67.5% |
| Retail Mean Accuracy | 78.1% | 78.8% | 82.5% |
| Airline Pass^4 | 35.0% | 45.0% | 40.0% |
| Airline Mean Accuracy | 57.5% | 60.0% | 65.0% |
| Retail cost/conversation | $0.084 | $0.095 | $0.139 |
| Airline cost/conversation | $0.081 | $0.097 | $0.107 |
| Retail guidelines | 0 | 31 | 292 |
| Airline guidelines | 0 | 14 | 101 |
The change is prompt-side. The agent keeps GPT-4.1 weights, and the only edit is a markdown list of learned guidelines after the domain policy.
The retail gain moves from 57.5 to 67.5 Pass^4. The airline gain moves from 35.0 to 45.0, but the compact sup3 core is more reliable than lossless.
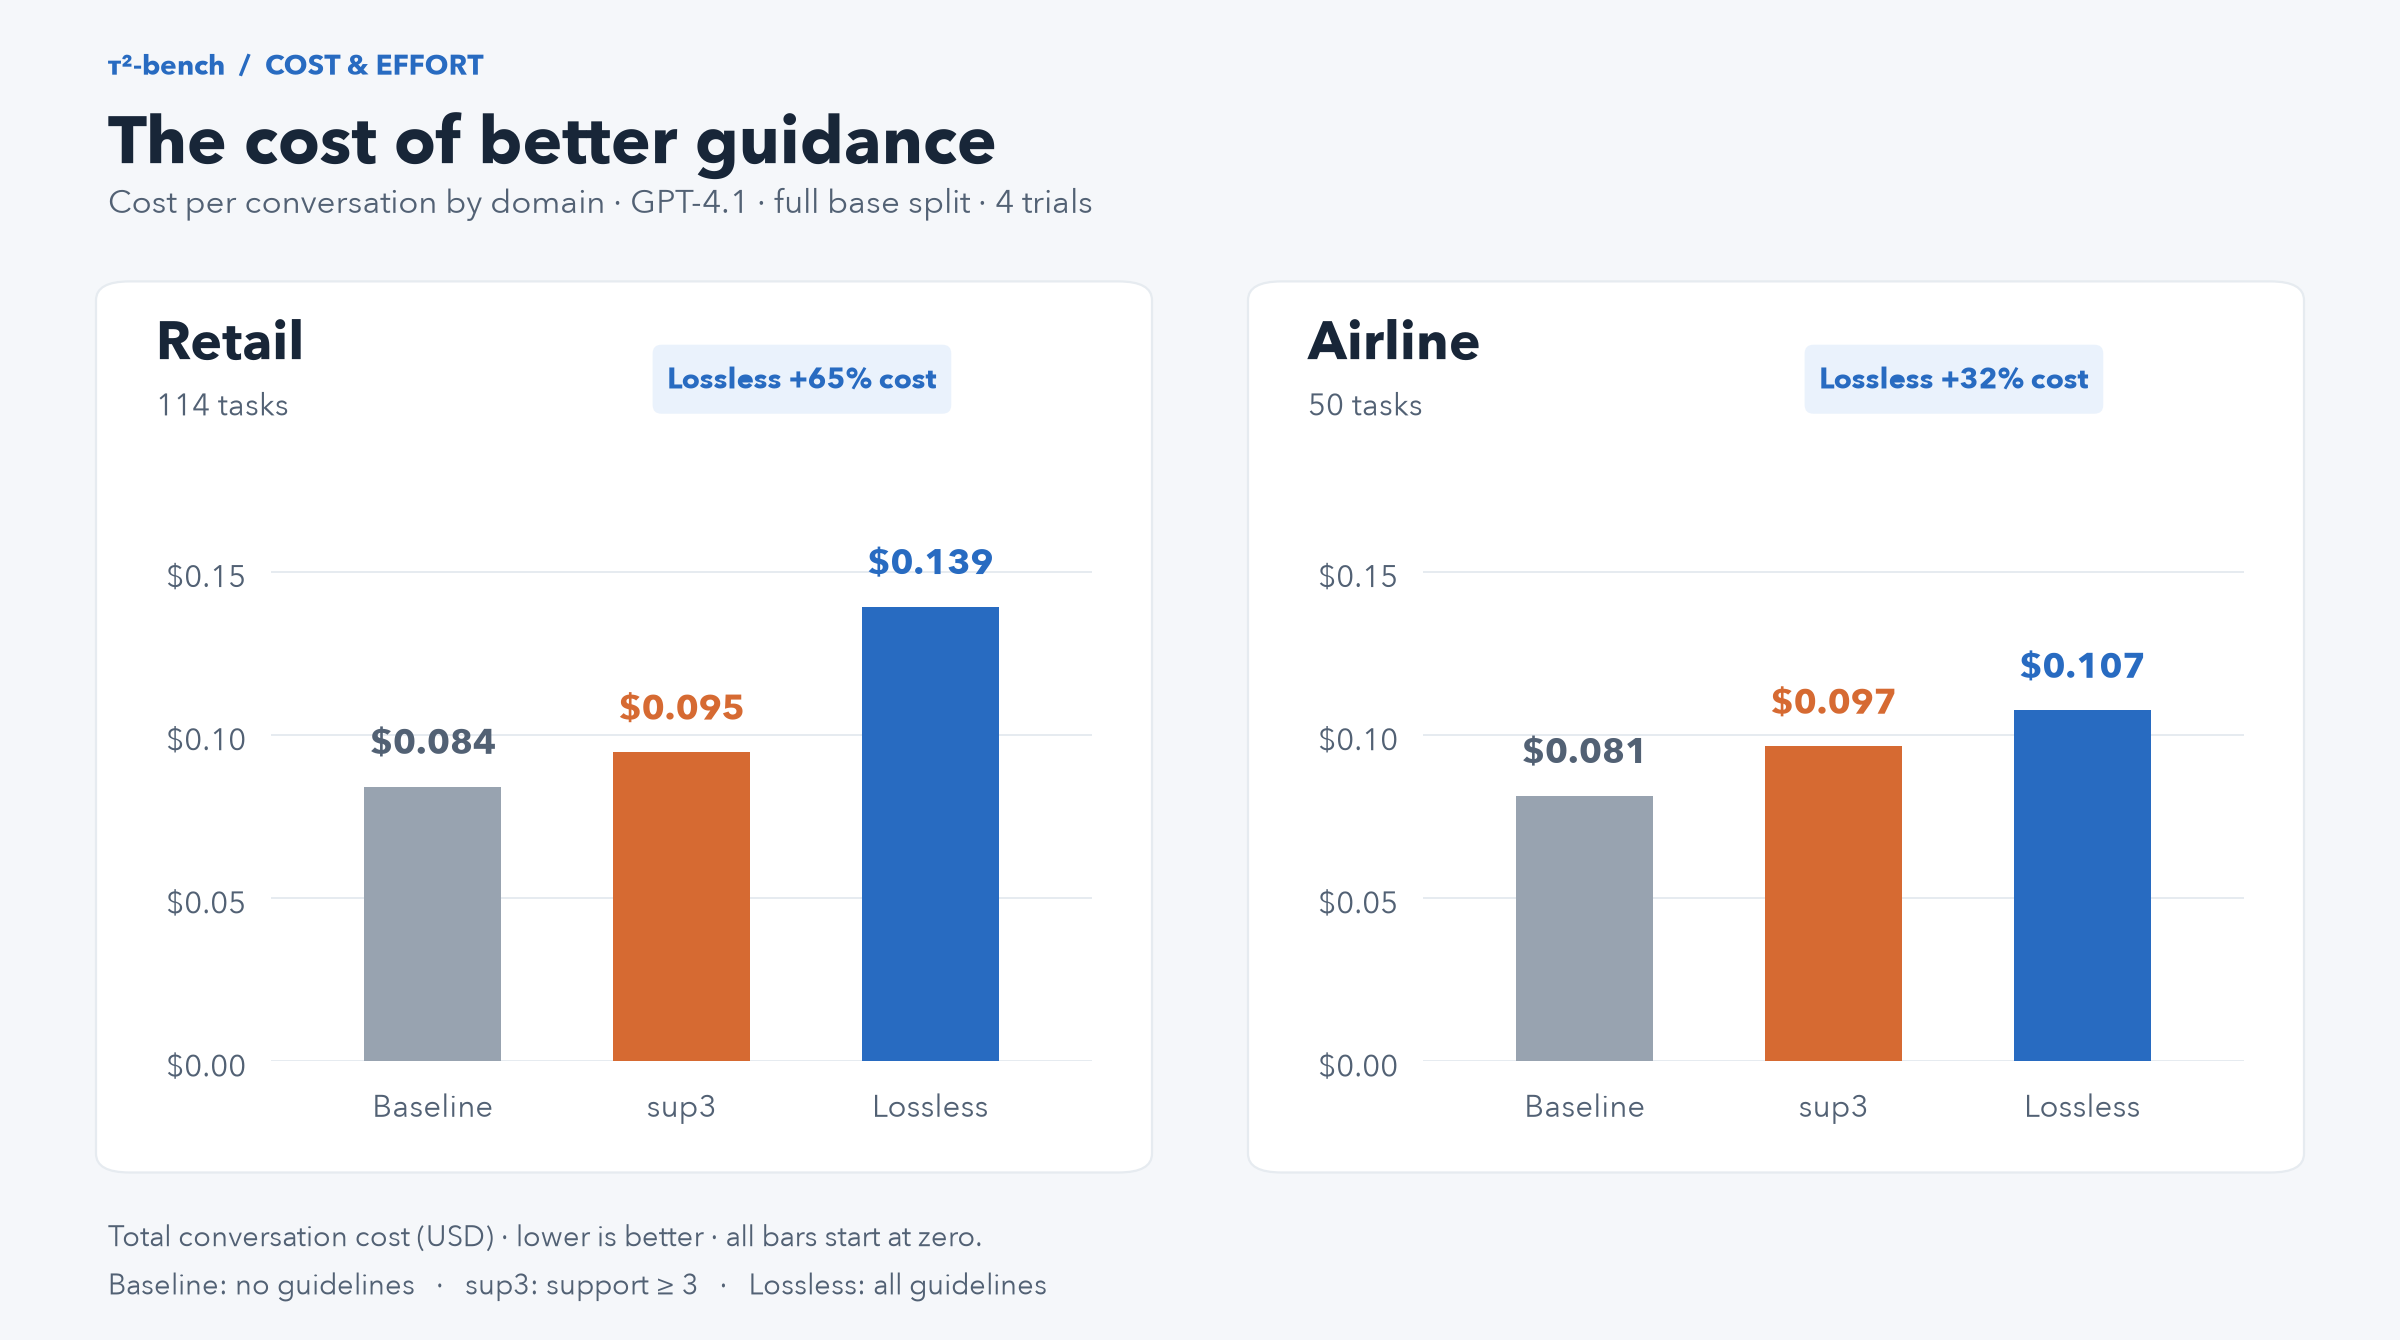
Retail cost rises from $0.084 to $0.139 per conversation. The buyer inherits prompt maintenance, input-token cost, and per-domain tuning rather than a new model class.
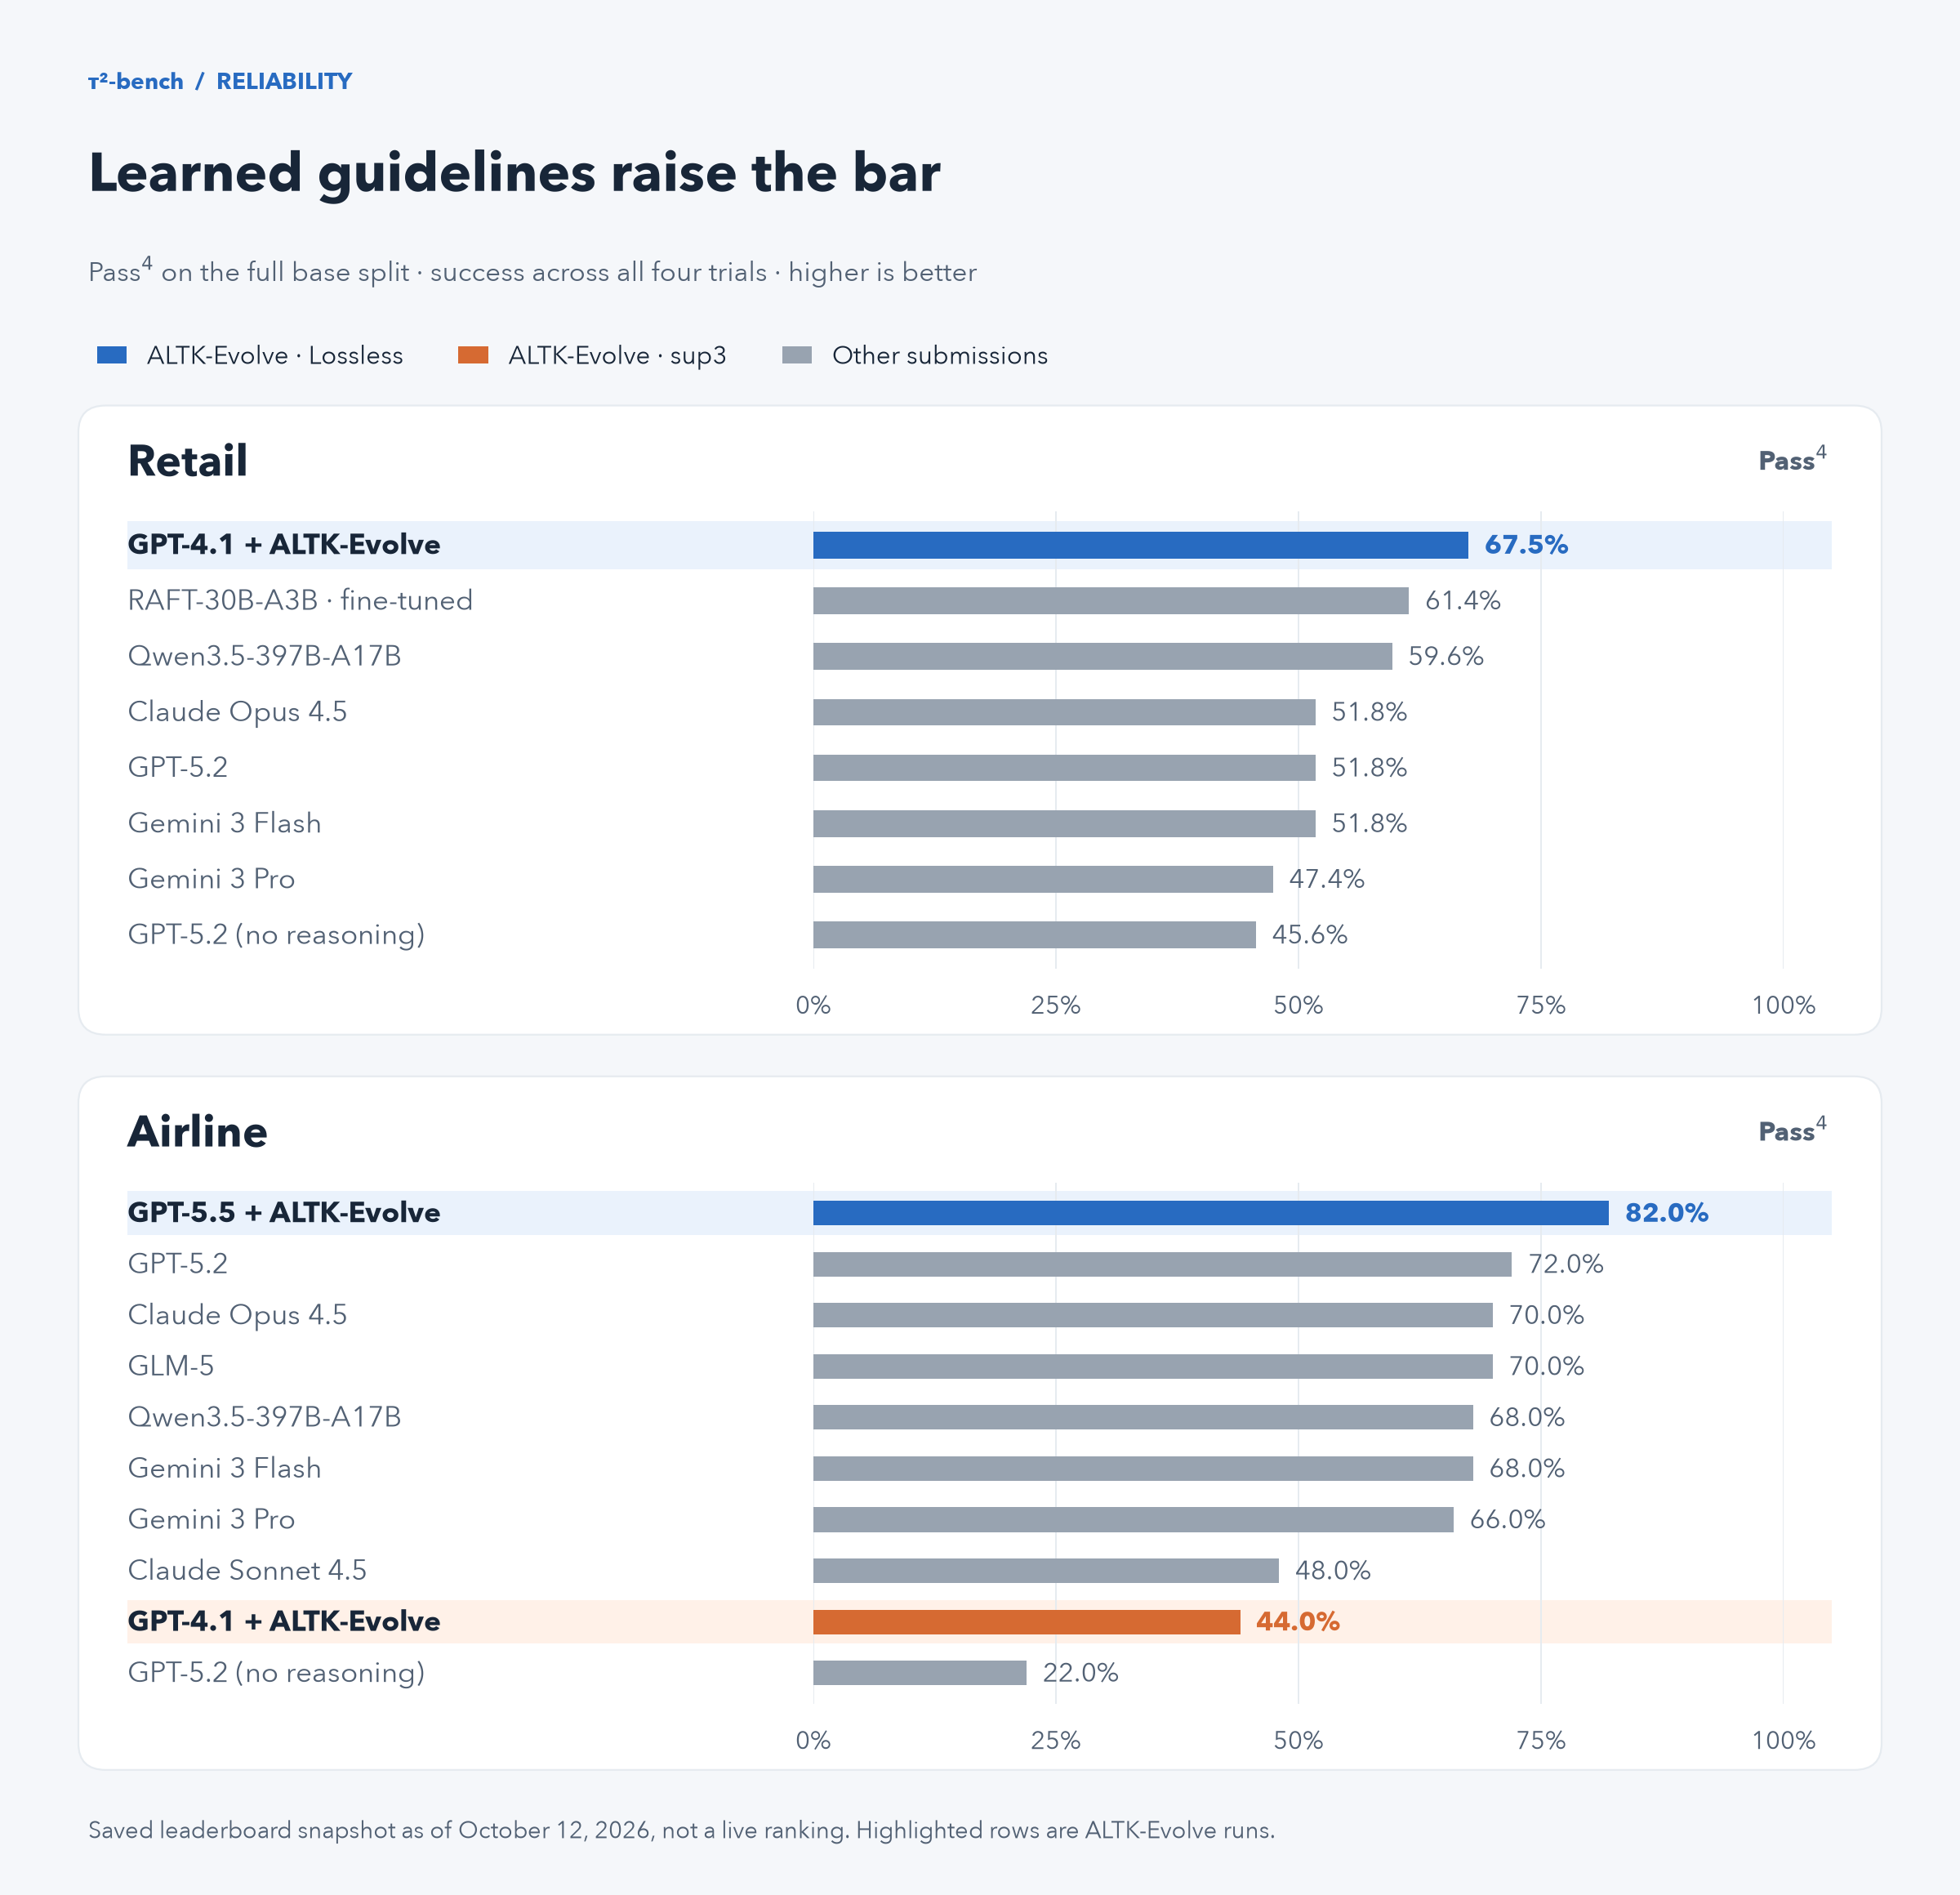
The page does not test whether the mined rules survive outside τ²-bench policies. It also does not measure independent reruns, prompt caching, live latency, or production failure costs.
The useful lever is reliability without weight updates. The gain is domain-shaped and costs more input tokens.
The change is a prompt-level reliability lever, not a production proof.
After huggingface.co. We did not report this. The pictures, if any, are theirs.