Muse Wonder Full joins the agentic top tier
Muse Code subscribers get the agent model that Meta calls its most capable.
| Muse Wonder Full (max) | |
|---|---|
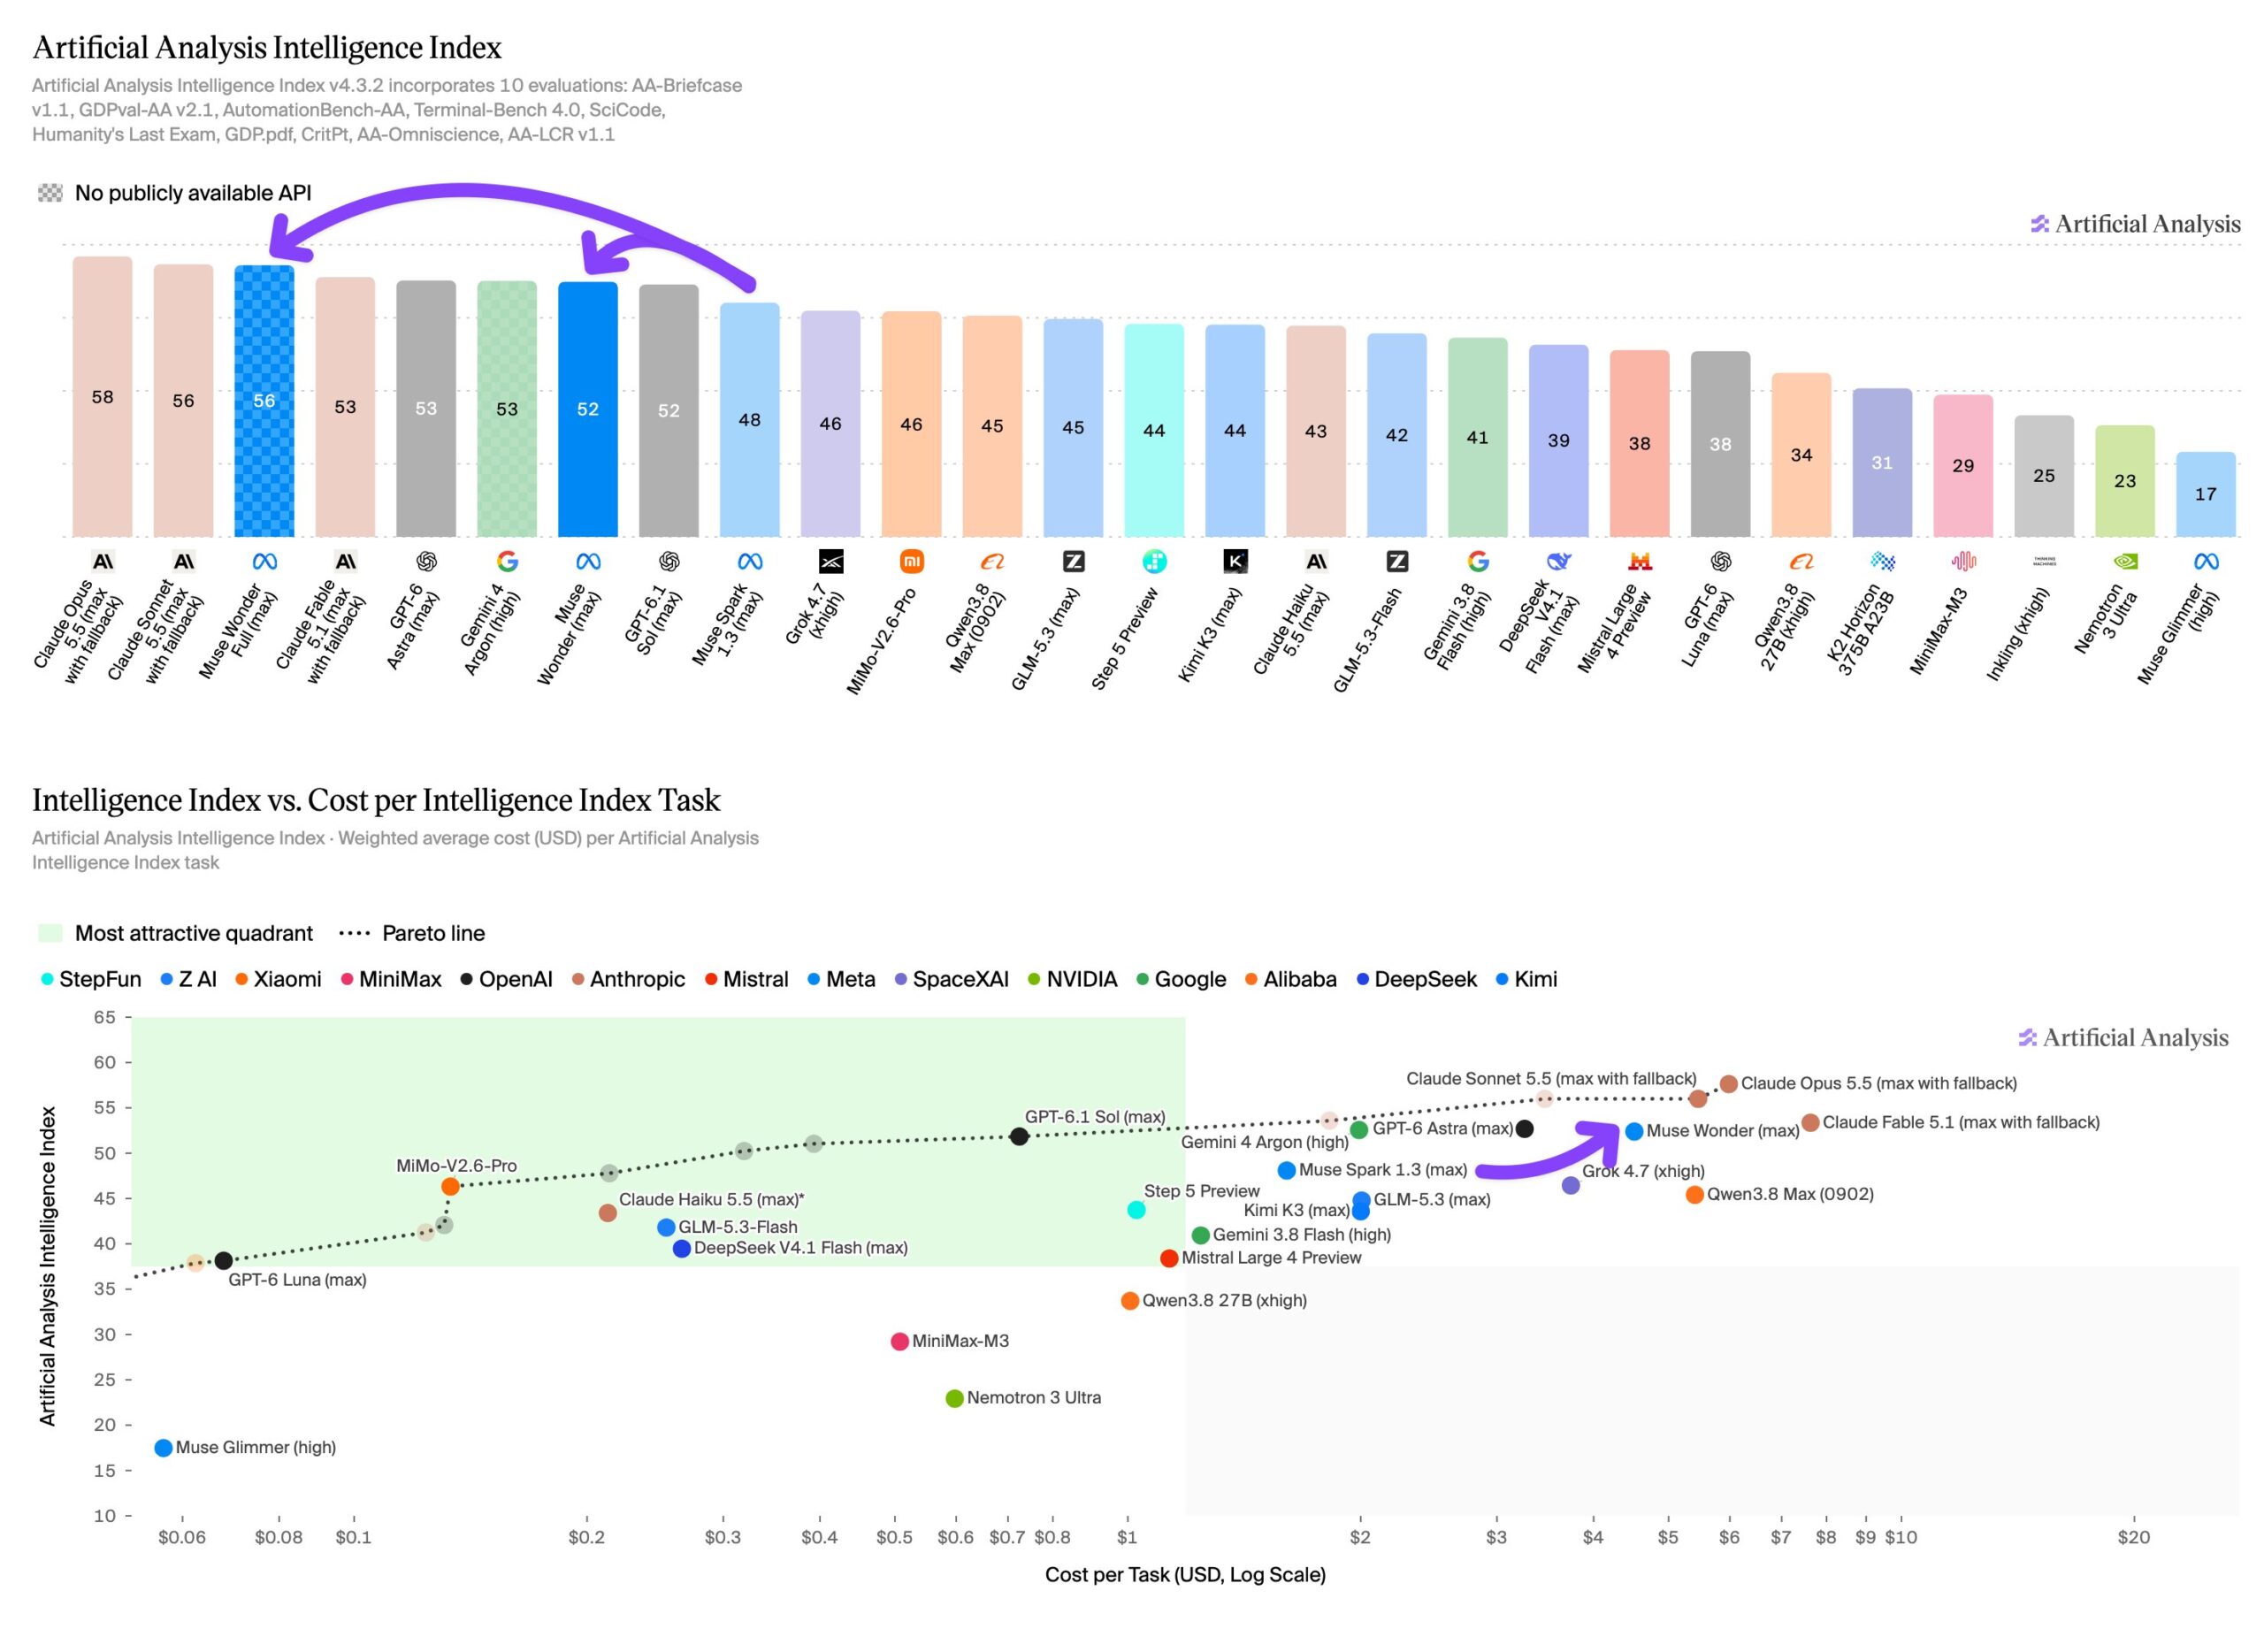
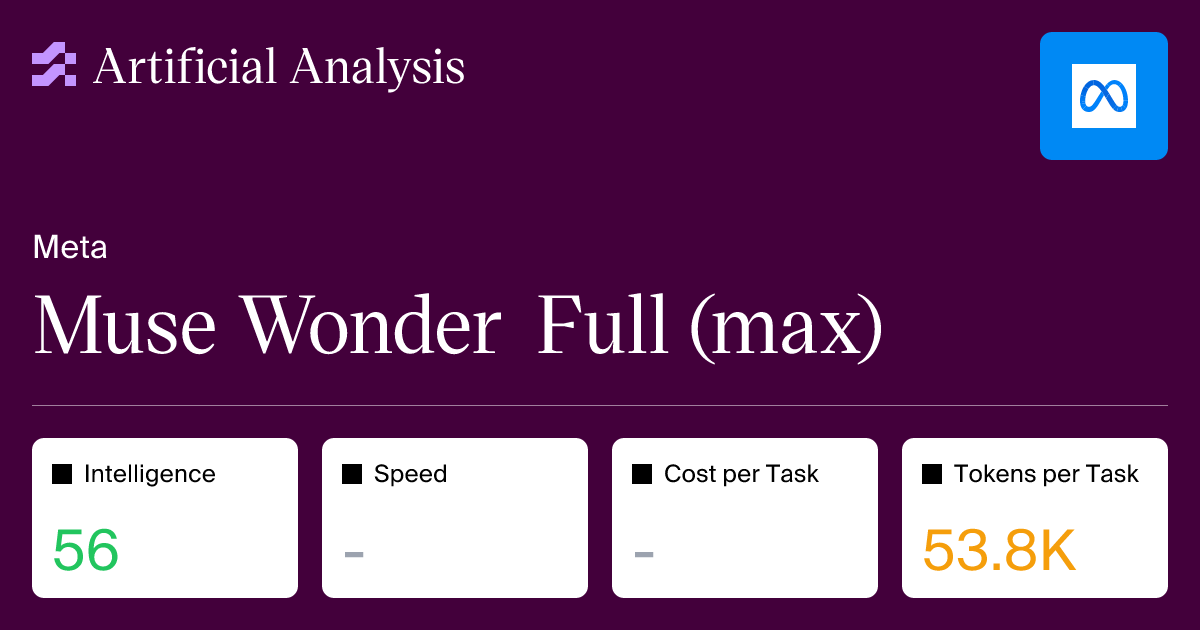
| Artificial Analysis Intelligence Index | 56 |
| Intelligence rank | 4 / 690 |
| Context window | 1M tokens |
| Input modalities | text, image, speech, video |
| Output | text |
| Verbosity | 140M output tokens |
The model is built for personal and professional agentic work, from insurance claims to leases to working apps.
Muse Code subscribers can use Muse Wonder Full now.
Active Memory and Active Focus let the model carry relevant details and keep working through hard tasks.
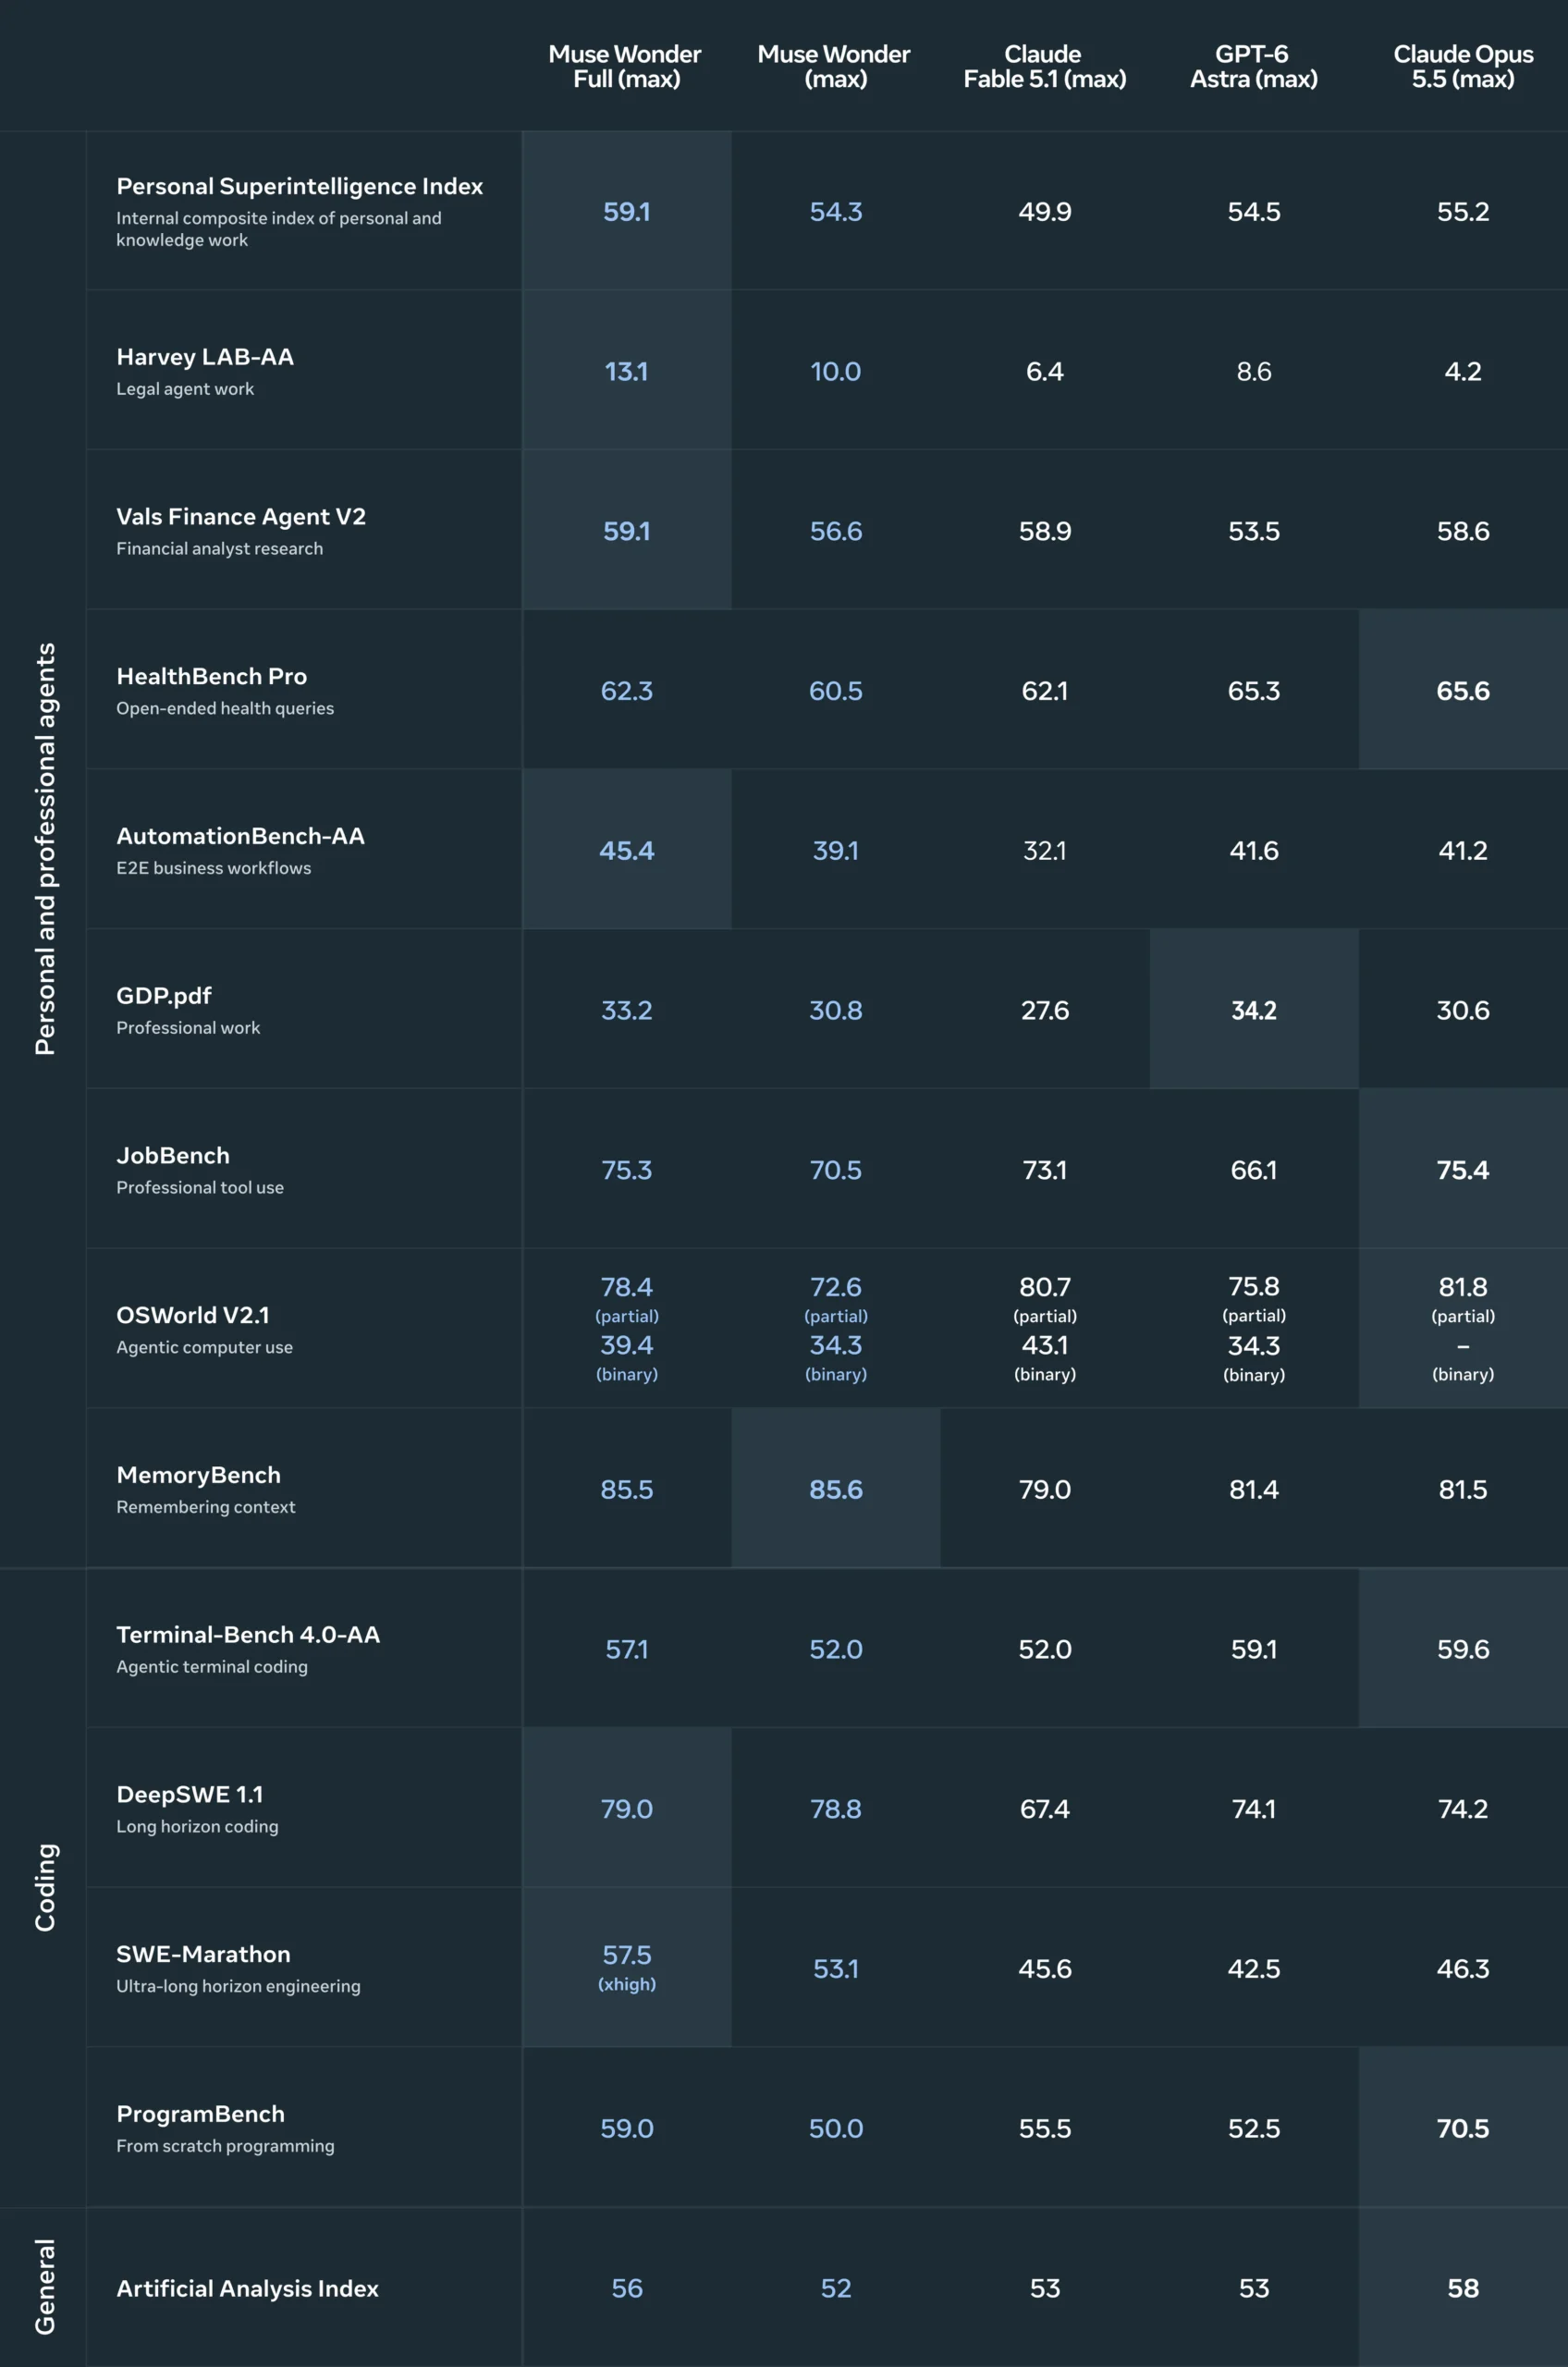
The visible page offers a video and a benchmark table, but no image of the model itself.
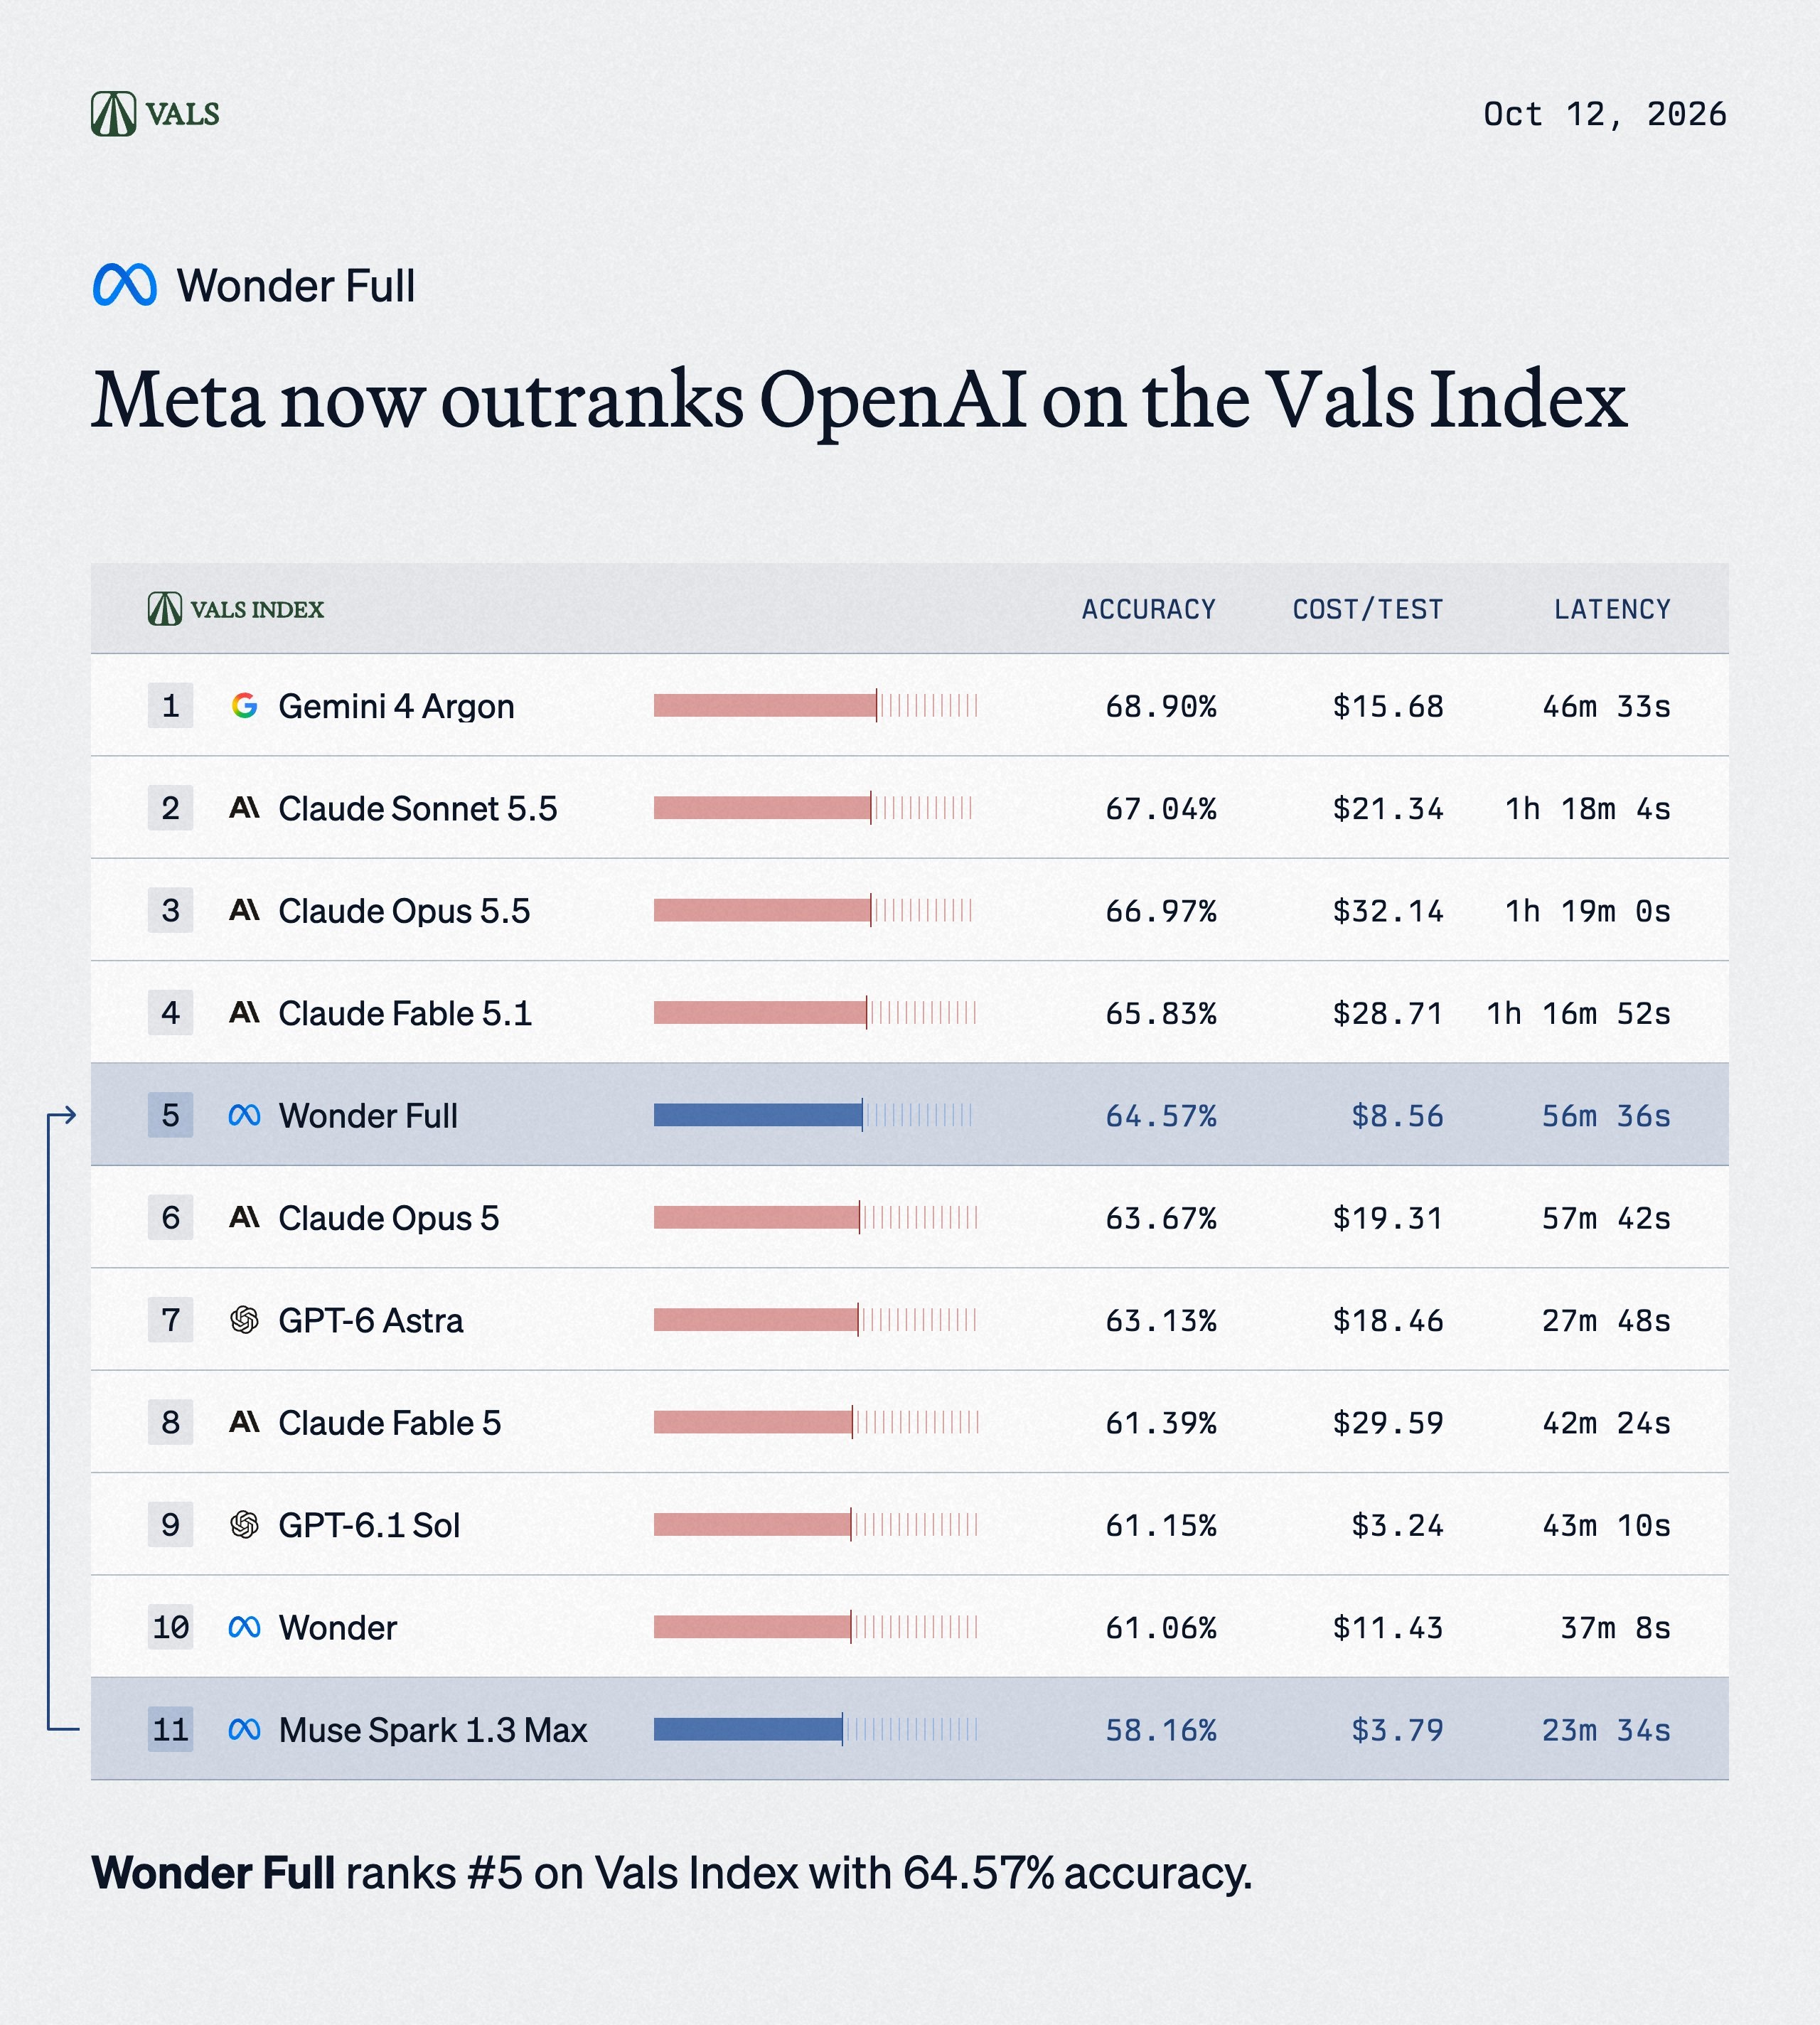
Artificial Analysis ranks Muse Wonder Full (max) fourth of 690 models and places it at 56 on the Intelligence Index.
The same page lists text, image, speech, and video input, with text output and no measured speed or cost.
The context window reaches one million tokens.
Muse Wonder scores 52, and the earlier Muse Spark 1.3 sat at 48.
Terminal-Bench 4.0 moved from 33 to 57 percent.
The buyer still faces missing economics: no API price, no output speed, and no training compute figure.
The 56 score is not shown to hold outside Meta's chosen tasks.
No node, no power, and no price appear in the packet.
The useful change is a one-million-token agent model, while the fab-side consequence stays thin.
The useful change is a one-million-token agent model, but the economic cost and independent verification remain unmeasured.
After @ValsAI. We did not report this. The pictures, if any, are theirs.